Taming Giants: Serving DeepSeek-R1–70B Across Dual NVIDIA DGX Spark Nodes
A deep dive into configuring vLLM, Pipeline Parallelism, and high-speed networking, featuring the crucial role of Gemini in navigating…
Taming Giants: Serving DeepSeek-R1–70B Across Dual NVIDIA DGX Spark Nodes

Two Sparks fit nicely on top of a small Cubby Organizer
A deep dive into configuring vLLM, Pipeline Parallelism, and high-speed networking, featuring the crucial role of Gemini in navigating complex infrastructure setups.
This is the “special sauce” for your Medium article. These sections provide the deep-dive technical substance that will make the post go viral among AI infrastructure nerds.
Section 1: Breaking the VRAM Myth with Unified Memory
How the GB10 Grace Blackwell Superchip Redefines Local Inference
For years, the rule for running Large Language Models was simple: “If it doesn’t fit in the GPU’s dedicated VRAM, it doesn’t run.” This bottleneck meant that to serve a 70B model like DeepSeek-R1 (which requires ~140GB in FP16), you needed at least two 80GB A100s or H100s, usually housed in a massive, noisy rack-mount server.
The NVIDIA DGX Spark changes the game through the GB10 Grace Blackwell Superchip.1 Unlike traditional setups where the GPU and CPU are separated by the relatively slow PCIe bus, the GB10 uses NVLink-C2C.2
- The Coherent Pool: The GB10 features 128GB of LPDDR5x unified memory.3 This isn’t just “system RAM”; it is a single, coherent memory space shared at high bandwidth between the 20-core Arm CPU and the Blackwell GPU.4
- Capacity Over Cost: By linking two DGX Spark units, we aren’t just doubling compute; we are creating a 256GB unified memory pool.
- Why this matters for 70B Models: With 256GB, you can load the entire 70B model and still have roughly 100GB remaining for the KV Cache. This allows for massive context windows (up to 32k or even 128k tokens) that would be physically impossible on a standard dual-GPU setup with 48GB or 80GB cards.
Section 2: Solving the “World Size” Mystery
When Multiprocessing Fails and Ray Saves the Day
One of the most valuable lessons from this build occurred during the initial vLLM launch. On paper, the command looked perfect, but we immediately hit a wall:
*ValidationError: World size (2) is larger than the number of available GPUs (1) in this node.*
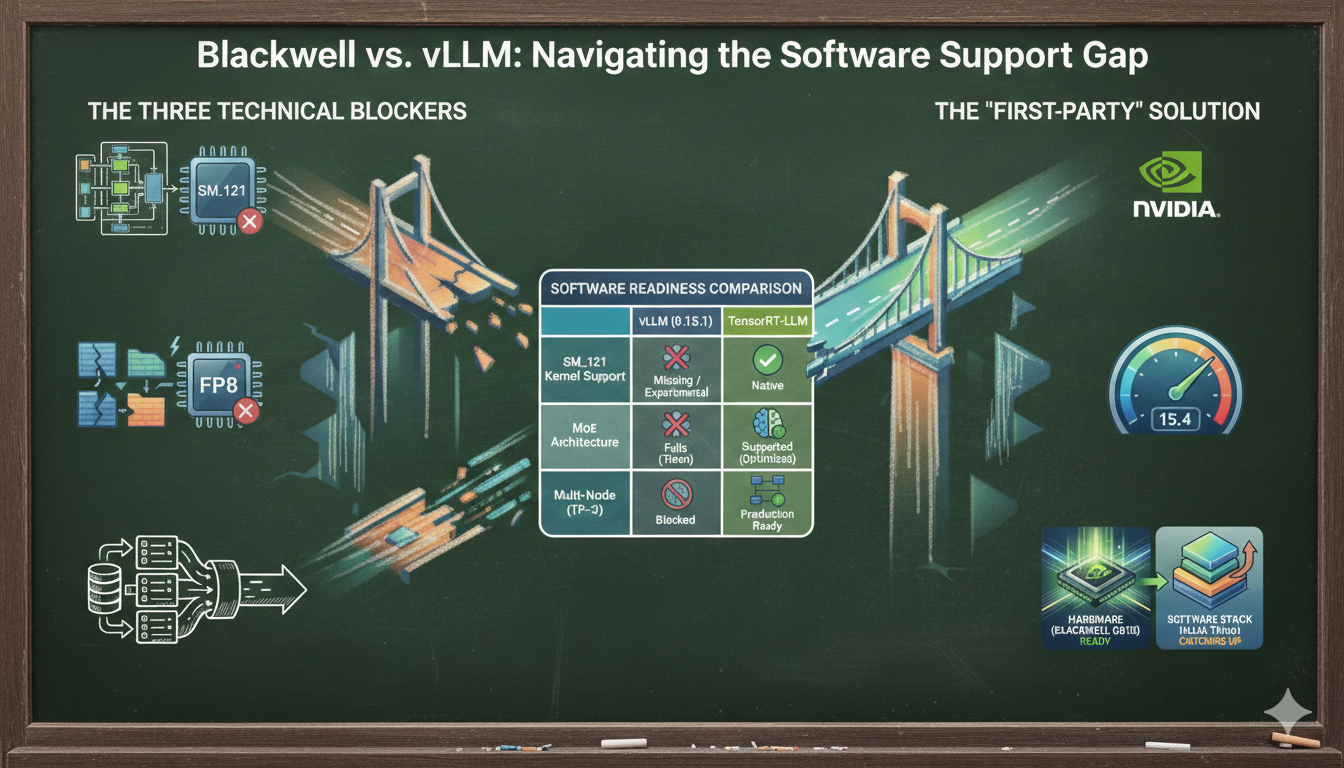
This error is a rite of passage for distributed inference. By default, vLLM uses a multiprocessing backend designed for single-node machines with multiple GPUs (like an A100–80GB x8).5 When it saw our request for a pipeline_parallel_size 2, it looked for two GPUs on the head node, found only one, and crashed.
The Fix: We had to pivot to Ray.
By explicitly setting — distributed-executor-backend ray, we told vLLM to stop looking for local hardware and instead look at the cluster state. Ray acts as the orchestrator that “stitches” the two DGX Spark units together, allowing the vLLM engine to see two GPUs across two different IP addresses as one unified pipeline.
Section 3: The “AI Wingman” Effect
Why I Paired My Hardware with Gemini
Building a mini-supercomputer isn’t just about hardware; it’s about navigating a sea of environment variables (NCCL_SOCKET_IFNAME, GLOO_SOCKET_IFNAME) and library versions.
Throughout this project, Gemini served as my real-time infrastructure consultant. When the server threw Pydantic validation errors, Gemini didn’t just explain the error — it analyzed my specific hardware topology (two nodes, one GPU each) and provided the exact Ray initialization sequence needed to bypass the “World Size” bottleneck.
In an era where software documentation often lags behind hardware releases, having an AI that understands the nuances of Pipeline Parallelism versus Tensor Parallelism is the difference between a running model and an expensive paperweight.
Key Takeaways for Your Readers
FeatureTraditional WorkstationDual DGX Spark ClusterModel CapacityUp to 30B (on 24GB GPUs)Up to 200B+Memory ArchitectureSplit (VRAM vs System RAM)Unified Coherent MemoryForm FactorLarge Tower / Server RackTwo 6-inch Desktop UnitsInterconnect6PCIe Gen 4/5 (64GB/s)7NVLink-C2C (900GB/s)8
Introduction: The Era of Massive Open Models
The open-weight AI landscape is moving at breakneck speed. With releases like DeepSeek-R1-Distill-Llama-70B, we now have access to reasoning capabilities that rival proprietary models. But there is a catch: “Open weight” doesn’t mean “easy to run.”
A 70 billion parameter model is a beast. Even quantized down to FP16, it demands upwards of 140GB of VRAM just to load the weights, not counting the massive memory needed for the Key-Value (KV) cache during long-context generation.
I recently found myself in front of two powerful NVIDIA DGX Spark nodes, tasked with getting this 70B giant up and running. The challenge wasn’t a lack of compute power; it was orchestration. How do you take a model too big for one GPU and split it efficiently across two separate physical machines without crushing performance?
This is the story of building that distributed inference cluster, the technical hurdles encountered, and how having an AI assistant (Gemini) as a technical co-pilot turned days of debugging into hours of configuration.
The Hardware Setup: NVIDIA DGX Spark
We weren’t running on commodity hardware. We were utilizing NVIDIA DGX Spark units. These are enterprise-grade systems designed specifically for accelerated analytics and AI workloads.
- Node Count: 2 Physical Nodes
- GPU Configuration: 1 high-powered NVIDIA GPU per node.
- Storage: High-speed shared storage accessible by both nodes (crucial for consistent model loading).
The goal was clear: combine the VRAM and compute of both DGX nodes to serve one unified API endpoint for the 70B model.
The Software Stack: vLLM and The Parallelism Puzzle
To serve the model, I chose vLLM. It’s currently the gold standard for high-throughput LLM serving, known for its PagedAttention mechanism.
However, vLLM out-of-the-box usually assumes one machine. When you cross physical boundaries, things get complicated.
The “Aha!” Moment: Enter Gemini
I started where everyone starts: trying to run a basic command and failing. I realized I wasn’t even running the vLLM process correctly, and I was struggling with how to point the system to my local model files rather than Hugging Face.
This is where I brought in Gemini. I pasted my confusing terminal outputs and my directory structure.
Instead of getting generic documentation links, Gemini immediately recognized the context. It pointed out that my model path was relative and needed to be absolute so vLLM wouldn’t try to download it. More importantly, it immediately identified the architectural constraint of my setup.
Because I had two nodes with one GPU each, Gemini advised that I couldn’t use Tensor Parallelism (TP) (which usually splits individual layers across GPUs on the same bus). Instead, I needed Pipeline Parallelism (PP).
- The Gemini Insight: “With 1 GPU per node (2 nodes total), you must use
--pipeline-parallel-size 2. vLLM will split the layers of the 70B model: approximately 40 layers on Node 1 and 40 layers on Node 2."
This architectural clarity was the turning point. I wasn’t just running commands anymore; I was designing a distributed system.
The Critical Glue: Networking and Ray
You can’t just tell two computers to share a model. They need a high-speed lane to pass massive amounts of activation data back and forth between layers.
If your nodes try to communicate over a standard 1Gb ethernet connection, the GPUs will spend all their time waiting for data. On DGX systems, you want to utilize the fastest available interconnects.
We needed to configure Ray, the distributed framework vLLM uses under the hood, and NCCL (NVIDIA Collective Communications Library) to use the right “pipes.”
This was the most delicate part of the setup. We had to:
- Identify the high-speed network interface on the DGX nodes (e.g., a specific high-speed Ethernet or InfiniBand interface).
- Explicitly tell Ray and NCCL to bind only to that interface.
If you skip this step, Ray might bind to a slow management interface, and your inference speed will crawl.
The Final Configuration
Thanks to the iterative back-and-forth with Gemini — verifying paths, network interface names, and appropriate VRAM safety flags — we arrived at a stable configuration.
Here is the sanitized blueprint for running a 70B model across two DGX nodes using high-speed shared storage.
Prerequisites
Ensure both nodes have the same Python environment and vLLM installed. Ensure the high-speed shared storage is mounted at the same path on both nodes.
Step 1: The Head Node (The Master)
The head node starts the Ray cluster and loads the first half of the model layers.
Bash
# Export network variables to ensure high-speed communication
# Replace [YOUR_HIGH_SPEED_INTERFACE] with your actual interface name (e.g., enp1s0, ib0)
export NCCL_SOCKET_IFNAME=[YOUR_HIGH_SPEED_INTERFACE]
export GLOO_SOCKET_IFNAME=[YOUR_HIGH_SPEED_INTERFACE]
# Start the Ray head
ray start --head --port=6379# Launch the vLLM server
# We use --enforce-eager for safety on initial runs with massive models
python3 -m vllm.entrypoints.openai.api_server \
--model /path/to/your/shared/storage/official-r1-70b/ \
--pipeline-parallel-size 2 \
--tensor-parallel-size 1 \
--max-model-len 16384 \
--trust-remote-code \
--enforce-eager \
--host 0.0.0.0 --port 8000Step 2: The Worker Node
The worker node joins the cluster and loads the second half of the layers.
Bash
# Export the same network variables
export NCCL_SOCKET_IFNAME=[YOUR_HIGH_SPEED_INTERFACE]
export GLOO_SOCKET_IFNAME=[YOUR_HIGH_SPEED_INTERFACE]
# Join the Ray cluster initiated by the head node
# Replace [HEAD_NODE_IP] with the IP address of the head node on the high-speed interface
ray start --address='[HEAD_NODE_IP]:6379'Watching the logs on the head node as the worker connected and hearing the DGX fans spin up as 140GB of weights loaded across the network was a satisfying moment.
Conclusion: The AI Co-Pilot Advantage
Running distributed AI infrastructure is difficult. The documentation is vast, the hardware idiosyncrasies are many, and one wrong environment variable can break everything.
While the NVIDIA DGX Spark hardware provided the raw muscle necessary for this task, the speed at which this cluster was brought online was largely due to having an AI assistant in the loop.
Gemini acted not just as a search engine, but as a contextual consultant. It translated my specific hardware constraints into the exact software parameters needed for vLLM. It turned a potential week of frustrating trial-and-error into an afternoon of targeted engineering.
As models keep getting bigger, the future of AI engineering isn’t just about knowing the commands; it’s about knowing how to effectively partner with AI to navigate the complexity of the infrastructure required to run them.
메타데이터
- post_id
- 0b3aca0c4988
- slug
- taming-giants-serving-deepseek-r1-70b-across-dual-nvidia-dgx-spark-nodes-0b3aca0c4988
- url
- https://medium.com/@sarankannan2002/taming-giants-serving-deepseek-r1-70b-across-dual-nvidia-dgx-spark-nodes-0b3aca0c4988
- canonical_url
- https://medium.com/@sarankannan2002/taming-giants-serving-deepseek-r1-70b-across-dual-nvidia-dgx-spark-nodes-0b3aca0c4988
- author_url
- https://medium.com/@sarankannan2002
- status
- ok
- fetched_at
- 2026-06-09 15:37:30