Optimizing Memory Layouts: Avoiding Cache Misses with NumPy Strides
Unlock blazing-fast data processing by understanding NumPy’s stride mechanics and memory layout optimization.
Optimizing Memory Layouts: Avoiding Cache Misses with NumPy Strides
Unlock blazing-fast data processing by understanding NumPy’s stride mechanics and memory layout optimization.
Boost NumPy performance by mastering memory layouts and stride tricks. Learn how to reduce cache misses on real-world data for faster computation.
Introduction: Why Your Fast Code Still Feels Slow
You’ve vectorized your operations, removed Python loops, and leaned hard on NumPy — but something still doesn’t add up. Your code looks efficient, yet benchmarks tell a different story. Why?
It often comes down to how your data is stored and accessed in memory. Memory layout, cache locality, and strides — those silent performance influencers — can make or break your processing speed, especially when working with large real-world datasets.
In this article, we’ll deep dive into how NumPy arrays are laid out in memory, explore the concept of strides, and show you practical ways to optimize memory access patterns to avoid cache misses and unlock maximum performance.
The Anatomy of a NumPy Array: More Than Meets the Eye
At first glance, a NumPy array seems like a simple grid of numbers. But under the hood, each array is a highly structured object with key attributes:
data: the actual buffer of bytes.shape: the dimensions of the array.dtype: data type of the elements.strides: the number of bytes to skip in memory to move to the next element along each axis.
The stride is a key player when it comes to performance. It dictates how your array is traversed in memory — crucial for avoiding CPU cache misses.
Let’s break it down:
import numpy as np

a = np.array([[1, 2, 3], [4, 5, 6]], dtype=np.int32)
print("Shape:", a.shape)
print("Strides:", a.strides)  # Output: (12, 4)
Here, to move to the next row, NumPy skips 12 bytes (3 columns × 4 bytes), and to move to the next column, it skips 4 bytes.
Cache Misses: The Silent Performance Killer
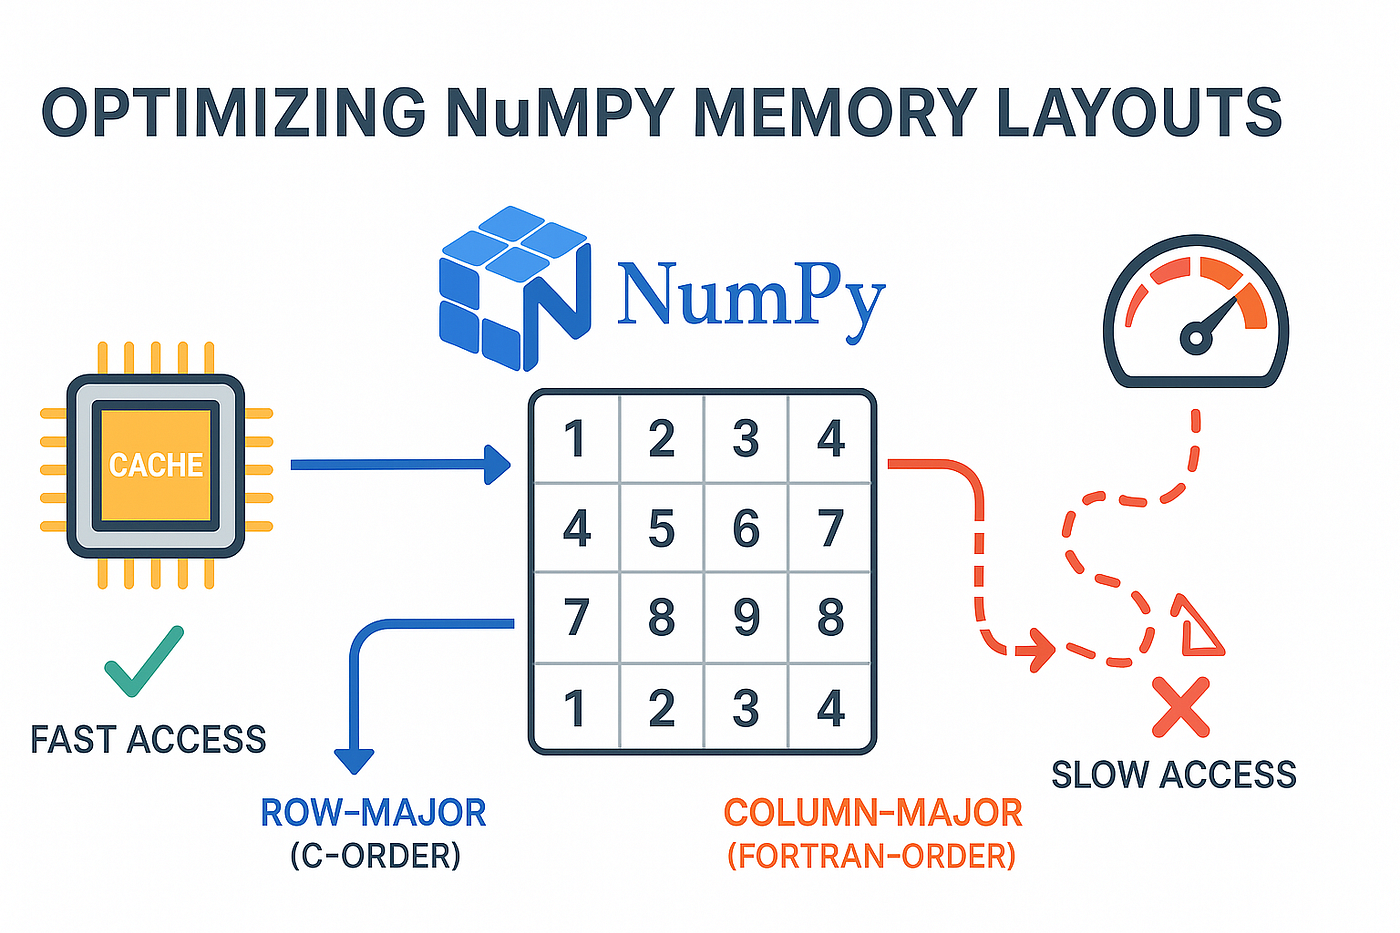
Modern CPUs use cache memory to speed up access to frequently used data. When your data is accessed in the order it’s laid out in memory (also called contiguous access), your CPU can prefetch it, reducing wait time.
But if your data is accessed in a non-contiguous way (say, by slicing columns instead of rows), the CPU has to jump around in memory — leading to cache misses, where the data isn’t available in the fast-access cache and has to be fetched from slower RAM.
This seemingly small inefficiency can scale up to seconds lost in large computations, especially in machine learning or data analysis pipelines.
C vs. Fortran Order: Layout Matters
NumPy supports two primary memory layouts:
- C-order (row-major): Rows are stored one after another.
- Fortran-order (column-major): Columns are stored contiguously.
By default, NumPy uses C-order. But if your algorithm accesses data column-wise (e.g., time series stored as columns), Fortran order might offer better performance.
# Column-major layout
b = np.asfortranarray(a)
print("Strides in Fortran order:", b.strides)
Understanding which layout suits your access pattern can drastically reduce cache misses.
Stride Tricks: Read-Only Performance Boosts
NumPy’s as_strided() function from numpy.lib.stride_tricks lets you create new views of the same data with custom strides—zero-copy and ultra-fast.
Example: Sliding Window without a Loop
Suppose you want a sliding window view of a 1D array:
from numpy.lib.stride_tricks import as_strided

x = np.arange(10)
window_size = 3
stride = x.strides[0]

sliding_windows = as_strided(x, shape=(len(x)-2, 3), strides=(stride, stride))
print(sliding_windows)
This technique avoids data duplication and keeps cache performance high.
⚠️ Caution: Improper use of as_strided() can lead to segmentation faults or data corruption. It’s a powerful but sharp tool.
Real-World Tip: Structure for Access, Not Just for Storage
In real-world datasets — like large matrices from scientific experiments or financial time series — how you structure and access the data matters more than just storing it compactly.
For example:
- When building batches for deep learning, make sure your tensors follow the access pattern of your compute backend (e.g., TensorFlow prefers NHWC while PyTorch prefers NCHW).
- If you frequently transpose large matrices, consider storing them in the format that matches the most frequent operation.
Performance Benchmarks: Strides in Action
Let’s test performance on row-wise vs. column-wise access:
import time

arr = np.random.rand(10000, 10000)

# Row-wise
start = time.time()
_ = [np.sum(row) for row in arr]
print("Row-wise time:", time.time() - start)

# Column-wise
start = time.time()
_ = [np.sum(col) for col in arr.T]
print("Column-wise time:", time.time() - start)
You’ll often find that accessing rows (which are contiguous in C-order) is significantly faster.
Best Practices for Memory Layout Optimization
- Know Your Access Pattern Structure arrays to match how data will be read or processed — not how it’s stored.
- Avoid Unnecessary Transposes Each transpose may change strides, affecting cache behavior.
- Use Contiguous Arrays
Use
.copy()withorder='C'ororder='F'when needed to enforce layout. - Profile Strategically
Use
%timeit,line_profiler, or tools like Intel VTune to spot cache-related slowdowns. - Beware of Implicit Copies
Functions like
np.concatenate()or slicing non-contiguous arrays can create unexpected copies. Use.flags['C_CONTIGUOUS']to check.
Conclusion: Small Shifts, Big Gains
Strides and memory layout might seem like low-level internals best left to system architects. But as you’ve seen, they can make a huge impact on performance — especially when working with large datasets or tight computation loops.
Understanding how NumPy arrays behave in memory, choosing the right layout, and avoiding cache misses through smart access patterns are all key to unlocking real performance in data-heavy Python applications.
If this article helped you think differently about how your code interacts with memory, please leave a 💬 comment, 💚 clap, or share it with your fellow data wranglers. Let’s help more people write code that not only looks clean but runs fast.
Optional External Links:
메타데이터
- post_id
- ca86c9c3a8a7
- slug
- optimizing-memory-layouts-avoiding-cache-misses-with-numpy-strides-ca86c9c3a8a7
- url
- https://medium.com/@ThinkingLoop/optimizing-memory-layouts-avoiding-cache-misses-with-numpy-strides-ca86c9c3a8a7
- canonical_url
- https://medium.com/@ThinkingLoop/optimizing-memory-layouts-avoiding-cache-misses-with-numpy-strides-ca86c9c3a8a7
- author_url
- https://medium.com/@ThinkingLoop
- status
- ok
- fetched_at
- 2026-08-02 20:41:19