Whatever Nvidia Does, We Do the Opposite
That’s Jim Keller. And he’s not bluffing.
Whatever Nvidia Does, We Do the Opposite
Two weeks ago, the man behind the iPhone chips, PlayStation’s architecture, and AMD’s Zen CPU stood on a stage and said:
“Whatever Nvidia does, we’ll do the opposite.”
That’s Jim Keller. And he’s not bluffing.
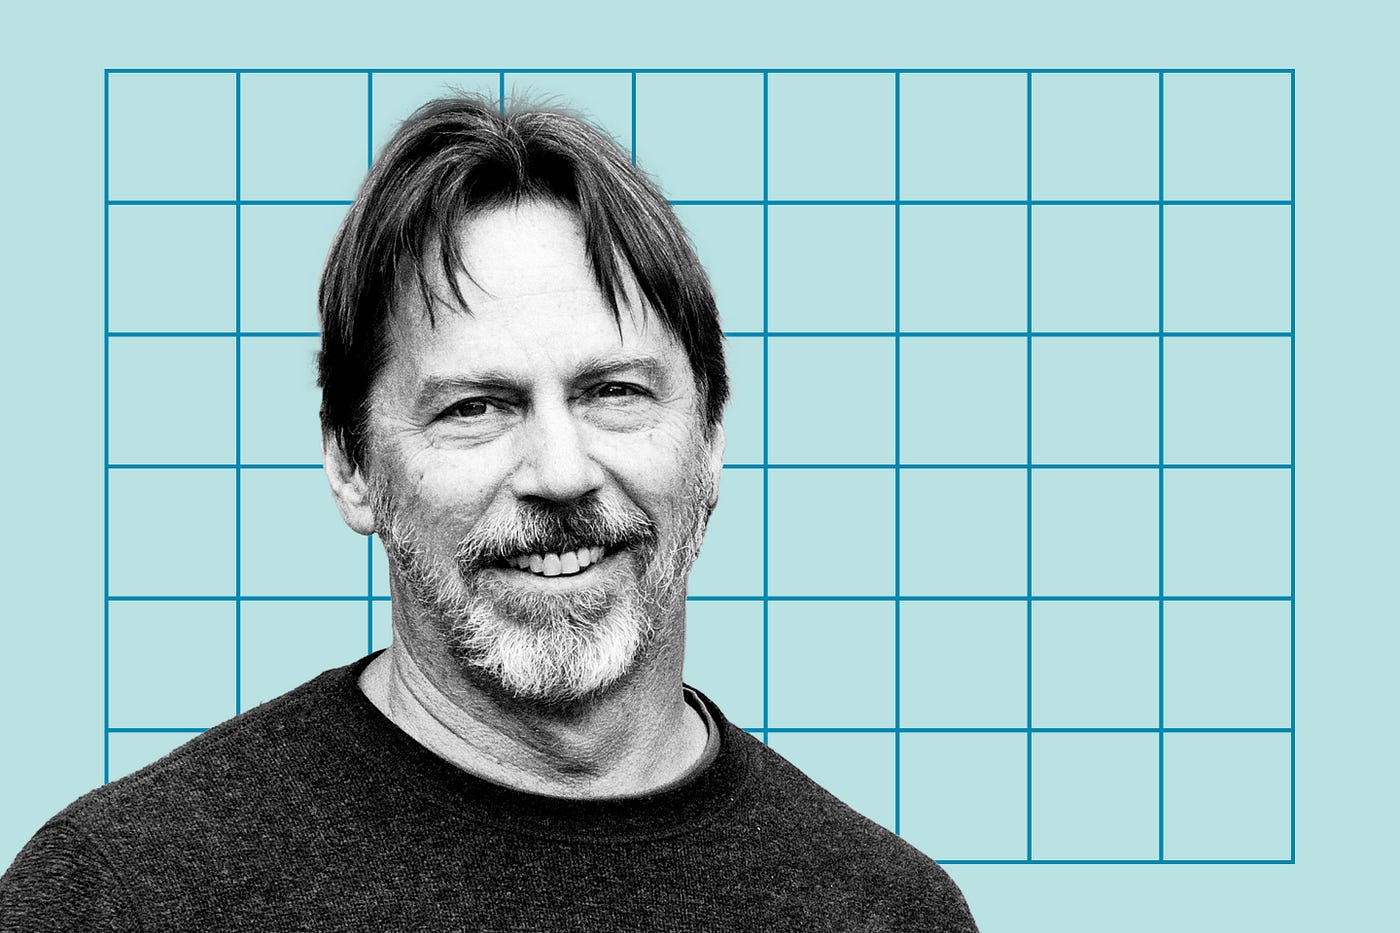
Jim Keller, CEO of Tenstorrent, speaking at a public event. The legendary chip architect is all smiles — and for good reason. Image: Fortune
Jim Keller, CEO of Tenstorrent, the man who just bet everything on a future where Nvidia doesn’t get to set the rules.
His company, Tenstorrent, just built a chip that beats Nvidia’s best inference system while costing five times less to run. Not a prototype. Not a press release. Third-party benchmarks. Real numbers.
So why is this barely a headline?
The Problem Nvidia Doesn’t Want You to Notice

Nvidia GPU architecture diagram showing HBM memory modules stacked on the chip. High Bandwidth Memory is the reason Nvidia chips cost as much as a car. Image: Semiconductor Engineering
This is HBM memory the expensive, power-hungry bottleneck Nvidia uses to keep prices high and margins higher.
Every time you use Claude, Gemini, or ChatGPT, somewhere a server is burning electricity and someone’s $3 billion annual infrastructure budget.
Right now, Nvidia controls that bill entirely. They charge whatever they want because there’s no real alternative.
Jim Keller decided to fix that.
And he started by rejecting every single assumption Nvidia’s architecture is built on.
The Core Insight That Changes Everything
Here’s what most people don’t realize about a modern GPU:
Less than half the silicon is actually doing math.
The rest? Hardware schedulers, cache controllers, and memory management units constantly playing traffic cop figuring out where data needs to go next.
It’s overhead. Massive, power-hungry overhead.
But Keller had a critical observation:
AI math isn’t random like rendering a video game. It’s perfectly predictable. You almost always know exactly what and when the data is needed before the chip even starts computing.
If the workload is predictable, you don’t need hardware to manage unpredictability.
So Keller’s team did something audacious: they deleted all the schedulers and traffic controllers.
All that management work moves into the software compiler which now knows the entire journey of every piece of data before the chip even turns on.
What the Chip Actually Looks Like

Tenstorrent Black Hole chip with intricate circuitry and heatsinks, labeled with the Black Hole branding. Image: TechPowerUp
The Black Hole chip Tenstorrent’s latest is built around a simple philosophy: let the compiler do the work the hardware shouldn’t have to do.
The result is called Black Hole Tenstorrent’s latest chip.
Instead of one massive processor fighting for resources, you’ve got:
- 352 Tensix cores packed onto a single chip
- 5 independent cores per tile, each with its own local SRAM
- No global clock — everything runs asynchronously
- No core ever sits around waiting for another to finish

Architecture diagram showing the Tensix core design RISC-V cores inside each compute unit, with routers and L1 memory handling data flow. Image: ServeTheHome
Each Tensix core contains a RISC-V processor that orchestrates compute — not a generic GPU scheduler doing guesswork.
Think of it like a fleet of small boats that all know the route in advance, rather than one massive ship waiting for traffic control to tell it where to go next.
The Memory Decision That Made Everyone Angry

Comparison of GPU memory architectures HBM stacked memory vs standard GDDR6. The difference in cost and complexity is visible in the physical layout. Image: Semiconductor Engineering
On the left: HBM stacked, expensive, power-hungry. On the right: GDDR6 standard, cheap, battle-tested. Tenstorrent chose right.
To run modern AI, Nvidia relies on HBM (High Bandwidth Memory) expensive memory that sits directly on the chip package. Insanely fast. Also the single biggest reason an AI chip costs more than a car.
Tenstorrent looked at HBM and said: “Hard pass.”
Instead, they used standard GDDR6 the cheap memory inside a PlayStation or mid-range gaming GPU.
On paper, that sounds like a downgrade. Lower bandwidth means slower memory access, right?
Here’s where it gets clever:
Because the compiler already knows what’s coming, it prefetches exactly what each core needs from slow GDDR6 right before it’s required. The cores are never actually waiting.
200 megabytes of SRAM per chip handles the rest.
Raw bandwidth only matters if you don’t know what’s coming. The compiler knows everything.
The Networking Trick That Changes the Scaling Game

Tenstorrent Galaxy server a dual-rack supercomputer with 1,000 chips working as a single unified system. Image: DataCenter Dynamics
32 chips, 1,000 chips Tenstorrent’s Galaxy servers scale without the NVLink tax. Each chip is simultaneously a processor and a router.
This is where it gets interesting for data centers.
When you chain multiple chips together to run massive models, they start spending more time talking to each other than actually computing. Nvidia’s fix: NVLink incredibly fast, but costs as much as the chips themselves.
Tenstorrent’s answer was brutally simple:
They baked 400 GB/s Ethernet straight into every Black Hole chip.
Every chip is simultaneously a processor and a router. No expensive external switches. No layers of latency and complexity.
Tenstorrent Galaxy architecture diagram showing 1,000 chips connected in a mesh no bottlenecks, no central switch. Image: Tenstorrent
This is what 1,000 chips looks like when the compiler already knows every data movement before it happens. No central switch. No bottleneck.
And because the compiler premaps data movement across the entire cluster before a single calculation starts, 32 chips in a Tenstorrent Galaxy server don’t behave like 32 separate components.
They behave like one unified brain.
Chain 36 servers together (1,000+ chips) and you get a supercomputer without bottlenecks.
The Numbers That Actually Matter
Third-party benchmarks on DeepSeek R1:
- 350 tokens per second
- $6 per million tokens (Tenstorrent)
- vs. $30 per million tokens (Nvidia)
Same performance. Five times cheaper.
Why No One Is Buying It Yet
If the hardware is this good and the software is free, why isn’t every data center ripping out their Nvidia racks?
Two reasons:
1. The software gap is real
Tenstorrent claims 90% of Hugging Face models run out-of-the-box on their hardware.
To a developer, that sounds great. Until you ask about the other 10%.
Enterprise buyers don’t make billion-dollar infrastructure decisions on 90% compatibility. A hospital running medical imaging AI cannot afford to be stuck in that last 10%.
Black Hole’s software is still new. The previous generation (Wormhole) has years of optimization behind it. Black Hole is catching up.

Tenstorrent Wormhole n300 the previous generation chip that’s had years to mature its software stack. Image: Mos CGI/Future
Wormhole (left) is where Tenstorrent’s software maturity lives. Black Hole is closing the gap but slowly.
2. Jim Keller’s pattern
If you look at his track record:
- Zen architecture at AMD → saved AMD from bankruptcy → Keller left before chips shipped
- Apple’s A-series chips → laid the foundation for modern iPhones → left before they fully matured
- Tesla’s full-self-driving silicon → left after 18 months
The pattern isn’t that Jim Keller fails. It’s that he builds the foundation and walks away before it becomes an inferno.
Tenstorrent is now four years in right around when Keller historically starts looking for the exit.
Are enterprises supposed to buy millions of dollars of hardware just for the chief architect to potentially leave?
That’s the question every procurement team is quietly asking.
Why This Time Might Be Different
Here’s the thing that separates Tenstorrent from every project that came before:
He’s not just the architect anymore. He’s the CEO.
For the first time in his career, Jim Keller isn’t building someone else’s future. He’s building his own.
And the software problem is closing faster than anyone expected. Because Tenstorrent’s stack is fully open source the entire global community is helping fix it, not just one isolated engineering team.
That’s a fundamentally different trajectory than how Nvidia’s CUDA was built.
The Real Story
This isn’t just a chip story. It’s a glimpse at what happens when someone with the most legendary track record in silicon decides to build on his own terms — with open-source tools, a compiler that knows everything, and a “whatever Nvidia does, we’ll do the opposite” philosophy.
The Tenstorrent Black Hole chip collection multiple units arranged together, each one a building block in a new kind of AI infrastructure. Image: Tenstorrent
The pieces are on the board. The question is whether the world is ready to play by someone else’s rules.
The question isn’t whether Tenstorrent can compete.
It’s whether the world is ready for a challenger that refuses to play by Nvidia’s rules.
And whether Jim Keller for the first time stays long enough to see the fire he started actually burn.
If you found this useful, you can read more of my writing on Medium. I write about AI, software, and how new tech actually affects developers. No hype, just clarity.
메타데이터
- post_id
- 2722855327d6
- slug
- whatever-nvidia-does-we-do-the-opposite-2722855327d6
- url
- https://medium.com/@warpie/whatever-nvidia-does-we-do-the-opposite-2722855327d6
- canonical_url
- https://medium.com/@warpie/whatever-nvidia-does-we-do-the-opposite-2722855327d6
- author_url
- https://medium.com/@warpie
- status
- ok
- fetched_at
- 2026-06-12 07:40:50