Machine Learning Lesson 12: Ensemble Models
Definition:
Machine Learning Lesson 12: Ensemble Models
Definition:
Ensemble is a supervised learning technique for combining multiple weak learners/ models to produce a strong learner model with improvised stability and predictive power. For example: To identify ‘spam’ and ‘not spam’ emails, we can try using following criteria. If:
-
Email has only one image file (promotional image), It’s a SPAM
-
Email has only link(s), It’s a SPAM
-
Email body consist of sentence like “You won a prize money of $ xxxxxx”, It’s a SPAM
-
Email from a known official domain, Not a SPAM
-
Email from known sender, Not a SPAM
But, individually, these rules are not powerful enough to classify an email into ‘spam’ or ‘not spam’. Therefore, these rules are called as weak learner. To convert weak learner to strong learner, we can combine the prediction of each weak learner using methods like: averaging (for Regression problem) or voting (for classification problems) to come with an Ensemble Model.
We can combine multiple models of same ML algorithms, but combining multiple predictions generated by different algorithms would normally give better predictions. It is due to the diversification or independent nature as compared to each other. For example, the predictions of a random forest, a SVM, and a Naive Bayes may be combined to create a stronger final prediction set as compared to combining three random forest model. The key to creating a powerful ensemble is model diversity. An ensemble with two techniques that are very similar in nature will perform poorly than a more diverse model set.
Error in Ensemble Learning (Variance vs. Bias):
To understand what really goes behind an ensemble model, we need to first understand what causes error in the model. The error emerging from any model can be broken down into three components mathematically. Following are these components:
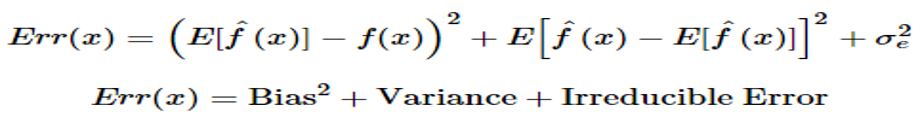
Bias error is useful to quantify how much on an average are the predicted values different from the actual value. A high bias error means we have an under-performing model which keeps on missing important trends.
Variance on the other side quantifies how are the prediction made on same observation different from each other. A high variance model will over-fit on the training population and perform badly on any observation beyond training. Following diagram will give you more clarity (red spot is the real value and blue dots are predictions):

Normally, as we increase the complexity of our model, there will be a reduction in error due to lower bias in the model. However, this only happens till a particular point. As we continue to make our model more complex, we end up over-fitting your model and hence your model will start suffering from high variance. A champion model should maintain a balance between these two types of errors. This is known as the trade-off management of bias-variance errors. Ensemble learning is one way to execute this trade off analysis.

Sampling with Replacement:
Consider a population of potato sacks, each of which has either 12, 13, 14, 15, 16, 17, or 18 potatoes, and all the values are equally likely. Suppose that, in this population, there is exactly one sack with each number. So the whole population has seven sacks. If I sample two with replacement, then I first pick one (say 14). I had a 1/7 probability of choosing that one. Then I replace it. Then I pick another. Every one of them still has 1/7 probability of being chosen. And there are exactly 49 different possibilities here (assuming we distinguish between the first and second.) They are: (12,12), (12,13), (12, 14), (12,15), (12,16), (12,17), (12,18), (13,12), (13,13), (13,14), etc.
Sampling Without Replacement:
Consider the same population of potato sacks, each of which has either 12, 13, 14, 15, 16, 17, or 18 potatoes, and all the values are equally likely. Suppose that, in this population, there is exactly one sack with each number. So the whole population has seven sacks. If I sample two without replacement, then I first pick one (say 14). I had a 1/7 probability of choosing that one. Then I pick another. At this point, there are only six possibilities: 12, 13, 15, 16, 17, and 18. So there are only 42 different possibilities here (again assuming that we distinguish between the first and the second.) They are: (12,13), (12,14), (12,15), (12,16), (12,17), (12,18), (13,12), (13,14), (13,15), etc.
Bootstrapping:

In machine learning, the bootstrap method refers to random sampling with replacement. By using multiple sample data sets and then testing multiple models, it can increase robustness. Perhaps one sample data set has a larger mean than another, or a different standard deviation. This might break a model that was overfit, and not tested using data sets with different variations.
Types of Ensemble Models:
1. Bagging (Bootstrap Aggregating):
Bagging is an Ensemble method which creates multiple samples (with replacement) from the training data then runs a single model on each of these samples and finally, results of these multiple samples are combined using average (for Regression problem) or voting (for Classification Problem). By sampling with replacement (bootstrap sampling), some observations may be repeated in each new training data set. Bagging helps to reduce the variance and avoid overfitting. Random forest is one of the most important bagging ensembles learning algorithms.

2. Boosting:
This technique employs the logic in which the subsequent models learn from the mistakes of the previous models. Therefore, the observations have an unequal probability of appearing in subsequent models and ones with the highest error appear most. (So, the observations are not chosen based on the bootstrap process, but based on the error). The predictors can be chosen from a range of models like decision trees, regressors, classifiers etc. Because new predictors are learning from mistakes committed by previous predictors, it takes less time/iterations to reach close to actual predictions. But we have to choose the stopping criteria carefully or it could lead to overfitting on training data.
Boosting provides sequential learning of the predictors. It starts by classifying original data set and giving equal weights to each observation. If classes are predicted incorrectly using the first learner, then it gives higher weight to the missed classified observation. Being an iterative process, it continues to add classifier learner until a limit is reached in the number of models or accuracy. Most common example of boosting is AdaBoost and Gradient Boosting.

A. AdaBoost (Adaptive Boosting):
The algorithm takes the entire training data and randomly sample points from this data. Initially all the observations are given equal weights for being selected in a sample. Then algorithm builds a decision tree model on that randomly selected sample. Then, algorithm fits the decision tree to the complete training data. Then algorithm increase the weights of these misclassified sample points so that that they have a better chance of being selected when sampled again. When data is sampled next time, the decision stump 2 is combined with decision stump 1 to fit the training data. Therefore, we have a miniature ensemble here trying to fit the data perfectly. This miniature ensemble of two decision stumps might misclassifies few of the sample points. Therefore, we exaggerate the weights of these misclassified samples so that that they have a better chance of being selected when sampled again. The previously misclassified samples are chosen and again a decision tree model is built. Then the ensemble of three decision stumps (1, 2 and 3) are used to fit the complete training data. Being an iterative process, it continues to add learner(s) until a limit is reached in the number of models or accuracy. The final classifier is a weighted sum of the decisions made by the trees. The following diagram aptly explains Ada-boost.

Box 1: You can see that we have assigned equal weights to each data point and applied a decision stump to classify them as + (plus) or — (minus). The decision stump (D1) has generated vertical line at left side to classify the data points. We see that, this vertical line has incorrectly predicted three + (plus) as — (minus). In such case, we’ll assign higher weights to these three + (plus) and apply another decision stump.
Box 2: Here, you can see that the size of three incorrectly predicted + (plus) is bigger as compared to rest of the data points. In this case, the second decision stump (D2) will try to predict them correctly. Now, a vertical line (D2) at right side of this box has classified three misclassified + (plus) correctly. But again, it has caused misclassification errors. This time with three -(minus). Again, we will assign higher weight to three — (minus) and apply another decision stump.
Box 3: Here, three — (minus) are given higher weights. A decision stump (D3) is applied to predict these misclassified observations correctly. This time a horizontal line is generated to classify + (plus) and — (minus) based on higher weight of misclassified observation.
Box 4: Here, we have combined D1, D2 and D3 to form a strong prediction having complex rule as compared to individual weak learner. You can see that this algorithm has classified these observations quite well as compared to any of individual weak learner.
The drawback of AdaBoost is that it is easily defeated by noisy data, the efficiency of the algorithm is highly affected by outliers as the algorithm tries to fit every point perfectly.
B. Gradient Boosting:
To overcome problem of overfitting that we encounter on AdaBoost method, Gradient Boosting Method comes into picture. We create multiple bootstrap samples from the population and one of such sample is taken to build an initial weak learner and the model is asked to fit the complete training data. Let’s think of these below residuals as mistakes committed by our initial weak predictor. We might argue that, if we are able to see some pattern of residuals around 0, we can leverage that pattern to fit a model.

So, the intuition behind gradient boosting algorithm is to repetitively leverage the patterns in residuals and strengthen a model with weak predictions and make it better. So, each consecutive weak learner is built on independently drawn from random sample to predict the residuals coming from previous weak learner. We just sample with replacement so that each tree ends up with at most 1 “copy” of each data point (as opposed to a random forest where sampling is done with replacement and some data points will show up multiple times in each sample). Once we reach a stage that residuals do not have any pattern that could be modelled, we can stop modelling residuals (otherwise it might lead to overfitting). For the Gradient boosting algorithm, the final prediction is just the prediction from the “final tree” which is inherently summing up residual predictions from all trees and the actual prediction from the first one.
h1(x)=y−F1(x)
F2(x)=F1(x)+h1(x)
So, if we iteratively do this then,
F(x)=F1(x)↦F2(x)=F1(x)+h1(x)⋯↦FM(x)=FM−1(x)+hM−1(x) where F1(x) is an initial model fit to y.


We observe that after 20th iteration, residuals are randomly distributed around 0 and our predictions are very close to true values.

We see that even after 50th iteration, residuals vs. x plot look similar to what we see at 20th iteration. But the model is becoming more complex and predictions are overfitting on the training data and are trying to learn each training data. So, it would have been better to stop at 20th iteration.
The MSE loss function computed from N observations in matrix is:


But let’s substitute for the model output, to make equation clearer:


Since N is a constant it has no impact on computing minima. So we drop it:

Now let’s take partial derivative of the loss function with respect to a specific approximation:

Dropping the constant in front again leaves us with the gradient being the same as the residual vector: So, chasing the residual vector in a GBM is chasing the gradient vector of the MSE loss function while performing gradient descent. The following steps are involved in gradient boosting:
- F0(x) — with which we initialize the boosting algorithm — is to be defined:

- The gradient of the loss function is computed iteratively:

- Each hm(x) is fit on the gradient obtained at each step
- The multiplicative factor γm for each terminal node is derived and the boosted model Fm(x) is defined:

Light GBM grows tree vertically while other algorithm grows trees horizontally meaning that Light GBM grows tree leaf-wise while other algorithm grows level-wise. It will choose the leaf with max delta loss to grow. When growing the same leaf, Leaf-wise algorithm can reduce more loss than a level-wise algorithm.
C. Extreme Gradient Boosting Machine (XG Boost)
Extreme Gradient Boosting or XG Boost is another popular boosting algorithm. In fact, XG Boost is simply an improvised version of the GBM algorithm! The working procedure of XG Boost is the same as GBM. But there are certain features that make XG Boost slightly better than GBM:
- Regularization for solving over ftting
- parallel processing
- flexibility in setting an objective function
- handling of missing values
- non-greedy tree pruning
- built-in cross-validation and methods of dropout (DART)
Difference between Bagging and Boosting:
→In Boosting, each model is built on top of the previous ones. Whereas in bagging each model is built independently.
→The final boosting ensemble uses weighted majority vote while bagging uses a simple majority vote/ averaging.
→Bagging is a method of reducing variance while boosting can reduce the variance and bias of the base classifier.
→Bagging solves problem of overfitting while boosting is not immune to overfitting problem.

메타데이터
- post_id
- 2ecb7a1b3965
- slug
- machine-learning-lesson-12-ensemble-models-2ecb7a1b3965
- url
- https://medium.com/@ai_academy/machine-learning-lesson-12-ensemble-models-2ecb7a1b3965
- canonical_url
- https://medium.com/@ai_academy/machine-learning-lesson-12-ensemble-models-2ecb7a1b3965
- author_url
- https://medium.com/@ai_academy
- status
- ok
- fetched_at
- 2026-07-29 10:02:12




