Stanford Just Put an $850K/Year Skill on YouTube
Stanford Just Put an $850K/Year Skill on YouTube
Anthropic pays up to $850,000 for engineers who build self-improving AI agents. The Stanford course that teaches it dropped last week and one of the instructors helped build Claude.

Anthropic’s website
No Medium membership? No problem, read here for free.
Lets start with a number: Anthropic’s open role for Research Engineer, Agents lists a salary of $500,000–$850,000 a year. Not total comp with equity funny money. Salary. The Code RL role — teaching Claude to write and ship real software and within same range.
And here’s the part that makes our timeline ridiculous (in a good way): a week ago, Stanford uploaded the full course that teaches exactly this skill to YouTube. Free. No enrollment, no application, no $70K tuition.
You gotta love it. Knowledge got so cheap and accessible that we’re officially out of excuses.
The course
CS329A: Self-Improving AI Agents — a Stanford graduate course taught by Aakanksha Chowdhery and Azalia Mirhoseini in Fall 2025, uploaded to the official Stanford Online channel on August 3, 2026. Part 1 already has over 200K views, so I’m clearly not the only one who noticed.
Quick word on the instructors, because it matters here.
Aakanksha Chowdhery led the training of Google’s 540B PaLM model — at the time, the largest densely trained language model in the world — and drove pre training for Gemini’s MoE models. Azalia Mirhoseini directs Stanford’s Scaling Intelligence lab and previously worked at Google Brain, Google DeepMind, and — yes — Anthropic, on the development of Claude.
Read that again. One of the people teaching this free course helped build Claude. The skill Anthropic pays up to $850K for is being taught, on YouTube, by someone who did the job.
What “self-improving agents” actually means
Let’s be honest, “AI agents” has become a word that means everything and nothing. This course is about something specific: agents that get better through interaction — with tools, with their environment, with themselves.
The curriculum covers test-time compute scaling (making models smarter by letting them think longer, not by retraining them), verifiers and reward signals, reinforcement learning at train time, multi-step reasoning and planning, augmenting agents with memory and tools, and — the part I find most interesting — evaluating agents on long-horizon tasks, where most of them still quietly fall apart.
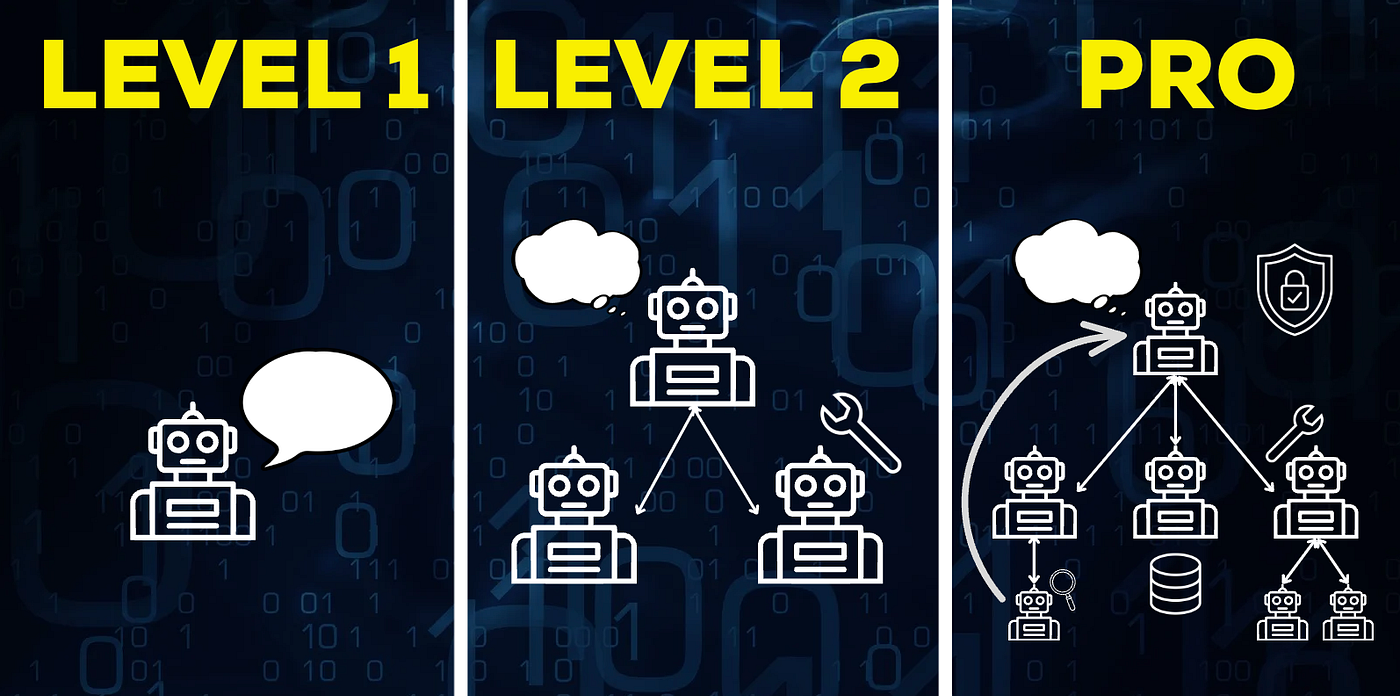
If you’ve used Claude Code or any deep research tool, you’ve touched the output of these techniques. Lecture 1 walks through exactly that arc: how we went from single-turn chatbots to orchestrator-worker agent patterns, using Claude Code as a live example.
Seventeen lectures total. Guest speakers include Denny Zhou and Thang Luong from Google DeepMind, Misha Laskin from Reflection AI, and Danny Driess from Physical Intelligence. This is not a “10 ChatGPT prompts to 10x your productivity” playlist. It’s the real thing.
Why this skill, why now
Look at what Anthropic’s job posting actually asks for: design agent harnesses, build rigorous benchmarks for large-scale agentic tasks, optimize training data for agentic performance. That’s not prompt engineering. That’s a new discipline sitting between research and engineering, and almost nobody has it yet — which is exactly why the number on the posting has six figures before the comma does its work.
The labs are all converging on the same bet: the next leap doesn’t come from bigger base models alone, it comes from agents that improve themselves — through search, through verification, through RL on real tasks. Whoever understands that loop deeply is the person every frontier lab is fighting over.
The zero-excuses part
Ten years ago, this knowledge lived inside maybe three companies and a handful of PhD programs. Five years ago, you needed to be at Stanford to sit in this room. Today, the room is a YouTube playlist and the syllabus is a public webpage with the reading list attached.
I’m not saying watching 17 lectures makes you an $850K engineer. It doesn’t. The people getting those offers have years of hands-on training experience behind them. But the gap between you and that job used to include “access to the knowledge” — and that part of the gap is now thin. What’s left is the part you can actually control: doing the work.
How I’d actually take it
Don’t binge it like a Netflix show — you’ll retain nothing. Instead, try one full lecture per week, with the course page open next to it for the papers. After each lecture, build something tiny that uses the idea. Build in public — document your journey on X or LinkedIn. Watched the test-time compute lecture? Implement best-of-N sampling with a simple verifier over a weekend. Watched the memory lecture? Bolt a memory layer onto an agent you already have.
The syllabus, schedule, and readings are all at cs329a.stanford.edu. If you want the credentialed version, Stanford also offers it as an online graduate course (XCS329) — but the lectures themselves, the actual knowledge, are sitting on YouTube waiting for you.
The knowledge is free. The effort is what counts now.
메타데이터
- post_id
- 2f131d993219
- slug
- stanford-just-put-an-850k-year-skill-on-youtube-for-free-2f131d993219
- url
- https://medium.com/dare-to-be-better/stanford-just-put-an-850k-year-skill-on-youtube-for-free-2f131d993219
- canonical_url
- https://medium.com/dare-to-be-better/stanford-just-put-an-850k-year-skill-on-youtube-for-free-2f131d993219
- author_url
- https://medium.com/@valerie_m
- status
- ok
- fetched_at
- 2026-10-01 01:07:00