MCP Is Losing the Coding Agent War — And the Numbers Prove It
Independent benchmarks show MCP burning 4–35x more tokens than plain CLI tools — and failing more often on hard tasks. Here’s what’s…
MCP Is Losing the Coding Agent War — And the Numbers Prove It
Independent benchmarks show MCP burning 4–35x more tokens than plain CLI tools — and failing more often on hard tasks. Here’s what’s actually happening, and where MCP still wins.
The first time I connected three MCP servers to my coding agent — GitHub, Slack, and Sentry — I hadn’t asked it to do anything yet. No task. No prompt. Just connections.
Then I looked at the context window: 143,000 of my 200,000 tokens were already gone.
Seventy-two percent of my agent’s working memory, consumed by tool descriptions for tools it hadn’t used and might never use. I was paying — in money and in the agent’s ability to think — for a catalog of possibilities.

I assumed I’d misconfigured something. I hadn’t. This is how MCP works by default. And once I started digging into the benchmarks, I realized my little surprise was the visible tip of a much bigger shift: for coding agents specifically, developers are quietly walking away from MCP — and going back to the most boring technology imaginable.
The command line.
Wait — wasn’t MCP supposed to be the winner?
It was. And in many ways, it still is.
The Model Context Protocol launched in late 2024 as Anthropic’s answer to “integration hell” — the custom glue code every team wrote to connect agents to Jira, Postgres, GitHub, and everything else. It worked. OpenAI and Google adopted it. In December 2025, Anthropic donated MCP to the Linux Foundation, cementing it as the de facto standard for agent-to-tool communication. If you’ve read my earlier piece on MCP, you know I was — and largely still am — a believer in what it standardizes.
But something interesting happened on the way to total victory. The people building coding agents — the Claude Code, Codex, and Cursor crowd, the ones who live in terminals and pay their own API bills — started benchmarking MCP against the dumb alternative: just letting the agent run CLI commands like gh, git, and grep.
The results were not close.
The numbers, honestly presented
I want to be careful here, because “the numbers prove it” is exactly the kind of claim that deserves scrutiny. Different benchmarks measured different things, so here’s the spread rather than one cherry-picked figure:

Let me unpack each, with sources, because numbers without provenance are just vibes with confidence.
1. The token overhead is structural, not incidental
Scalekit’s 2026 benchmark ran identical tasks through MCP servers and CLI tools and measured 4–32x more tokens per call for MCP, driven by JSON schema overhead. A separate benchmark widely covered by MindStudio landed at roughly 35x on identical tasks. An independent test of agent search measured 17x per call. The multiplier moves with the task; the direction never does.
In dollar terms, Scalekit’s comparison of GitHub operations is the cleanest example: at 10,000 monthly operations, the CLI route (gh) cost about $3.20. The MCP route cost about $55.20. Same work. Seventeen times the bill.
2. The “standing cost” is the silent killer
Per-call overhead is only half the story. By default, MCP injects its full tool catalog into the context window — every tool, every parameter, every description — whether the agent uses zero tools or ten. One analysis of a 93-tool GitHub MCP server measured that schema at roughly 55,000 tokens. That’s my three-servers-eat-143k-tokens story, explained. Perplexity’s engineers reported the same pattern: 72% of the context window consumed by tool descriptions alone.
This isn’t just a cost problem. Context is the agent’s working memory. Every token spent describing a tool it won’t use is a token not spent holding your codebase, your error logs, your actual problem.
3. Reliability diverges exactly when it matters
The benchmark covered by MindStudio found both approaches at 100% completion on simple tasks — the regime where every conference demo lives. As complexity rose, CLI held at 100% while MCP degraded to 72%. And per-call reliability compounds: a workflow chaining ten tool calls at 72% each succeeds about 3% of the time.

Figure 1 — The standing-cost problem: what your agent’s context window looks like before it does any work.
One crucial honesty note before we go further: when researchers dug into why MCP runs failed, most failures were TCP timeouts connecting to remote MCP servers — infrastructure problems, not protocol problems. CLI tools run locally; there’s no remote server to time out. That distinction matters, and we’ll come back to it. But for the developer choosing an architecture today, a failure is a failure regardless of which layer caused it.
“A task that costs your CLI tool 1,000 tokens costs your MCP server 35,000. The benchmark numbers aren’t a reason to avoid MCP. They’re a reason to be intentional about it.” — from MindStudio’s analysis of the MCP vs. CLI benchmark
Why this happens: catalogs vs. conversations
The gap isn’t mysterious once you see the two philosophies side by side.
MCP is a catalog model. The server announces everything it can do, in full structured detail, upfront. That’s wonderful for discoverability — the model never has to guess what a tool accepts. But the agent carries that catalog on every single completion request, like packing your entire toolbox for a job that needs one screwdriver.
CLI is a lazy-discovery model. A binary on the PATH costs approximately zero standing tokens. When the agent needs it, it runs --help, reads a few hundred tokens, and acts. Coding agents are unusually good at this, because the models behind them were trained on decades of shell commands, man pages, and Stack Overflow answers. The terminal is their native habitat.
Here’s the same real task — “find open issues labeled bug and comment on the oldest one” — both ways:
The MCP route (simplified)
# Standing cost: full GitHub MCP schema in context (~55k tokens on the 93-tool server)
# Then, per call, the agent emits structured JSON:
{
  "tool": "github_list_issues",
  "arguments": { "owner": "suresh", "repo": "agent-lab",
                 "labels": ["bug"], "state": "open" }
}
# → full JSON response (every field, ~6k tokens in one measured search case)
# → second structured call to github_add_comment ...
The CLI route
# Standing cost: ~0. The agent just runs:
gh issue list --label bug --state open --json number,title,createdAt \
  --jq 'sort_by(.createdAt) | .[0]'

gh issue comment 142 --body "Reproduced on main. Investigating."
# Field projection (--json, --jq) returns only what's needed -
# one measured comparison: 351 tokens vs 6,047 for the default MCP payload
Notice the second advantage hiding in that snippet: field projection. CLI tools let the agent ask for exactly the fields it needs and pipe results between tools with jq and grep. MCP's structured responses, by default, return everything. Composability — the forty-year-old Unix idea — turns out to be a token-efficiency superpower.

Figure 2 — Catalog-upfront vs. discover-on-demand: where the tokens (and the failures) come from.
The honest counterargument: losing a battle isn’t losing the war
If I stopped here, this would be a clean story and a slightly dishonest one. So let’s steelman MCP properly, because three things complicate the obituary.
The reliability gap is largely fixable
Remember those TCP timeouts? They’re an argument against naive MCP deployments, not against the protocol. MCP gateways — a layer that filters schemas down to task-relevant tools, pools connections, and centralizes auth — have been measured restoring ~99% reliability while cutting token overhead by roughly 90%. Anthropic’s own engineering work on code execution with MCP showed a Drive-to-Salesforce workflow dropping from 150,000 tokens to about 2,000 by calling tools as code instead of loading every definition. The waste is a default, not a destiny.
MCP solves a problem CLI can’t
Here’s the part the CLI maximalists skip. The properties that make MCP expensive — explicit schemas, OAuth handshakes, structured responses — are the same properties that make it governable. Run fifty agents across a department with raw CLI access and you’re distributing secrets to every agent session: the pre-SSO era, recreated at machine speed. When an agent acts on behalf of a customer, in a multi-tenant product, with audit requirements? MCP’s authorization model isn’t overhead. It’s the product.
The war has more than one front
That’s why my title says the coding agent war, not the war. For cross-functional agents touching Slack, Jira, and CRMs — used by people who will never open a terminal — MCP remains the standard, and deservedly so. The Linux Foundation didn’t adopt a dying protocol.
But on the coding-agent front specifically, the trend line is unambiguous. Developer-tool benchmarks keep landing the same way, ecosystem projects converting MCP servers into CLIs (mcp2cli, CLIHub, mcp-cli) report 92–99% token savings, and industry observers now describe teams moving away from MCP for coding workflows entirely, preferring direct CLI and API calls. When a protocol’s most active ecosystem niche becomes “tools that help you avoid the protocol’s defaults,” that’s a verdict.
So what should you actually do?
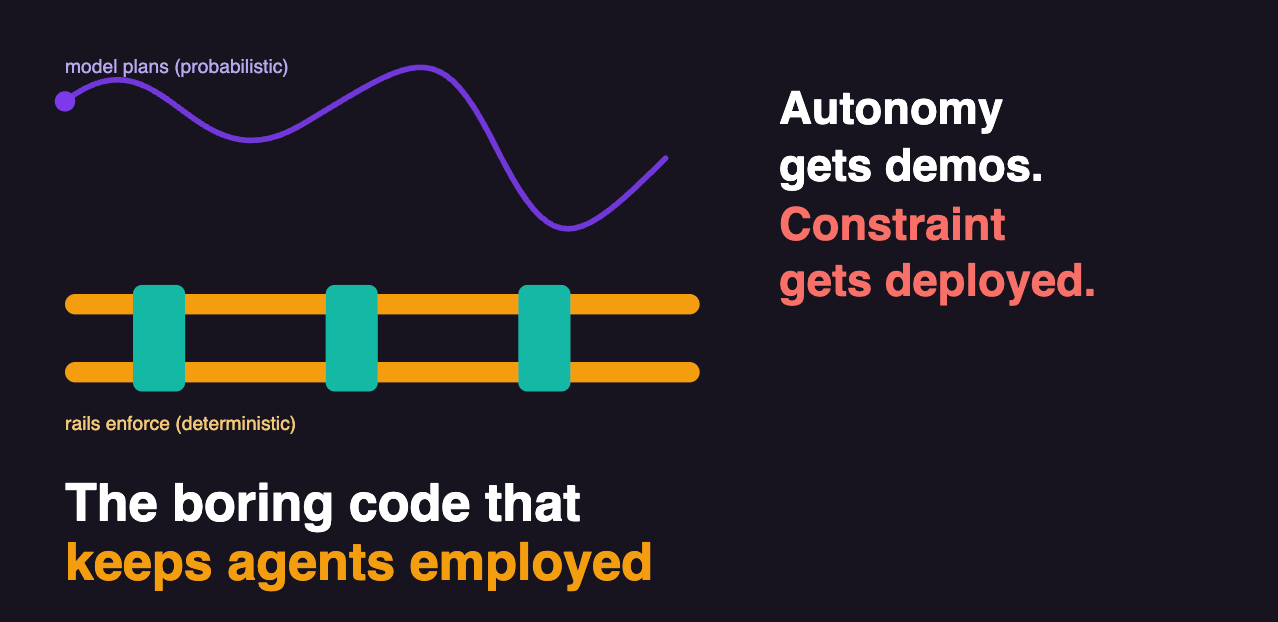
The good news: this isn’t a religious choice. It’s a routing decision, and the decision tree is short.

Figure 3 — The routing decision: identity and blast radius decide the layer, not protocol loyalty.
Practical takeaways
- Audit your standing cost today. Start a fresh agent session, run your tool’s context inspector (in Claude Code:
/context), and look at what's consumed before you've typed a task. If tool schemas eat more than ~10% of your window, you have a routing problem. - Default new coding workflows to CLI. 100% benchmark reliability and near-zero standing cost is the right starting point. Add MCP only when you’ve confirmed you need what it uniquely provides — live external data with per-user auth.
- Write a skill file instead of loading a schema. A ~400-token markdown guide telling your agent which CLI commands to prefer replaced a ~55k-token schema in one measured setup — a 137x cheaper discovery step.
- If you keep MCP, keep it on a leash. Connect to small, task-scoped servers — never the 90-tool mega-catalogs — or put a gateway in front to filter schemas and pool connections.
- Tell your agent your preference explicitly. A pre-session instruction (“prefer CLI for git/GitHub operations; use MCP only for X”) is cheaper than discovering mid-session that it chose the 35x path.
The forty-year-old winner
There’s a pattern in software history that this whole episode rhymes with. We build an elaborate abstraction, the abstraction’s costs surface at scale, and we rediscover that the boring, composable thing — the thing with forty years of accumulated design wisdom — was quietly excellent all along. SOAP gave way to REST. Heavy ORMs gave way back to SQL. And now, in the most futuristic corner of software, the hottest optimization of 2026 is teaching billion-parameter models to use grep.
MCP isn’t dying. It’s being demoted — from “the way agents use tools” to “the way agents use tools when identity and governance are the problem.” That’s a smaller kingdom, but a real one. The mistake was ever believing one protocol should rule every front.
The deeper lesson is the one I keep relearning in this series: token economy is the gravity of agent architecture. Every design choice — your framework, your memory strategy, your tool layer — eventually answers to it. The benchmarks didn’t create that constraint. They just made it visible.
Level up your skills with my Amazon eBooks
Get the The AI Agent Builder’s Playbook : Why AI Agent Projects Die in Production on Amazon.
메타데이터
- post_id
- 3cb0efb33570
- slug
- mcp-is-losing-the-coding-agent-war-and-the-numbers-prove-it-3cb0efb33570
- url
- https://medium.com/system-design-mastery-series/mcp-is-losing-the-coding-agent-war-and-the-numbers-prove-it-3cb0efb33570
- canonical_url
- https://medium.com/system-design-mastery-series/mcp-is-losing-the-coding-agent-war-and-the-numbers-prove-it-3cb0efb33570
- author_url
- https://medium.com/@sureshdotariya
- status
- ok
- fetched_at
- 2026-06-22 00:13:37