What is Reactive Programming + Spring WebFlux
Read for free
What is Reactive Programming + Spring WebFlux
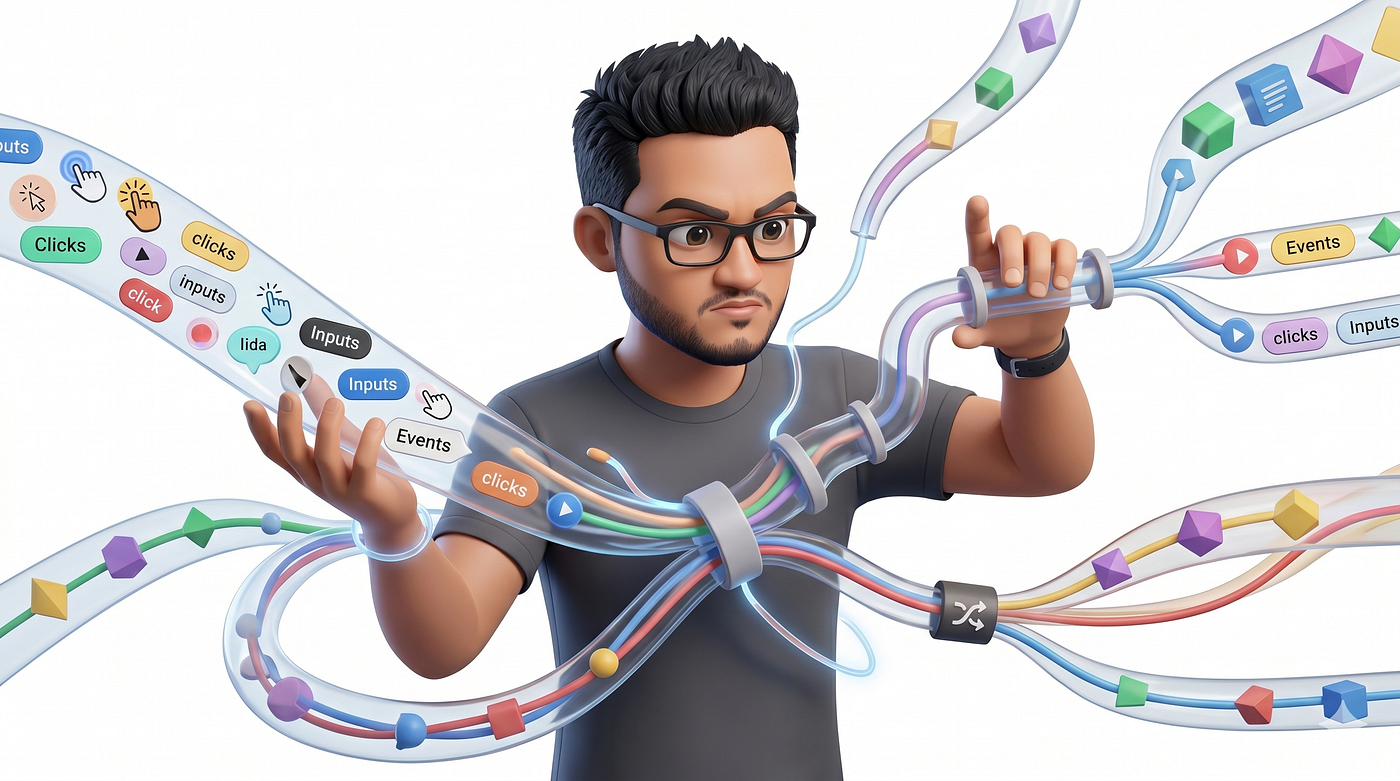
If you’ve been diving into modern software development, you’ve probably heard the buzzword Reactive Programming. It sounds complex, but at its core, it’s a brilliant way to build applications that are incredibly fast, efficient, and responsive.
If you are a student or a fresh graduate looking to level up your software architecture skills, this guide will break down reactive programming step-by-step — explaining the core concepts first, followed by how different languages implement them, and finally closing with a concrete backend example.
Part 1: Understanding Reactive Programming
To grasp reactive programming, we first need to look at how we traditionally write code.
Imperative vs. Reactive
In traditional imperative programming, code executes like a sequential recipe: Step A, then Step B, then Step C. If Step B involves waiting for a slow database or an external API to respond, the entire program execution stops and waits. This behavior is called blocking.
Reactive programming, on the other hand, is entirely non-blocking. Instead of actively waiting for data, your application defines a set of pipelines, steps aside, and reacts whenever new data arrives. It is a paradigm driven completely by asynchronous data streams and the propagation of change.
💡 A Real-World Analogy: Think of imperative programming like checking your physical mailbox every five minutes to see if a package arrived. Reactive programming is like subscribing to SMS notifications; you go about your day, and the moment the package drops, your phone alerts you so you can react to it.
Core Concepts: The Building Blocks
Before looking at any code or specific languages, there are three fundamental concepts you must understand:
1. Everything is a Data Stream
In a reactive world, data is not treated as a static collection or a single fixed value. Instead, everything is a stream of data ordered over time. A stream can be a sequence of user clicks, incoming HTTP requests, or live feeds from a database.
These data streams emit three types of signals:
- A Value: The actual data payload (e.g., a text string or an object).
- An Error: A signal indicating something went wrong, allowing the stream to handle failures gracefully.
- A Complete Signal: A notification that the stream has finished sending data and is now closed.
2. The Observer Pattern
Reactive programming relies heavily on the Observer Design Pattern, which features two primary components:
- The Publisher (Observable): The source that produces and pushes data into the stream whenever it becomes available.
- The Subscriber (Observer): The code that registers interest in the stream. It “subscribes” to the publisher and executes specific logic whenever a value, error, or completion signal is received.
3. Backpressure
What happens if a publisher generates data faster than a subscriber can process it? In a reactive system, backpressure is the mechanism that allows a struggling subscriber to signal to the publisher to slow down, preventing the system from running out of memory or crashing under heavy load.
Part 2: Ecosystem & Implementations
Because reactive programming is a conceptual paradigm and not a specific tool, it is not tied to any single programming language. Almost every major language ecosystem has its own implementation of these reactive principles, usually standardized around the Reactive Streams specification.
- JavaScript / TypeScript: Uses RxJS, which is wildly popular in frontend development for turning UI events, mouse movements, and HTTP requests into clean, reactive pipelines.
- Python: Uses RxPy to create asynchronous, event-based programs.
- C++: Uses RxCPP for high-performance, reactive workflows.
- Java: Has multiple powerful implementations, most notably RxJava and Project Reactor (the engine powering the modern Spring ecosystem).
No matter which language you use, the core concepts — Publishers, Subscribers, Streams, and Backpressure — remain exactly the same.
Part 3: Under the Hood — The Runtime Engine
To achieve high concurrency and non-blocking I/O, reactive frameworks swap out traditional runtime web servers for an event-driven engine. Let’s look at how this operates on the backend using Netty, a highly popular asynchronous network framework.
Tomcat vs. Netty: What’s the Difference?
The fundamental difference lies in how they manage threads and incoming requests.
- Apache Tomcat (Thread-per-Request): Tomcat relies heavily on a large pool of worker threads (historically up to 200+ threads by default). When a request hits Tomcat, one specific thread accompanies the request all the way through the code. If your database call takes 2 seconds, that thread sits idle (“blocked”) for 2 seconds doing nothing. If 200 users hit a slow database simultaneously, Tomcat runs out of threads, and user #201 is stuck in a queue.
- Netty (Event-Driven / Non-Blocking): Netty uses a tiny pool of threads — typically matching your machine’s CPU core count (e.g., just 8 threads on an 8-core CPU). These threads never sit idle waiting for I/O operations. When an API request needs to query a database, the Netty thread registers the query task with the operating system kernel and immediately jumps to handle the next incoming request.
What is an Event Loop?
The Event Loop is the core design pattern that makes Netty’s non-blocking execution model possible. Think of the Event Loop as a continuous, infinite while loop running on a thread. Its sole job is to sit and listen for events (like a new HTTP request arriving, data being read from a socket, or a database returning a query result) and dispatch those events to their respective processing pipelines.
How the Thread Lifecycle Handles an Event:
- The Arrival: A user hits an endpoint, triggering an event in the OS.
- The Loop Picks It Up: The Event Loop detects this notification, grabs the request using an available thread (e.g., EventLoop-Thread-1), and kicks off your pipeline.
- The Delegation: Your code initiates a reactive database call. EventLoop-Thread-1 passes the task to the underlying operating system’s non-blocking I/O layer, registers an internal callback for that network socket, and instantly returns to the top of its loop to see if any other users are trying to connect.
- The Response Event: When the database sends back data, it triggers a “data ready” event. An I/O event notification is sent back to the application server. At this point, the next available thread in the Event Loop thread pool will pick up the event and execute the rest of the stream pipeline to write the final response back to the client.
Important Thread Takeaways:
- It could be a totally different thread: If EventLoop-Thread-1 is busy serving someone else when the database event fires, EventLoop-Thread-2 will handle the response. No threads sit parked waiting for data.
- Don’t block the Event Loop: Because the Event Loop pool is small, you must never write traditional blocking code (like Thread.sleep() or synchronous database calls) inside a reactive pipeline. Doing so risks locking up your entire server.
Part 4: Putting It Into Practice with Java & Spring Boot
To see how these abstract stream concepts translate to real-world code, let’s look at Java’s Project Reactor implementation within Spring WebFlux.
Mono and Flux
Project Reactor implements the Reactive Streams specification by introducing two core stream implementations:
- Mono<T>: A reactive stream that will emit 0 or 1 item (e.g., fetching a specific user by their unique ID).
- Flux<T>: A reactive stream that will emit 0 to many items (e.g., streaming a live list of data rows).
A Reactive Controller Example
Let’s look at a standard Spring Boot REST Controller that handles user profiles asynchronously. Instead of returning a raw object, we wrap our API responses in a Mono or a Flux so the underlying server handles them using non-blocking I/O.
import org.springframework.web.bind.annotation.*;
import reactor.core.publisher.Flux;
import reactor.core.publisher.Mono;

@RestController
@RequestMapping("/api/users")
public class UserController {

    // 1. GET /api/users/42 -> Returns a single user wrapped in a Mono
    @GetMapping("/{id}")
    public Mono<UserResponse> getUserById(@PathVariable String id) {
        // Pretend this mimics a non-blocking database call
        Mono<UserResponse> userStream = Mono.just(new UserResponse(id, "alice"));

        // We cleanly transform data inside the pipeline using operators like .map()
        return userStream.map(user -> {
            user.setName(user.getName().toUpperCase()); // Capitalize name reactively
            return user;
        });
    }

    // 2. GET /api/users -> Returns a collection of users wrapped in a Flux
    @GetMapping
    public Flux<UserResponse> getAllUsers() {
        // Creates a stream emitting multiple data points asynchronously
        return Flux.just(
            new UserResponse("1", "bob"),
            new UserResponse("2", "charlie"),
            new UserResponse("3", "david")
        ).filter(user -> user.getName().length() > 3); // Filter out short names reactively
    }
}

// Simple POJO class for the response body
class UserResponse {
    private String id;
    private String name;

    public UserResponse(String id, String name) {
        this.id = id;
        this.name = name;
    }

    // Getters and setters
    public String getId() { return id; }
    public String getName() { return name; }
    public void setName(String name) { this.name = name; }
}
Part 5: Managing Stream Overflow (Backpressure Examples)
As mentioned in the core concepts, if a data producer sends data faster than a consumer can process it, the application needs a backpressure strategy to manage the overflow. Here is how you can explicitly configure backpressure strategies using Project Reactor:
import reactor.core.publisher.Flux;
import reactor.core.scheduler.Schedulers;
import java.time.Duration;

public class BackpressureDemo {
    public static void main(String[] args) throws InterruptedException {

        // 1. A fast publisher generating numbers every 1 millisecond
        Flux<Long> fastPublisher = Flux.interval(Duration.ofMillis(1));

        // 2. Apply a Backpressure Strategy to handle the overflow
        Flux<Long> backpressurePipeline = fastPublisher
            // .onBackpressureDrop(dropped -> System.out.println(" Dropped: " + dropped)) // Strategy A: Drop extra data
            .onBackpressureBuffer(50) // Strategy B: Keep up to 50 items in memory, error if exceeded

            // Move processing to a separate thread pool so the consumer is slower than the producer
            .publishOn(Schedulers.boundedElastic());

        // 3. A slow subscriber taking 100ms to process each item
        backpressurePipeline.subscribe(
            data -> {
                try {
                    Thread.sleep(100); // Mimic slow processing (e.g., writing to a slow DB)
                    System.out.println("Processed: " + data);
                } catch (InterruptedException e) {
                    Thread.currentThread().interrupt();
                }
            },
            error -> System.err.println("Error due to backpressure: " + error.getMessage())
        );

        // Keep main thread alive for the demo
        Thread.sleep(5000);
    }
}
Core Backpressure Strategies Available:
- .onBackpressureBuffer(maxSize): Holds a specific amount of items in a queue until the subscriber can catch up.
- .onBackpressureDrop(): Instantly discards any data emitted by the publisher if the subscriber is too busy.
- .onBackpressureLatest(): Keeps only the absolute latest item emitted, discarding any previous items.
- .onBackpressureError(): Immediately terminates the stream with an error signal if the consumer falls behind.
Why Should You Care? (The Benefits)
Adopting a reactive mindset gives your backend services several major architectural advantages:
- High Concurrency: Because threads are never blocked waiting for slow I/O operations, a small, fixed pool of threads can handle thousands of concurrent requests simultaneously.
- Resource Efficiency: Your server’s CPU and memory footprints remain low because system resources aren’t wasted on stagnant threads.
- Resilience: Built-in operators make it easy to chain timeouts, retries, and fallback strategies (like .onErrorResume()), keeping your system robust when downstream dependencies fail.
Wrap-Up & Next Steps
Reactive programming shifts your mental model from “doing things sequentially and waiting” to “setting up a pipeline and reacting to data as it moves.” It is a fundamental architecture for building highly scalable modern systems.
Your Actionable Takeaways:
- Shift your perspective: Start looking at data in your applications not as static states, but as moving pipelines over time.
- Explore the tools: Create a playground project using your favorite language’s reactive extension (like RxJS for JavaScript or Spring WebFlux for Java).
- Experiment: Try rewriting a basic REST endpoint to use reactive wrappers, utilizing operators like .map() and .filter() to manipulate your data stream.
Happy coding, and stay reactive!
Follow Me On:
- ▶️ YouTube — http://youtube.com/rusirugunaratne
- 📔 Medium — https://medium.com/@rusirugunaratne
- 👍🏼 Facebook — https://www.facebook.com/rgunaratne/
- 🧑🏼💻 LinkedIn — https://www.linkedin.com/in/rusirugunaratne/
- 📸 Instagram — https://www.instagram.com/rusiru_gunaratne/
메타데이터
- post_id
- a259d2e5f0af
- slug
- what-is-reactive-programming-spring-webflux-a259d2e5f0af
- url
- https://medium.com/@rusirugunaratne/what-is-reactive-programming-spring-webflux-a259d2e5f0af
- canonical_url
- https://medium.com/@rusirugunaratne/what-is-reactive-programming-spring-webflux-a259d2e5f0af
- author_url
- https://medium.com/@rusirugunaratne
- status
- ok
- fetched_at
- 2026-06-21 07:44:09