What Are Tokens? A Simple Explanation for QA Engineers
Understanding how LLMs break text into smaller pieces
What Are Tokens? A Simple Explanation for QA Engineers
Understanding how LLMs break text into smaller pieces

When I started learning how LLMs work, I kept seeing the word token everywhere.
At first, I assumed:
Token = Word
But that’s not quite right.
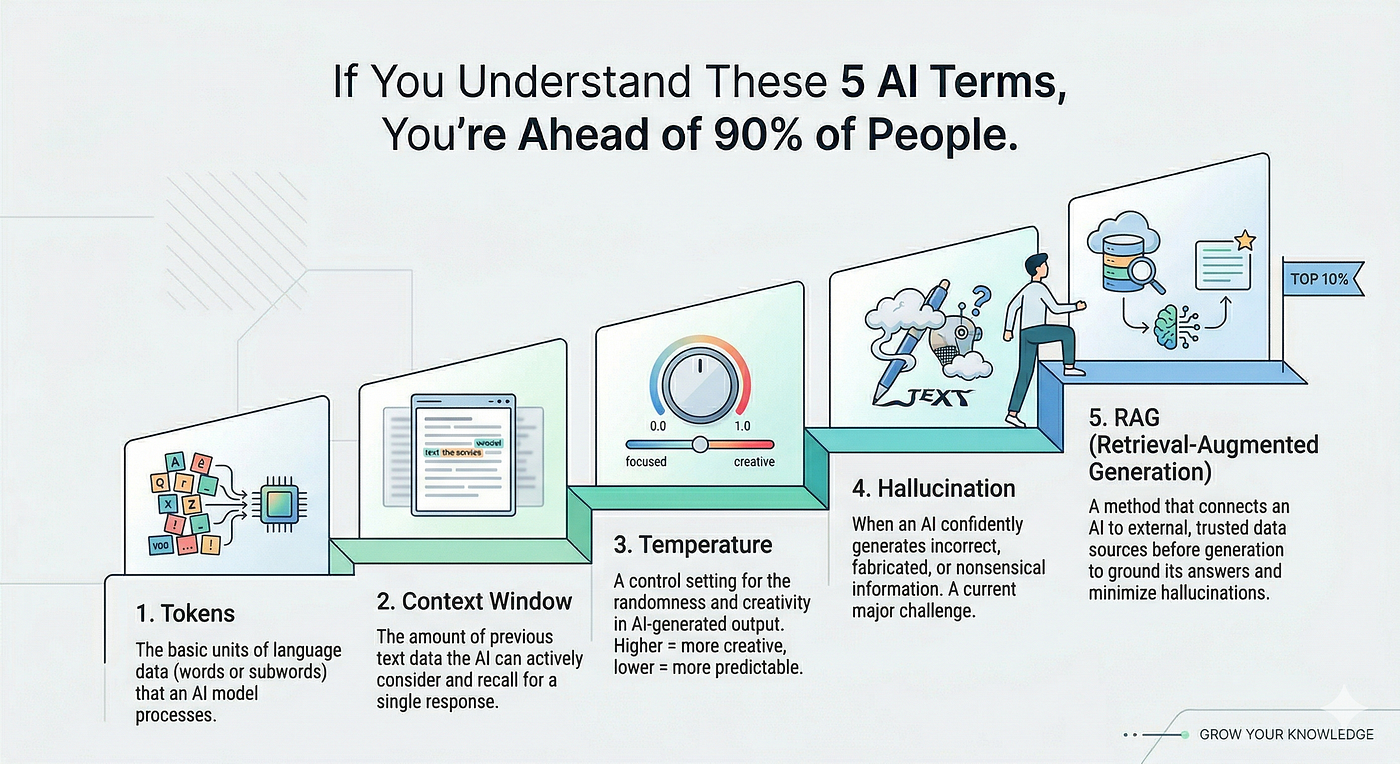
A token is a small piece of text that an LLM processes.
It can be a complete word, part of a word, a number, or punctuation.
Understanding this simple concept helped me understand what happens between our prompt and the response we receive from an LLM.
What Is a Token?
Let’s start with a simple example.
Suppose we give an LLM this prompt:
“Create test cases for a login page.”
At a simplified level, the text can be broken into pieces like:
Create | test | cases | for | a | login | page | .
Each piece represents a token.
So the flow becomes:
Text → Tokens
Note: This is a simplified illustration. Actual tokenization depends on the tokenizer and model being used.
Is Every Token a Complete Word?
No.
This was one of the most useful things for me to understand.
A token doesn’t necessarily represent an entire word.
A longer or less common word may be split into multiple pieces.
For example, conceptually:
testing
↓
test + ing
So we shouldn’t assume:
1 word = 1 token
That’s not always true.
What Can a Token Contain?
Depending on the tokenizer, tokens can represent different pieces of text.
They may correspond to:
Complete words Parts of words Numbers Punctuation Other text patterns
For example:
2026
may be represented differently depending on the tokenizer.
And:
can also be represented as a token.
The exact tokenization depends on the model and tokenizer.
Why Do Tokens Matter?
If you’re learning LLMs, you might wonder:
Why should I care about tokens?
Because token counts are important in several areas.
Context Limits
LLMs have limits on how much input and context they can process.
That limit is commonly discussed in terms of tokens.
So a longer prompt generally means more tokens.
Prompt Design
Understanding tokens helps us think about how much information we’re putting into a prompt.
For example, instead of unnecessarily repeating large amounts of information, we can provide the relevant context clearly.
This becomes especially useful when working with:
Large requirements Documentation Logs API responses Test data Long conversations API Usage and Cost
For many paid LLM APIs, usage is measured using tokens.
So understanding token counts can help when thinking about API usage and cost.
The exact pricing model depends on the provider and model.
Tokens and the QA Engineer
This is where the concept becomes interesting from a QA perspective.
Imagine we ask an LLM:
“Generate test cases for this requirement.”
The requirement itself becomes part of the input.
Conceptually:
Requirement
↓
Tokens
↓
LLM
↓
Generated Response
If the requirement is very large, it can consume a significant number of tokens.
That makes understanding context and token limits useful when designing AI-assisted testing workflows.
Tokens and Prompt Engineering
Tokenization also connects directly to prompt engineering.
Consider two prompts.
Prompt A
“Test login.”
Prompt B
“Generate positive, negative and boundary test cases for a login page. Include valid credentials, invalid credentials, empty fields, password boundaries and account-lockout scenarios.”
Prompt B provides much more context.
That generally means more tokens.
But the goal isn’t simply to minimize the number of tokens.
The goal is to provide useful context while staying within the model’s limits and using the available context effectively.
So the balance is:
Useful context
Clear instructions
Reasonable prompt size
Tokens Connect to What We Learned Earlier
In Day 1, I used this simple mental model:
Prompt → Tokens → Model → Prediction → Response
Now we can understand the second step better.
Prompt
We provide an instruction or question.
↓
Tokens
The input is broken into pieces that the model processes.
↓
Model
The model processes the token sequence and context.
↓
Prediction
The model generates the response progressively.
↓
Response
We see the generated text.
This is one of the basic building blocks for understanding LLMs.
An Important Misconception
One misconception I had initially was:
“A token is just a word.”
A better mental model is:
A token is a piece of text.
Sometimes that piece is a whole word.
Sometimes it’s part of a word.
Sometimes it represents punctuation or another text element.
And different models can use different tokenization methods.
Why This Matters for AI-Assisted Testing
As QA engineers, we are increasingly using AI for activities such as:
Test case generation Test data ideas Requirement analysis API testing assistance Automation support Documentation Debugging assistance
In each case, we’re providing some form of input to the model.
Understanding tokens helps us understand that input at a lower level.
It also helps us understand why things like context limits and prompt size matter.
My Simple Takeaway
I don’t think a QA engineer needs to understand every detail of tokenization before starting to use LLMs.
But knowing this much is useful:
A token is a small piece of text processed by an LLM.
Remember:
Text
↓
Tokens
↓
Model
↓
Prediction
↓
Response
That’s the mental model I’m using as I continue learning how LLMs work.
And the next concept naturally follows:
How Is an LLM Trained?
That’s where we move from what the model processes to how the model learns patterns in the first place.
Key Takeaways A token is a piece of text, not necessarily a complete word. A word can sometimes be split into multiple tokens. Numbers and punctuation can also be represented as tokens. Different models can use different tokenization methods. Token counts matter for context limits. Token usage can matter for API costs. Understanding tokens helps when designing prompts and AI-assisted QA workflows.
Text → Tokens → Model → Prediction → Response
That’s the simple picture to remember.
메타데이터
- post_id
- abf202c4229e
- slug
- what-are-tokens-a-simple-explanation-for-qa-engineers-abf202c4229e
- url
- https://medium.com/@rohithgowda1993/what-are-tokens-a-simple-explanation-for-qa-engineers-abf202c4229e
- canonical_url
- https://medium.com/@rohithgowda1993/what-are-tokens-a-simple-explanation-for-qa-engineers-abf202c4229e
- author_url
- https://medium.com/@rohithgowda1993
- status
- ok
- fetched_at
- 2026-10-02 03:38:02