NONPARAMETRIC DECISION MAKING
TABLE OF CONTENTS
NONPARAMETRIC DECISION MAKING
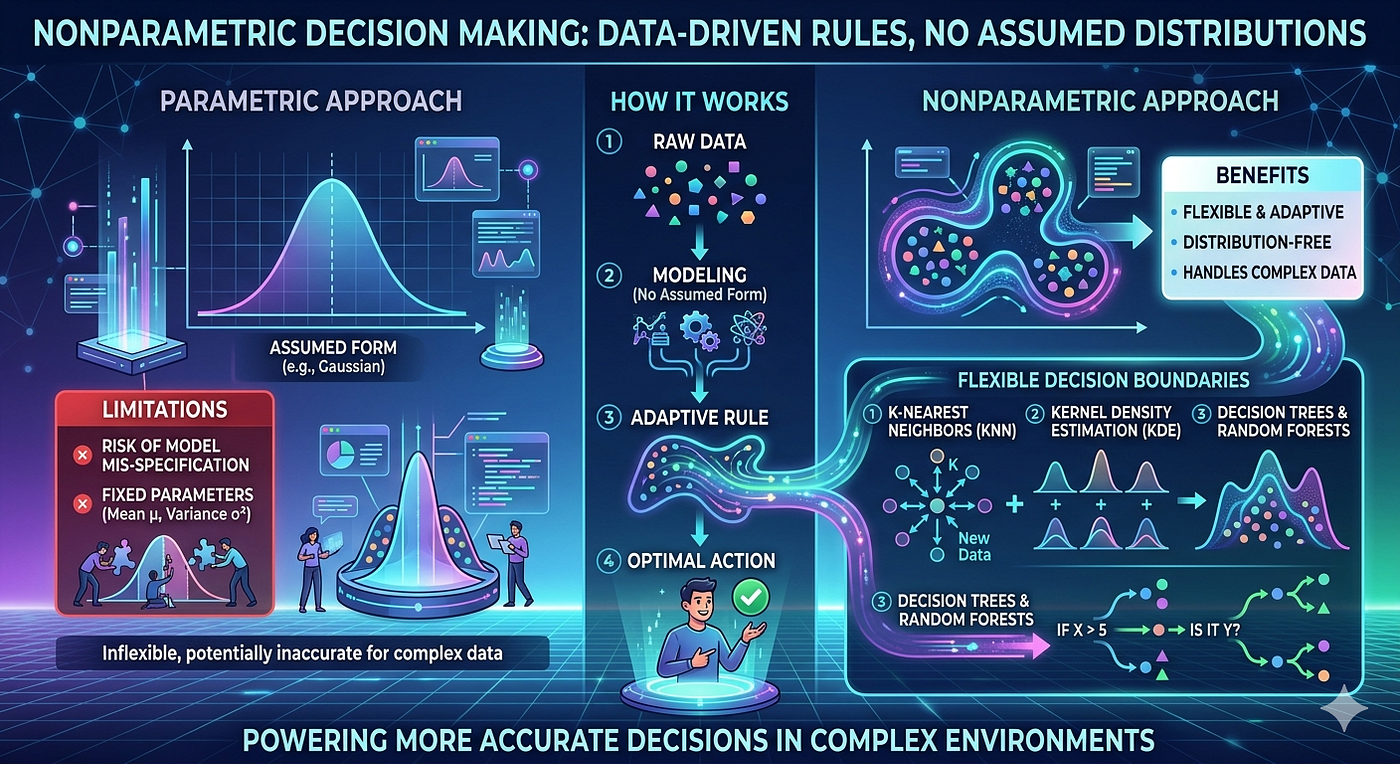
TABLE OF CONTENTS

Contents
Chapter 1: The World Without Parametric Assumptions

Introduction
Pattern recognition systems have been using an assumption. They assume that the probability density functions for each class of data follow a known form. * For example in Chapter 3 of pattern recognition we have assumed data, from each class followed a specific distribution. It could be a Normal distribution or a Poisson distribution. These distributions are shaped by a parameters. To classify data we just had to do two things.First estimate those parameters from training data. Then use them to classify samples.
The systems relied on knowing the distribution type. Gaussian and Poisson are examples of these distributions. They help simplify the classification process. We use training data to get the parameters right. Then we can classify data.

Reality is not always what we want it to be. When we look at real-world data from things like images and financial numbers over time speech recordings and pictures from satellites we see that they do not always fit the usual patterns. The data can have peaks be uneven have extreme values or be too complicated for any simple equation to really get it right. When we try to make this kind of data fit a model it can give us wrong answers make it hard to tell things apart and create systems that stop working when we use them in the real world. Real-world data is, like this and it is a problem because it does not match the patterns so real-world data is hard to work with.

Nonparametric methods do not make any assumptions, about the shape of the
density function. They simply allow the data to show its pattern. This
approach lets the data speak for itself. Nonparametric methods rely on the
data to tell its story. The shape of the density function is not assumed in
methods.
1.1 What Is Nonparametric Decision Making?
Nonparametric decision making is about a group of techniques for classification and figuring out how dense something is. These techniques do not assume that the probability of something belonging to a class follows a specific mathematical pattern. Instead Nonparametric decision making looks at the samples. Tries to understand the density based on what the data shows.
When we have an idea of the density we can use Bayes theorem to make good decisions about classification just like we do when we know the mathematical pattern.This is a help in machine learning because sometimes when we look at graphs or test results they do not follow the usual patterns. We need Nonparametric techniques to still get information, about the density and make accurate classifications. Nonparametric techniques are the tools that help us do that.

Keynotes:
The main thing to understand about methods is that we already know what the
density looks like and we just need to figure out the parameters. On the hand
nonparametric methods are different because we do not know what the density
looks like. So we use the data to estimate the density form of the methods
directly. This means the density can be really complex or really simple it
just depends on what the data tells us about the methods.
1.2 Parametric vs. Nonparametric: A Detailed Comparison
Before we look at nonparametric methods lets see how they are different from parametric methods in real-life situations.
Here are some key differences:

1.3 Road Map: Topics Covered in This Blog
Chapter 2: Histograms as Density Estimators
The histogram is really old. It is also very easy to understand. It is a way
to estimate the density of something. Even though the histogram is simple it
has some problems that are always going to be there when we try to estimate
something without using a lot of rules. These problems are things like trying
to balance being right and being precise being smooth and being accurate and
being simple and being able to show a lot of details. The histogram has all
of these problems, like bias and variance and smoothness and fidelity and
parsimony and expressiveness.
2.1 The Core Idea
Let us say we have a lot of samples like x₁, x₂ and on up to x_N and these samples come from some unknown density p(x) that we want to figure out. To do this we can use something called a histogram. The histogram takes all the values of x. Divides them into separate groups or bins that do not overlap with each other.
For each bin we count how many of our samples fall into it. We then use this count to determine the height of the density estimate for that bin.
To be more precise let us say we have bins called B₁, B₂ and on up to B_m and each of these bins has a certain width, like w₁, w₂ and so on up to w_m. If n₀ is the number of samples that fall into a bin then the density estimate for that bin can be calculated using the following formula:

EQ. 2.1
This formula is important because it makes sure that the total area under the histogram is equal to 1 which means it is a way to estimate the probability density. The area under each bar in the histogram is equal to the fraction of samples in that bin. When we add up all these fractions they equal 1. This is because the area under bar j is (nⱼ/N) × (wⱼ/wⱼ) = nⱼ/N, which is the fraction of samples, in that bin and all these fractions add to 1 when we consider all the bins.

2.2 Equal vs. Unequal Bin Widths
Bins are usually the width. This makes it easier to work with them and the height of the bars in the histogram will show the density of the samples. The histogram will be more accurate because we do not have to adjust the bars.. Sometimes it is better to have bins that are not all the same width.
If the samples have a lot of variation in one area and not much in another area we can use small bins where the samples change a lot and fewer big bins where the samples do not change much. This helps us get an estimate of the samples without using too many parameters.
When the bins are not all the width we have to adjust the height of each bar very carefully. The height of the bar is the number of samples in the bin divided by the width of the bin. We have to do this. The histogram will not be right. If we do not adjust the height of the bars the histogram will show the number of samples instead of the density of the samples. This can be confusing because the histogram will not show what we want it to show. The histogram will show the number of samples, in each bin of the density of the histogram bins. The density of the histogram bins is what we really want to see.

Example

2.3 Choosing the Number of Bins
Choosing the number of histogram bins is a big deal. It is hard to decide. This decision affects how good your histogram is.The right number of bins is a trade-off between being too simple and too complex.In statistics and machine learning this is a problem.You want to pick a number of bins that shows the data well. Few bins can hide details. Many bins can make it noisy. Histogram bins are important for density estimation. The goal is to find a balance. This balance is key, to making a histogram. It helps in making decisions.The right histogram helps in understanding the data.
Too few bins result in variance but high bias. The histogram appears smooth.
However it misses the structure, in the data. On the hand too many bins lead
to low bias but high variance.The histogram looks very jagged.It overfits the training sample.
The square root rule is a way to figure out how many bins to use. It says to make the number of bins to the square root of the sample size. This works out well because it gives us the same number of intervals and the same average number of samples per interval which is the square root of the sample size. This means each scale is roughly equal in terms of precision.
When we are trying to find the approach we should try out a few different values for the number of bins on the training data. We can use a method called cross-validation to see how accurate our classification is. One way to do this is to leave one sample out at a time which’s really convenient. Then we pick the number of bins that gives us the accuracy on the training data. It is really important that we do not use the test set to choose the number of bins. If we do that it is, like using it as a training set, which means our test is not a good way to estimate how well our method really works. The square root rule and the number of bins are important to get right so we can have an estimate of how well our method works.
2.4 Multi-Dimensional Histograms
When the feature space has dimensions like x has d dimensions the histogram gets extended to a grid with many cells. Each cell lets call it B is made by combining intervals, one for each dimension. The density estimate in cell B is calculated like this:

Eqn 2.2
Here the number of samples, in B is counted as n_B and the Volume of B is calculated as width of first interval times width of second interval and so on.

2.5 Bayes Classification from Histogram Estimates
When we have the histogram estimates of p̂(x|Cᵢ) for each class Cᵢ we can use Bayes theorem to find the probability that the sample belongs to a particular class Cᵢ given the data x.
The formula for this is:

P(Cᵢ | x) = p̂(x | Cᵢ) P(Cᵢ) divided by the sum of p̂(x Cⱼ) P(Cⱼ) for all classes Cⱼ.
We then look at the class Cᵢ that has the highest probability P(Cᵢ | x) and assign the sample to that class Cᵢ. This is the decision we can make using Bayes theorem and the estimated densities of the classes Cᵢ.
If the classes Cᵢ are equally likely to happen then we just choose the class Cᵢ that has the highest density estimate, at the point x.
Example

The histogram is not very good at showing the density because it has big jumps
at the edges of each bin. This is a problem with the way we make the histogram
it is not really what the true density looks like.Kernel estimators are a way
to do this. They take each piece of data. Replace it with a smooth curve that
is the same on both sides. This makes the density estimates very smooth,
like the curves that we use to make them.
Chapter 3: Kernel Estimators & Parzen Windows
The histogram is not very good at showing the density because it has big jumps at the edges of each bin. This is a problem with the way we make the histogram it is not really what the true density looks like.
Kernel estimators are a way to do this. They take each piece of data. Replace it with a smooth curve that is the same on both sides. This makes the density estimates very smooth, like the curves that we use to make them.

3.1 From Histogram to Kernel Estimator
The idea behind kernel density estimation is really simple. We do not just put each sample point in a bin. Count it once for that bins density. Instead kernel density estimation places an symmetric function, which is called the kernel in the middle of each sample point. The density estimate at any point like the point x is the sum of what we get from all the kernel functions when we evaluate them at the point x.
To be more formal about it let us say we have N samples, which’re x₁, x₂ and so on up to x_N. Then the kernel density estimate is given by the equation:

P̂(x) = (1/N) Σᵢ K_h(x. Xᵢ) = (1/Nh) Σᵢ K((x. Xᵢ)/h)
Here the kernel function is K and h is a number that’s greater than 0, which we call the bandwidth. Sometimes people also call the bandwidth the window width or the smoothing parameter. The kernel function K has to satisfy a conditions.
First the integral of K(u) with respect to u must be equal to 1.
[Constraint 1] This means ∫ K(u) du = 1, which basically says that the area under the curve of the kernel function is 1.
Next, K(u) must be greater than or equal to 0.
[Constraint 2] This just means that the kernel function K(u) is never negative.
Lastly the kernel function K(u) must be symmetric about zero.
[Constraint 3] This means K(u) = K(-u) which is usually the case, for kernel density estimation.

3.2 Common Kernel Functions
Many functions can be used as kernels. The shape of the kernel does not make a difference in how well the density is estimated. What really matters is the bandwidth. Different kernels have properties when it comes to computing and theory and that is what sets them apart. The kernel shape is not as important, as the bandwidth when it comes to getting a good density estimate. Kernels have properties and these properties are important to consider when choosing a kernel.

The Epanechnikov kernel is really good because it reduces the error in the
run. The Epanechnikov kernel is great at minimizing the mean integrated
squared error.People usually use the Gaussian kernel instead of the
Epanechnikov kernel. The Gaussian kernel is popular because it works for
all numbers and it is very smooth. The Gaussian kernel produces estimates
that're also very smooth, just, like the kernel itself the Gaussian kernel.
Example


Input

Impule function
Step-1

Step-2

Step-3


Step-5

메타데이터
- post_id
- b3c5d28318f0
- slug
- nonparametric-decision-making-b3c5d28318f0
- url
- https://medium.com/@rmdi115/nonparametric-decision-making-b3c5d28318f0
- canonical_url
- https://medium.com/@rmdi115/nonparametric-decision-making-b3c5d28318f0
- author_url
- https://medium.com/@rmdi115
- status
- ok
- fetched_at
- 2026-08-16 00:49:26