🌐 Why Fewer Network Calls Matter More Than Faster Ones
When teams talk about performance, the conversation usually goes like this:
🌐 Why Fewer Network Calls Matter More Than Faster Ones

🌐 Why Fewer Network Calls Matter More Than Faster Ones
When teams talk about performance, the conversation usually goes like this:
“Can we make this request faster?” “Can we shave off a few milliseconds?” “Can we optimize serialization?”
But in production systems, speed is rarely the real problem.
The number of network calls is.
🚦 Latency Is Additive, Not Isolated
A single network call might take 20 ms.
That sounds fine.
Now chain five of them:
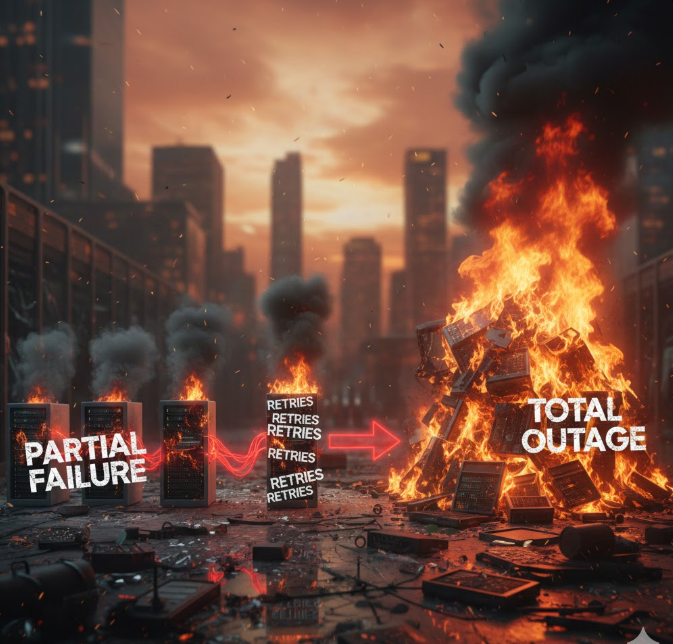
Service A → Service B → Service C → Service D → Service EEven if each call is “fast,” the total latency adds up — and that’s before retries, timeouts, or partial failures.
Performance doesn’t degrade gradually.
It compounds.
🔁 Every Network Call Is a Failure Opportunity
A network call can fail because of:
- Timeouts
- DNS issues
- Packet loss
- Thread pool exhaustion
- Downstream overload
When you make more calls, you don’t just increase latency — you increase uncertainty.
Fast calls still fail.
🧠 Distributed Systems Fail Between Components
Most production incidents don’t happen inside services.
They happen between them.
More network calls mean:
- More coordination
- More coupling
- More cascading failures
- Harder debugging
This is why reducing calls often stabilizes systems more than optimizing code.
📦 Chattiness Hurts More Than Payload Size
Consider this REST pattern:
GET /user/{id}
GET /user/{id}/orders
GET /user/{id}/preferences
GET /user/{id}/notifications
Each request:
- Adds latency
- Consumes threads
- Creates retry potential
- Requires error handling
A single, slightly larger response is often cheaper than four “small” ones.
⚡ Faster Serialization Doesn’t Fix Network Math
Switching from JSON to Protobuf helps.
So does gRPC.
But none of that changes this truth:
The slowest part of distributed systems is coordination, not computation.
Reducing calls beats optimizing format every time.
🧪 Fewer Calls = More Predictable Behavior
When systems make fewer network hops:
- Latency variance shrinks
- Failure modes are clearer
- Load spikes are easier to handle
- On-call debugging is faster
Predictability improves — and that’s the real performance win.
🧱 This Is Why Aggregation Patterns Exist
Patterns like:
- Backend-for-Frontend (BFF)
- API Gateways
- Query aggregation
- GraphQL (used carefully)
…exist for one reason:
To reduce round trips.
Not to be clever — but to be stable.
🧠 Senior Engineers Optimize for Flow, Not Speed
Junior engineers ask:
“How fast is this call?”
Senior engineers ask:
“How many calls does this path make?”
Because they’ve seen fast systems collapse under coordination overhead.
✨ Final Thought (This Sticks)
Fast calls feel good in isolation.
Fewer calls feel good in production.
If you want real performance:
- Reduce hops
- Collapse chatty paths
- Design APIs around use cases, not resources
Because in distributed systems, less talking beats faster talking.
💬 Medium Engagement Hook
Where is your system most chatty — and what would break if you reduced those calls?
메타데이터
- post_id
- e76f0655fe06
- slug
- why-fewer-network-calls-matter-more-than-faster-ones-e76f0655fe06
- url
- https://systemweakness.com/why-fewer-network-calls-matter-more-than-faster-ones-e76f0655fe06
- canonical_url
- https://systemweakness.com/why-fewer-network-calls-matter-more-than-faster-ones-e76f0655fe06
- author_url
- https://medium.com/@gangoladeepa
- status
- ok
- fetched_at
- 2026-08-27 16:19:55