The Busy Mom Syndrome
Why your AI reasons better on Sunday morning than Tuesday afternoon
The Busy Mom Syndrome
Why your AI reasons better on Sunday morning than Tuesday afternoon
Authors: Fatih E. Nar, Robert Shaw, Taneem Ibrahim | Reviewers: David Whyte-Gray, Alexander Matveev
“Why does my AI reason better on Sunday morning than Tuesday afternoon? Same model. Same prompt. Same context. Somehow different quality outcomes.”
Busy Mom
The Observation Nobody Talks About
You’re not hallucinating 🙂.
Same Claude, same Gemini, same Qwen3 — same model.
Same prompt you ran three days ago.
But on a Tuesday afternoon the answer feels shallower, reasoning less crisp, coherence across a long context slightly off.
On a Sunday morning the same model feels sharper, actually reads your full context and holds the thread longer and better.
The instinct is to blame your prompt, or chalk it up to model randomness. It’s neither. It has a name; multi-tenant inference contention.
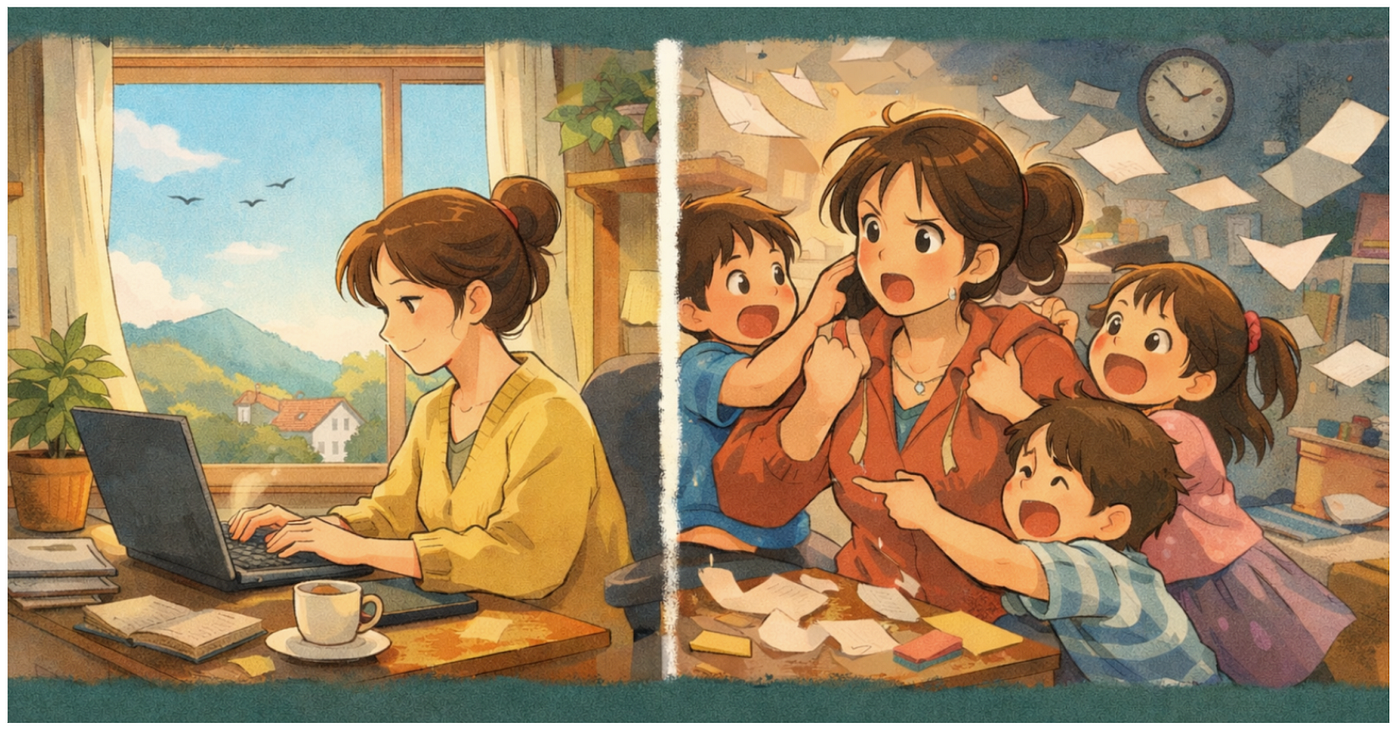
Any parent recognizes the pattern immediately. A mother with one child asking a question is patient, thorough, coherent. That same mother with five kids all demanding attention simultaneously? She still loves them all equally. The intelligence did not change. The quality of each individual answer did, not because she became less capable, but because the resource contention became real.
The model weights did not change. The platform resources they’re running on did.
The Engineering Reality: What Gets Squeezed
Before we talk about feelings and who’s wrong (it is us, not you), let’s talk about memory math. Because this is a physics problem, not a perception problem. The root cause is a hardware tension that predates LLMs: GPU compute doubles roughly every two years, memory bandwidth improves far more slowly. For example; an Nvidia H100 peaks at 1000 TFLOPs of compute per second which is enough in theory, for an 8B model to generate 62,000 tokens per second. However in practice you get 200.

The Memory Wall; Why Your GPU Idles
The gap exists because LLM decode is memory-bound; every output token requires streaming the entire model from GPU memory to the processor, and at H100’s 3.2 TB/s bandwidth that ceiling is exactly 200 transfers per second. The processor idles waiting for weights to arrive. Every production serving framework — vLLM, SGLang, TensorRT — is ultimately an engineering fight against that constraint. The primary weapon in that fight is the KV cache.
The KV Cache: Your Context Lives Here
Every transformer model maintains a Key-Value cache during inference, which is the computed attention state for every token in your context. This is what allows the model to remember your document without re-processing it from scratch on each generation step.
Without the KV cache, every output token would require full re-attention over the entire input. With it, generation is fast and contextually coherent and consistent.
The memory cost per token is model-specific and calculable. The formula has two multipliers that are easy to confuse; the leading 2 is the K+V factor (you store both Key and Value tensors), and precision_bytes is 2 for FP16 or 1 for FP8:
KV cache per token (bytes) = 2(K+V) x n_layers x n_kv_heads x head_dim x precision_bytesThis formula applies to full attention with Grouped-Query Attention (GQA). Sliding window attention and MLA architectures use different KV cache formulas with different memory footprints.
Real numbers on the Qwen3 dense model family, which uses Grouped-Query Attention (GQA) with 8 KV heads, a deliberate architectural choice that trades marginal representational capacity for significantly lower cache pressure:
Qwen3–8B (GQA, FP16): 2(K+V) x 36 layers x 8 KV heads x 128 head_dim x 2(FP16 bytes) = 147,456 bytes ~ 0.14 MB/tokenQwen3–32B (GQA, FP16): 2(K+V) x 64 layers x 8 KV heads x 128 head_dim x 2(FP16 bytes) = 262,144 bytes ~ 0.25 MB/tokenNow scale to a real request. A single Qwen3–8B call at 8K tokens — a typical agentic session with tool calls and context carryover — consumes:
8,192 tokens x 0.14 MB = 1.12 GB of KV cache, per requestAn H100 SXM 80GB with Qwen3–8B loaded (~16 GB weights in FP16) leaves roughly 56 GB for KV cache at vLLM default 0.90 gpu_memory_utilization. That sounds generous. Do the math:
56 GB / 1.12 GB per request ~= 49 concurrent 8K-token requests (theoretical ceiling)Now enable thinking mode, Qwen3’s extended chain-of-thought reasoning and your context window expands to 32K tokens:
32,768 tokens x 0.14 MB = 4.5 GB per request
56 GB / 4.5 GB ~= 12 concurrent requests
At 128K context (document analysis, long reasoning chains), a single Qwen3–8B request consumes 18 GB of KV cache. You fit three on an H100 before the cache is full. On a shared cloud endpoint, you have zero visibility into which slot your request occupies or whether any slots remain.
The ceiling on a dedicated H100 is already tight. On shared infrastructure, that ceiling belongs to someone else.
Real eviction begins before the ceiling. vLLM’s gpu_memory_utilization defaults to 0.90, but KV cache eviction pressure starts at approximately 85% GPU memory utilization. For Qwen3–8B on a single H100, the practical safe pool is ~52 GB — dropping concurrent capacity to ~46 at 8K context and ~11 at 32K before quality degradation begins.
Move to Qwen3–32B and the math gets harder faster. At ~65 GB for model weights, you need at minimum two H100s in NVLink configuration just to load the model with meaningful KV headroom. At 32K context in thinking mode, each request consumes 8 GB of KV cache — leaving room for roughly 9 concurrent sessions on a dual-H100 node before eviction begins silently rewriting your inference quality.

Ceiling = 90% gpu_memory_utilization (vLLM default). Eviction = 85% utilization threshold.
That is not a warning message. It is a scheduler decision. You will not see it in your response.
What Happens When the Cache Fills: Preemption & Recompute
When KV cache capacity is exhausted under load, vLLM does not fail gracefully but it preempts. When this triggers you would see:
WARNING: Sequence group 0 is preempted by PreemptionMode.RECOMPUTE mode because there is not enough KV cache space. This can affect the end-to-end performance.
total_cumulative_preemption_cnt=1
RECOMPUTE mode means the server evicts the entire PagedAttention block table for your request and recomputes the full prefill from your original prompt tokens when capacity is available again. Two immediate consequences follow:
- Latency explosion: The prefill phase must run again from scratch. For a 4K-token context, full prefill recomputation takes hundreds of milliseconds before you receive a single new output token.
- Batch composition variance: vLLM RECOMPUTE re-runs the full prefill correctly, RoPE positional encodings are reapplied from scratch and token positions are not disrupted. However, floating-point operations across different batch compositions are not bit-identical. When your request recomputes under a different concurrent batch than the original prefill, attention score distributions shift at the margins. For most workloads this is negligible. The cases where it matters are deterministic reproducibility requirements where rerunning the same prompt must return the same output and long reasoning chains where early token distributions condition the entire generation path, making small shifts compound across hundreds of decode steps and produce drift that is difficult to reproduce or debug. This output variance across batch compositions is a documented vLLM behaviour (GitHub issue #27433) and is most relevant for RL rollout pipelines and analytical workloads with strict reproducibility SLAs.
These two consequences are specific to self-hosted vLLM under load. Cloud-hosted services operate at a higher level of the stack and the mechanisms are different in kind, not just degree.
How Cloud AI Platforms Degrade Quality Under Load
Cloud inference providers applying quality pressure under-load are not doing anything undocumented or surprising, they are making rational economic decisions under finite GPU capacity. The difference is that none of it is visible to you. The evidence is in provider system cards, official architecture documentation, and peer-reviewed benchmarks.
The most visible layer is model substitution where the platform silently serves you a different, cheaper model than the one you think you are talking to.
- Quota-triggered model downgrade: This is the most direct and documented mechanism. OpenAI’s published GPT-5 system card states explicitly; a real-time router decides which internal sub-model handles each request, and once usage limits are reached, a mini version of each model handles remaining queries. On a busy Tuesday afternoon, millions of users simultaneously approach their rolling usage quotas. The platform silently routes them to a cheaper, smaller sub-model. The API response carries no flag. The model name in the response header does not change. The user experiences a quality drop with no explanation. This is not theoretical, it is the published production architecture.
- Quality-band routing under load: Microsoft’s Azure AI Foundry model router documentation describes its default Balanced mode as selecting models within a quality tolerance band of 1–2% below the highest-quality option for that prompt, choosing the most cost-effective model within that band. In Cost mode the tolerance band widens to 5–6%. Under peak traffic, cost pressure shifts routing toward the lower end of that band. The user gets a model that is within the acceptable quality range for the provider’s economics — not necessarily the model that would give the best answer for their specific workload.
- Silent model drift: A peer-reviewed study by Chen, Zaharia, and Zou (Stanford and UC Berkeley, arxiv:2307.09009) benchmarked GPT-3.5 and GPT-4 at the same API endpoint across two points in time between March 2023 and June 2023, with no model version change disclosed by OpenAI. GPT-4 accuracy on prime number identification dropped from 84% to 51% between March and June. Code generation formatting degraded in both models. The paper’s conclusion; the behavior of the same LLM service can change substantially in a relatively short time, and when and how updates occur is opaque. The Busy Mom observation, same model, different quality which has peer-reviewed empirical confirmation. The causes remain undisclosed by the provider.
Below model substitution sits the infrastructure layer where the serving stack silently compresses, truncates, or drops the context your request depends on.
- Context compaction and truncation: When a conversation or agentic session grows long enough to approach context limits under load, cloud providers silently compress earlier conversation history into a shorter summary representation, or truncate it entirely. This is observable in tools like Claude & Cursor, which surface a compaction notice when a thread becomes long. In production API contexts it happens without notification. The model reasons over a compressed or partial version of your original context, and the quality of answers referencing earlier parts of the conversation degrades accordingly.
- Quantization pressure on complex workloads: Production inference at scale runs quantized model variants. FP8 quantization is near-lossless and widely deployed. However, more aggressive INT4 quantization which delivers 2.7x throughput improvement and dramatically expands concurrency capacity under memory pressure which has a measurable accuracy impact on exactly the workloads where users notice quality degradation. Benchmarks across multiple model families show INT4 formats degrade performance on GSM8K math reasoning earlier than other task types, and MT-Bench evaluation shows quantization significantly reduces performance in coding and STEM tasks. These are not edge cases. They are the primary workloads where Busy Mom quality drops are perceived.
- Token-level KV cache compression: At the scale of infrastructure serving hundreds of millions of concurrent sessions, some operators apply token-level compression strategies beyond block-level preemption such as; scoring individual tokens for importance and permanently dropping low-scoring tokens from the cache. Unlike RECOMPUTE, dropped tokens are not recovered. Research documents the quality impact of this class of eviction; a 2025 study (arxiv:2511.04686) found coherence failure appearing by turn 9–10 in multi-turn conversations under eviction pressure, and a complementary benchmark across 16 LongBench tasks (arxiv:2510.13334) confirmed that as cache availability drops, reasoning, QA, and summarization accuracy all degrade. Whether specific providers deploy this mechanism is not publicly disclosed but the academic literature exists precisely because the engineering pressure to build it is real.
The result is an answer that feels shallower. The model missed something because the platform silently substituted a cheaper model, compacted your context, or dropped the tokens it needed to reason over.
The latency side of this degradation is directly measurable. A reported benchmark from the vLLM community (GitHub issue #20469) shows what queue collapse looks like in practice with Qwen3–14B-AWQ on a single A100 80GB, using vLLM’s own benchmark_serving.py with 16K input tokens:

Source: vLLM community benchmark, GitHub issue #20469. P99 TTFT nearly triples from concurrency 1 to 5. At concurrency 25, the system enters queue collapse. The model is unchanged. These numbers measure latency SLO breach. The quality degradation mechanisms described above operate independently and are not captured here.
The high throughput does not equal high goodput.
vLLM’s own documentation defines goodput as the fraction of requests meeting latency SLOs. A system can run at 90% GPU utilization and show impressive throughput numbers while simultaneously failing 40% of requests on their TTFT SLO.
The Prefix Cache Hit Rate: The Hidden Quality Lever
KV cache eviction is a capacity problem when the GPU runs out of memory and blocks must be freed. Prefix cache miss is a separate and distinct routing problem in which your request lands on a pod that holds no cached context for your session, forcing a cold prefill regardless of whether the overall system has memory headroom. Both degrade quality. They have different causes, different mitigations, and different observability signals. Under peak load both compounds simultaneously.
This matters especially in agentic workflows. When an AI agent runs a multi-step pipeline with calling tools, accumulating results, passing context forward where the same system prompt and conversation history is re-submitted with every new step. Without prefix caching, the serving layer re-processes that entire prefix from scratch on every request. With prefix caching, KV blocks for that shared prefix are computed once and reused across all subsequent steps in the same session. vLLM’s prefix caching feature makes this explicit; system prompts, document preambles, and accumulated conversation history are computed once and served from cache for all matching requests. In a 10-step agentic pipeline on a 4K-token system prompt, prefix caching eliminates 9 out of 10 full prefill computations for that shared context. The cold prefill cost is what you pay when that cache is cold or when load balancing routes your request to the wrong pod.

Production operational thresholds
According to Red Hat Developer benchmarks on llm-d’s KV cache-aware routing (developers.redhat.com, October 2025), cache-aware scheduling achieved an 87% overall cache hit rate versus 30–40% with cache-blind round-robin routing, and an 88% reduction in TTFT for warm cache hits versus cold recompute. This is corroborated by the llm-d project’s own benchmark blog (llm-d.ai/blog/kvcache-wins-you-can-see), which shows precise prefix-cache scheduling maintaining the lowest mean TTFT and highest throughput at rising QPS rates compared to approximate and random scheduling. Cache-blind load balancers scatter requests across pods randomly. Your request lands on a pod with zero cache locality for your context. Cold prefill. Every time.
87% hit rate vs 30% is not a tuning parameter. It is a product quality decision.
The Batching Tax on Performance
Continuous batching, the core scheduler mechanism in vLLM and every production serving framework, admits new prefill requests into running decode batches to maximise GPU utilisation. Under high concurrency, your decode phase gets preempted mid-sequence to process incoming prefill from newly arrived users.
Practical result; your token generation becomes bursty. ITL (Inter-Token Latency) spikes. Instead of a steady 20ms per token, you see 20ms-20ms-20ms-200ms-20ms-180ms as prefill operations for other users who interrupt your decode stream.
The direct quality impact is client-side timeout. When ITL spikes cause a response to exceed the client or gateway timeout window, generation is truncated mid-output. For standard responses this means an incomplete answer. For thinking-mode models running extended chain-of-thought reasoning, truncation cuts the reasoning chain before it reaches a conclusion before even the model was mid-thought. The output you receive reflects an incomplete reasoning path, not a complete one that ran fast. The E2E latency formula makes the compounding effect clear:
E2E Latency = TTFT + (n_output_tokens x TPOT)

where:
 TTFT = queue_delay + prefill_time + (recompute_overhead if preempted)
 (Time To First Token: the wait from request submission to receiving
 the first generated token; inflates under queue pressure and preemption)
TPOT = generation_time / output_tokens
 (Time Per Output Token: the per-step generation speed after the first
 token; degrades with batching pressure)
Under-load, both TTFT and TPOT inflate.
For a 500-token response with a 30-second client timeout, a TPOT spike from 20ms to 200ms reduces your safe output budget from 1,500 tokens to 150 before the connection times out. That is not a cosmetic difference.
The Shared Tenant Reality Nobody Talks About
When you use a cloud-hosted AI service, you are sharing GPU compute pools, KV cache memory banks, network bandwidth, and scheduler priority queues with everyone else on the platform simultaneously.
Peak weekday business hours; enterprise customers, automated agentic pipelines, developer CI workflows, and millions of consumer users all competing. Sunday morning; low contention, a disproportionately generous slice of the same infrastructure for whoever happens to be working.
The effect hits hardest on exactly the workloads where it matters most with long context-heavy prompts, multi-turn reasoning chains, and deep technical analysis. These are the workloads where KV cache pressure bites first, because maintaining coherent attention over a large context window is the first thing the serving stack sacrifices to protect global throughput SLOs.
You’re paying the same price for a measurably worse product during business hours. Classic noisy neighbour crime. New victims.
What You Can Actually Do About It
As an End-User
- Schedule your heaviest cognitive work for off-peak hours. You’re probably doing this intuitively on weekends and now do it deliberately.
- Break very long contexts into modular, independently coherent chunks. Smaller KV footprint per request means less eviction risk and more coherent attention.
As an Enterprise or Platform Operator
The signals are already in your stack. You just have to look at the right ones first.
Monitor vllm:kv_cache_usage_perc via the Prometheus /metrics endpoint. A sustained reading above 85% under load is your early warning signal — not TTFT. TTFT is the lagging indicator. Cache pressure is the leading one.
Right-size GPU memory allocation for peak concurrency using the formula:
Max concurrent = available_KV_cache_GB x 1024 / (avg_seq_len x per_token_MB)

Example: Qwen3–8B on H100 80GB, 8K avg context:
(80 x 0.9–16) GB / (8192 x 0.14 MB) ~= 49 theoretical max
At 85% eviction threshold: ~= 46 practical limit
This formula assumes uniform sequence length equal to the average. In production agentic workloads, sequence length distribution has a long tail; the P95 session length is commonly 3 to 5 times the average. Applying the formula against average sequence length and operating near the theoretical ceiling will still trigger eviction under tail load. Use a conservative multiplier of 0.5 to 0.6 against the theoretical max to establish a safe operating ceiling for production SLA commitments.
- Evaluate dedicated inference capacity for SLA-sensitive workloads. Shared pools are fine for bursty, latency-tolerant workflows. For agentic pipelines, customer-facing reasoning, or autonomous network operations, the hidden quality cost of contention changes the economics.
- For telco-grade AI platforms: QoS-aware inference scheduling is a first-class design requirement, not an afterthought. KV-cache-aware routing that directs requests to pods holding their relevant prefix cache is the right direction.
What This Really Means
The busy mom did not get less intelligent on Tuesday. She got less available. Our presented evidence just finally gives that observation a name.

Relaxed vs Busy Days
We spent a decade learning that cloud infrastructure quality is not a static property but a dynamic outcome of load, contention, and how well you manage both. We built observability stacks, SLAs, and capacity models for compute, storage, and networking because we learned the hard way that assuming quality will exist -> is a big sin. That lesson did not expire when the workload became intelligent.
The weights are static, everything around them is not.
Inference quality is not a model property to trust blindly, it is an AI platform property to instrument, measure, and enforce.
We believe the same discipline that made cloud infrastructure production-grade is exactly what AI layer needs.
What SLA are you actually enforcing on your AI response quality? Do you even measure goodput?
메타데이터
- post_id
- e8a8829ae3db
- slug
- the-busy-mom-syndrome-e8a8829ae3db
- url
- https://medium.com/enterpriseai/the-busy-mom-syndrome-e8a8829ae3db
- canonical_url
- https://medium.com/enterpriseai/the-busy-mom-syndrome-e8a8829ae3db
- author_url
- https://medium.com/@fnar
- status
- ok
- fetched_at
- 2026-06-22 00:35:52