Language Modeling with Neural Networks
Feel free to take a look at my previous article on basic (n-gram) language models here…
Language Modeling with Neural Networks
Feel free to take a look at my previous article on basic (n-gram) language models here: https://www.linkedin.com/pulse/language-models-sonal-prasad-2qf0c/?trackingId=47MDLmhdRtG9n52kVDJUCQ%3D%3D
How do language models predict the next word from previous words?
What You’ll Learn
- Compare n-gram vs. neural language models
- Understand the forward computation in a feedforward neural LM
- Learn what the model trains and what it produces (next-word probability distribution)
A Quick Mental Model
Before we get into the math, it helps to have a simple “pipeline” in mind. A feedforward neural language model is basically a function that takes a fixed-size window of previous words and returns a probability distribution for the next word.
At a high level, each prediction looks like this:
- Choose a context window: The model looks at the last N words (for example, N = 3): “the dog gets”.
- Turn words into IDs (indices): Each word is mapped to an integer ID using a vocabulary (a dictionary of all known words).
- Convert IDs into vectors (embeddings): You can think of this step as a lookup: each word ID maps to a dense vector (its embedding) from an embedding matrix E.
- Combine the context vectors into one input: The model concatenates the embeddings for the N previous words into a single long vector.
- Run that vector through a small neural network: A hidden layer applies weights and a nonlinearity to produce a representation of the context.
- Output next-word probabilities (softmax): The final layer produces a score for every word in the vocabulary, and softmax converts those scores into probabilities that sum to 1. The word with the highest probability is the model’s best guess for the next word.
During training, the model repeatedly does this prediction on real text and updates its parameters so that the true next word becomes more likely over time.
Language Modeling with Neural Networks
According to Jurafsky [1], “A language model is a machine learning model that predicts upcoming words. More formally, a language model assigns a probability to each possible next word, or equivalently gives a probability distribution over possible next words.” A language model is an application of Natural Language Processing (NLP). Modern NLP is based on the transformer architecture, which will be covered in a future article. For now, we will take a look at a simpler version of neural language models known as feedforward networks (or feedforward neural language model), but still more advanced than n-gram language models.
N-Grams vs. Neural Language Models
Neural language models are an improvement from n-gram models. Feel free to learn more about n-gram language models here: https://www.linkedin.com/pulse/language-models-sonal-prasad-2qf0c/?trackingId=47MDLmhdRtG9n52kVDJUCQ%3D%3D.
Neural language models can generalize better, compared to n-grams, since they capture syntactic relationships and capture meaning. For example, let’s take the sentence “I have to make sure that the cat gets fed.” The context window is “the dog gets”, and the neural language model outputs the following probability distribution: fed (0.22), wet (0.05), etc. The neural language model can now reasonably predict ‘fed’ after ‘the dog gets’ even if it never saw that exact phrase in training. It can predict “fed” after “the dog gets” because “cat” and “dog” have similar embeddings, but the n-gram language model cannot do that. The n-gram language model will predict “fed” after seeing “that the cat gets,” but not if the phrase is “that the dog gets.” Neural language models can also handle larger context and have more accurate predictions. On the other hand, n-grams are simpler, faster to train, have smaller computational complexity, are more interpretable, and are preferred for smaller tasks.
Feedforward Neural Language Model (LM)
The feedforward neural LM estimates the next word based on the prior context, or previous words. It generates a probability distribution over possible next words. The context, or previous words, are represented by their embeddings, which allows for better generalization to unseen data.
Forward Inference In Feedforward Neural Language Model
The inference generates a probability distribution over the next possible words. Here is how it does that. The feedforward neural LM keeps track of the past N words in a window. These N words are each represented by a one-hot vector.
One-Hot Vector
“A one-hot vector is a vector [or array] that has one element equal to 1 — in the dimension corresponding to that word’s index in the vocabulary — while all the other elements are set to zero” [1]. The below shows how the one-hot vector has a “1” marked at index 5, and the index 5 maps to a specific word in the vocabulary; all of the other indices are marked as “0.”
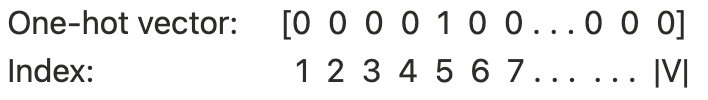
One-hot vector is basically an index turned into a vector so matrix multiplication can “look up” the embedding. The index of the vocabulary maps to a specific word, and the dimension value of 1 tells us which index (aka word) is lighting up or being represented. Each one-hot vector is multiplied by the embedding matrix E, which has a size of d x |V|, where |V| is the length of the vocabulary and there are d dimensions. Each of the embedding vectors are concatenated to create the embedding layer. Afterward, there is an output layer and then a softmax layer that creates the probability distribution.

The image above is credited to Speech and Language Processing by Jurafsky.
Embedding
“The input is a one-hot vector for each word which serves as an input index into an embedding matrix E. The embedding matrix E has a column (embedding vector) for each word in the vocabulary. Let’s say there’s a word with a 1-hot vector and it has an index number of 35 (which is the location in the vocabulary), we use this index to find its embedding vector in an embedding matrix. The embedding matrix may contain Word2Vec embeddings or the embedding may have random vectors which is how it was trained. This initial vector for each word in E is the initial embedding for the word that we have. When treated as a weight matrix (that can be updated), E contains the fine tuned word embeddings at the end of the training phase” [2].
Note: Read about Word2Vec here: https://www.linkedin.com/pulse/word-embeddings-sonal-prasad-7peec/?trackingId=OBoLGsSbQVmio38wqhvyXA%3D%3D

The image above is credited to Speech and Language Processing by Jurafsky.
Algorithm Example
Let’s say we have 3 previous words (shown in the diagram above), for which we create a total of 3 one-hot vectors. To create a one-hot vector, we first look up the index of the word from the vocabulary and mark the element at the index in the vector with “1” and the rest with “0.” We multiply the one-hot vector for “for” (index 35) with the embedding matrix E. Here is an example of the algorithm:
- The embedding layer for one word is: E*x_i = e_i E is the embedding matrix, x_i is the one-hot vector for one word, and e_i is the embedding layer for one word. We concatenate all of the N previous words’ one-hot vectors multiplied by E to get the embedding layer ‘e.’
- We pass the following through an activation function (such as ReLU): e is multiplied by W and then added with b. The final result is ‘h,’ or hidden layer.
- We multiply ‘h’ by ‘U.’
- With softmax, we get the probability distribution.

The semicolons refer to concatenation. The image above is credited to Speech and Language Processing by Jurafsky.
Training A Neural LM
When training a neural LM, we have the ability to adjust parameters E, W, U, and b. Training helps adjust W and U. We perform gradient descent, and use backpropagation. We train the parameters to minimize loss. “As we’re predicting upcoming words, we’re learning the embeddings E for each word that best predict upcoming words” [1]. Training results in 1) having a language model, and 2) a new set of embeddings E that can be used elsewhere. Alternatively, neural language models can use pre-trained embeddings.
Bibliography
[1] Speech and Language Processing by Jurafsky
[2] Jetcheva, San Jose State University Natural Language Processing Course, Module 9 slides
메타데이터
- post_id
- fdba55c1c3e3
- slug
- language-modeling-with-neural-networks-fdba55c1c3e3
- url
- https://medium.com/@sonalprasad.sp/language-modeling-with-neural-networks-fdba55c1c3e3
- canonical_url
- https://medium.com/@sonalprasad.sp/language-modeling-with-neural-networks-fdba55c1c3e3
- author_url
- https://medium.com/@sonalprasad.sp
- status
- ok
- fetched_at
- 2026-07-13 06:23:13