How to Convert PDFs to Grayscale Using Python
When automating document workflows, converting color PDFs to grayscale is a frequent requirement. Whether you aim to reduce printing costs…
How to Convert PDFs to Grayscale Using Python
When automating document workflows, converting color PDFs to grayscale is a frequent requirement. Whether you aim to reduce printing costs, compress file sizes, standardize archives, or remove visual distractions, grayscale conversion is an essential skill for Python developers.
This guide provides a step-by-step approach to convert PDF to grayscale in Python using the free Spire.PDF library—without losing vector quality or relying on external software like Adobe Acrobat.
1. Why Convert PDFs to Grayscale?
Typical use cases include:
- Cost-Effective Printing: Grayscale output significantly lowers color printing expenses while maintaining clear text and graphic readability.
- Standardized Archiving: Many archival systems mandate a uniform grayscale format for long-term storage and retrieval.
- File Size Reduction: Removing color channel data often leads to a noticeable decrease in file size, especially for image-heavy PDFs.
- Preprocessing for OCR & Analysis: Grayscaling is a critical preliminary step in OCR pipelines and AI-based document analysis to reduce noise.
2. Choosing the Right Approach
In the Python ecosystem, you have several ways to grayscale a PDF:
- Render and recompose — Render each page as a bitmap, convert it to grayscale, then reassemble a new PDF. This is flexible but loses vector information and may inflate file sizes.
- Call external tools — Use
subprocessto invoke command‑line utilities like Ghostscript. This is mature and robust, but it introduces external dependencies and complicates deployment. - Native PDF libraries — Modify the color space directly at the document level, preserving all vector data. This yields high-quality and compact output, but the library options are more limited.
✅ This article follows the third path, using the Free Spire.PDF for Python library. It provides a dedicated grayscale conversion API that retains vector structure and requires neither Adobe Acrobat nor any other external components.
3. Setting Up Your Environment
Install the Dependency
Install the free edition via pip:
pip install spire.pdf.freeVersion Note
The free version processes up to 10 pages per document — plenty for personal learning, small scripts, and typical office tasks.
After installation, import the necessary modules:
from spire.pdf.common import *
from spire.pdf import *
4. How to Convert a Single PDF to Grayscale in Python
The central class is PdfGrayConverter. It handles everything in a single call.
from spire.pdf.common import *
from spire.pdf import *

def pdf_to_grayscale(input_path: str, output_path: str) -> None:
    """Convert a color PDF to grayscale."""
    converter = PdfGrayConverter(input_path)
    converter.ToGrayPdf(output_path)
if __name__ == "__main__":
    pdf_to_grayscale("sample.pdf", "grayscale.pdf")
    print("Conversion completed")
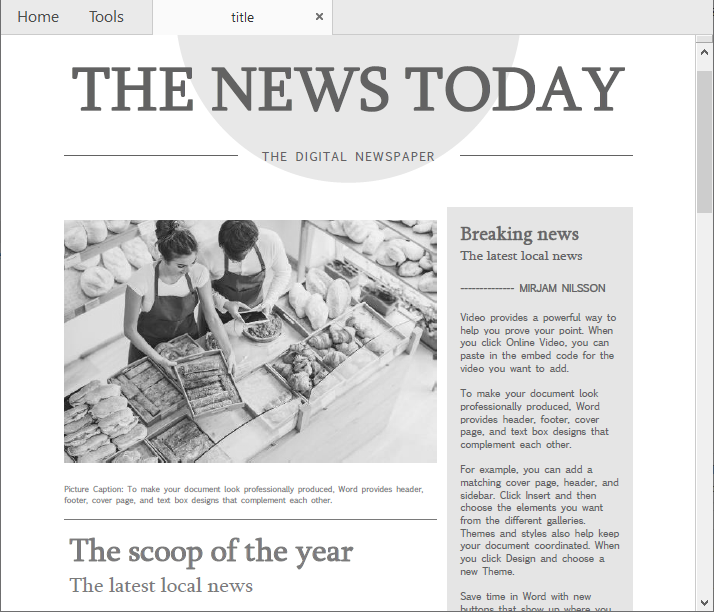
The grayscale PDF:
How the Code Works
- The
PdfGrayConverterloads your source document instantly. - The
ToGrayPdf()method handles all heavy lifting: parsing text, vector graphics, and images; converting RGB/CMYK to grayscale; and preserving original layouts.
💡 A key point: the method creates a brand‑new PDF and leaves the original untouched, following the immutable‑operation best practice.
5. Batch Converting Multiple PDFs to Grayscale with Python
Often you need to process many files at once. Here’s a ready‑to‑use batch script:
import os
from spire.pdf.common import *
from spire.pdf import *

def batch_convert_to_grayscale(input_dir: str, output_dir: str) -> None:
    """Convert all PDFs in a directory to grayscale."""
    os.makedirs(output_dir, exist_ok=True)

    for filename in os.listdir(input_dir):
        if not filename.lower().endswith(".pdf"):
            continue
        input_path = os.path.join(input_dir, filename)
        output_path = os.path.join(output_dir, f"gray_{filename}")

        try:
            converter = PdfGrayConverter(input_path)
            converter.ToGrayPdf(output_path)
            print(f"[OK] {filename}")
        except Exception as e:
            print(f"[FAIL] {filename}: {str(e)}")
if __name__ == "__main__":
    batch_convert_to_grayscale("./input_pdfs", "./output_pdfs")
🛡️ In production, add proper logging and error handling so that a single failure doesn’t halt the entire batch.
6. Wrap‑Up
Converting a PDF to grayscale may seem simple, but choosing the right implementation matters. With a dedicated PDF library that performs native color‑space conversion, you can achieve high‑quality results with minimal code.
The PdfGrayConverter approach described here is:
- Lightweight — minimal boilerplate
- Easy to integrate — no external dependencies
- Reliable — preserves vector quality
It’s ideal for embedding in document pipelines, automated archiving systems, or batch scripts. Feel free to extend it with additional features like compression, watermarking, or format conversion to suit your specific business needs. ✨
메타데이터
- post_id
- 07c55d8cbde7
- slug
- how-to-convert-pdfs-to-grayscale-using-python-07c55d8cbde7
- url
- https://medium.com/@andrewwil/how-to-convert-pdfs-to-grayscale-using-python-07c55d8cbde7
- canonical_url
- https://medium.com/@andrewwil/how-to-convert-pdfs-to-grayscale-using-python-07c55d8cbde7
- author_url
- https://medium.com/@andrewwil
- status
- ok
- fetched_at
- 2026-08-18 06:22:17