Memory-Efficient Top-K for ONNX with In-Place Heap Processing
Author: Asmaa Samir
Memory-Efficient Top-K for ONNX with In-Place Heap Processing
Author: Asmaa Samir
Senior Embedded Software / DSP Team
Date: January 2026
1. Abstract
The Top-K operation is a cornerstone of modern machine learning. The Top-K algorithm finds the K largest (or smallest) elements along a specified axis of a tensor, yet its standard implementation often introduces significant memory overhead through full sorting (O(N log N)) or the use of auxiliary buffers for heap management. This paper introduces a memory-efficient custom TopK kernel designed for the ONNX runtime (Open Neural Network Exchange runtime, It is an open-source format designed to represent machine learning models) that addresses these constraints. Our approach performs the operation in-place within the output tensor, eliminating the need for additional memory allocations. By utilizing a binary heap-based selection process, we achieve a time complexity of O(N log K) while maintaining a minimal memory footprint. This optimization is particularly critical for edge devices and memory-constrained embedded environments where resource efficiency directly impacts system performance and reliability.
2. Introduction
In the context of Deep Learning and Neural Network inference, the TopK operator identifies the K largest (or smallest) elements along a specific axis of a tensor. This is essential for tasks such as:
- Recommendation Systems: Selecting top-rated items.
- Search Engines: Ranking result relevance.
- Feature Selection: Identifying the most significant weights or activations in a model.
The Open Neural Network Exchange (ONNX) defines specific parameters for Top-K, including the input tensor, the value of K, the target axis, and attributes like largest (to toggle between max/min values) and sorted.
3. The Memory Challenge
Standard implementations of Top-K generally follow one of three preliminary paths before reaching highly optimized in-place solutions:
- Naïve Sort: Sorting the entire input array (N elements) and selecting the top K items (= 5 in ex). While simple to implement, this is computationally expensive (O(N log N)) and typically requires O(N) memory to hold the sorted copy if the input must remain immutable.
Input array
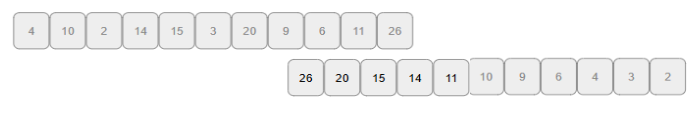
Sorted array (k = 5)
2. Advanced Naïve: Instead of sorting the whole array, this approach maintains a sorted list of K elements. For every new element in the input, the list is re-sorted or elements are shifted. While this reduces space complexity to O(K), the time complexity grows to O(N . K), making it inefficient for larger values of K.
Input array:

Output array:
3. Auxiliary Buffer Heap: This method employs a binary heap to maintain the top K elements with a time complexity of O(N log K). However, standard versions typically allocate an auxiliary memory buffer (a priority queue) of size K to manage the heap logic. While more efficient than sorting, this transient allocation increases the memory “high-water mark” during execution.

The “Binary heap” is “the most common method to implement” a priority queue for this type of problem. For embedded systems and Digital Signal Processors (DSPs), these approaches present significant bottlenecks. Even the memory used by an auxiliary buffer can lead to fragmentation or out-of-memory (OOM) errors in complex inference graphs with tight resource constraints.
4. Proposed Methodology: In-Place Heap Processing
Our implementation optimizes the Top-K kernel by leveraging a Binary Heap structure managed directly within the memory already allocated for the output tensor.
4.1 Binary Heap Logic
A Binary Heap is a complete binary tree where:
- Min-Heap: The root is the minimum element (used for finding the K largest values).
- Max-Heap: The root is the maximum element (used for finding the K smallest values).
We represent the heap using an array-based structure where for an element at index i:
- Parent: (i — 1) / 2
- Left Child: 2i + 1
- Right Child: 2i + 2
4.2 Algorithm Execution Flow
- Initialization: The output buffer — pre-allocated for both values and their corresponding indices — is initialized with the first K elements from the input tensor to form the initial heap structure.

2. Heapification: We perform an initial MinHeapify (if searching for largest values) to organize these K elements into a valid heap.
3. Streaming Comparison: For the remaining N-K elements in the input tensor:
- Compare the current element with the root of the heap.
- If the new element is “better” (e.g., larger than the min-root), replace the root with the new element.
- Re-run the Heapify logic to restore the heap property.


4. Finalization: Once the input is exhausted, the output buffer contains the Top K elements. If the ONNX sorted attribute is True, a final O(K log K) sort is performed on the results.
4.3 Code Implementation (Simplified)
If searching for largest values, restores the Min-Heap property by rearranging elements. It identifies the smallest value among a node and its children, performing an in-place swap of value and index if the parent is larger than a child. This keeps the smallest element at the root for O(1) access during streaming comparison.
template<typename T>
void MinHeapify(T* values, int* indices, int i, int heap_size) {
    int smallest = i;
    int left = 2 * i + 1;
    int right = 2 * i + 2;

    // Compare values at current index with children
    if (left < heap_size && values[left] < values[smallest])
        smallest = left;

    if (right < heap_size && values[right] < values[smallest])
        smallest = right;

    // If the smallest element is not the current root, swap and recurse
    if (smallest != i) {
        // Swap scalar values
        T tempVal = values[i];
        values[i] = values[smallest];
        values[smallest] = tempVal;

        // Swap corresponding indices
        int tempIdx = indices[i];
        indices[i] = indices[smallest];
        indices[smallest] = tempIdx;

        MinHeapify(values, indices, smallest, heap_size);
    }
}
5. Performance and Complexity Analysis
Our approach significantly reduces both temporal and spatial overhead compared to traditional methods.

By eliminating the need for an auxiliary buffer, the implementation achieves a zero-overhead space complexity relative to the required output memory. This represents a significant advancement for high-performance computing on hardware with strict memory limits.
6. Verification and Testing
To ensure full compliance with the ONNX specification, the kernel was verified against the ONNX reference model using various tensor shapes and attributes:
- Test Environment: Standard ONNX test cases for BHWGC (Batch, Height, Width, Group, Channel) shapes.
- Key Scenarios:
- largest = True/False
- sorted = True/False
- Varying K values (Small K vs K N).
Note on Sorting: Per ONNX specifications, if sorted = False, the order of the output elements is undefined. In these cases, our heap-based approach provides the correct values in a shorter time by skipping the final sort.
7. Conclusion
The In-Place Heap Processing technique for the Top-K operator offers a robust and highly efficient solution for modern machine learning inference. By merging the algorithmic advantages of binary heaps with a strategic in-place memory management approach, we have developed a kernel that excels in resource-constrained DSP and edge environments. This approach not only ensures ONNX compliance but also sets a benchmark for developing low-overhead, high-performance operators in embedded systems. This implementation ensures that even on the most constrained hardware, Top-K operations remain fast, reliable, and compliant with global standards.
메타데이터
- post_id
- 33de1a6c914e
- slug
- memory-efficient-top-k-for-onnx-with-in-place-heap-processing-33de1a6c914e
- url
- https://medium.com/si-vision-tech-blog/memory-efficient-top-k-for-onnx-with-in-place-heap-processing-33de1a6c914e
- canonical_url
- https://medium.com/si-vision-tech-blog/memory-efficient-top-k-for-onnx-with-in-place-heap-processing-33de1a6c914e
- author_url
- https://medium.com/@asmaa.samir
- status
- ok
- fetched_at
- 2026-06-14 11:28:49