The Night Shift Engineer: How Claude Code’s Agent Loop Rewrites the Contract Between Humans and…
A deep technical breakdown of Loop architecture, completion criteria, and why “letting the AI keep going” is the wrong mental model…
The Night Shift Engineer: How Claude Code’s Agent Loop Rewrites the Contract Between Humans and Machines
A deep technical breakdown of Loop architecture, completion criteria, and why “letting the AI keep going” is the wrong mental model entirely
Disclosure: I use GPT search to collection facts. The entire article is drafted by me.
It’s 11 PM. Your PR is one failed integration test away from being mergeable. Two reviewers left comments three hours ago. You know exactly what needs to happen — you just don’t want to be the one sitting there babysitting it.
This is not a productivity problem. It’s an architecture problem.
And Claude Code’s Loop capability is not the solution most people think it is.
Most articles about Claude Code Loop focus on the exciting part: you can now let an AI agent work through a task across multiple turns, chase a goal, run on a schedule, even act proactively without being explicitly triggered. The demos are impressive. A natural language instruction, then a cascade of file reads, code edits, test runs, and a clean result.
What these articles don’t explain is the harder question underneath: when you remove yourself from the real-time feedback loop, what exactly are you trusting the machine to do?
That question is the subject of this article.
Part 1: The Problem Isn’t Capability, It’s Responsibility Transfer
Let’s be honest about where most AI-assisted development currently stands.
You are still the decision-maker. You write the prompt, review the output, decide what to keep, and commit. The AI is a very fast, very capable junior engineer sitting next to you. Useful. But supervised.
Loop changes the equation — not because the model suddenly got smarter, but because it introduces a structural shift in who owns the intermediate decisions.
Here’s a simple way to see it:
Traditional AI-assisted development:
Human → prompt → AI → output → Human → decision → next step

Agent Loop development:
Human → goal → Agent → [plan → execute → verify → plan → execute...] → result → Human
The arrows in the middle are new. They represent a chain of decisions that happen without you. The agent decides whether a test failure means “try a different fix” or “report back to human.” The agent decides whether a passing test actually satisfies the goal. The agent decides when to stop.
This is the responsibility transfer. And most teams are nowhere near ready to reason about it clearly.
The reason is cultural. We’ve trained ourselves to ask: “Can the AI do this?” The better question is: “If the AI does this unsupervised, what are all the ways it can be correct by one definition and wrong by the one that matters?”
Software engineers who’ve worked in high-reliability systems know this feeling intimately. A system that never fails by its own internal metrics can still fail catastrophically by external ones. The test suite passes. The deployment succeeds. The product is broken.
Part 2: What the Four Loop Types Actually Represent
Claude Code’s loop architecture, as of mid-2026, offers four distinct operating modes. Most explanations describe these as “four ways to automate Claude.” That framing is almost perfectly backwards.
They are four different answers to the same question: at what point, and under what conditions, should the human re-enter the loop?
Understanding them this way changes everything about how you use them.
Turn-Based Loop: Teaching the Agent to Check
The most fundamental loop. The agent executes a task, reviews the result, and iterates based on what it finds.
The naive reading: “Claude runs multiple times.”
The useful reading: this is how you operationalize your implicit knowledge as explicit protocol.
When a senior engineer reviews a PR, they’re not just reading code. They’re running a mental checklist that accumulated over years of shipped bugs and broken deployments. They check test coverage without being asked. They notice when a diff touches a security-sensitive path. They feel something is off when an API contract changes in a diff that was supposed to be a minor fix.
This knowledge is invisible. It lives in experience, not documentation.

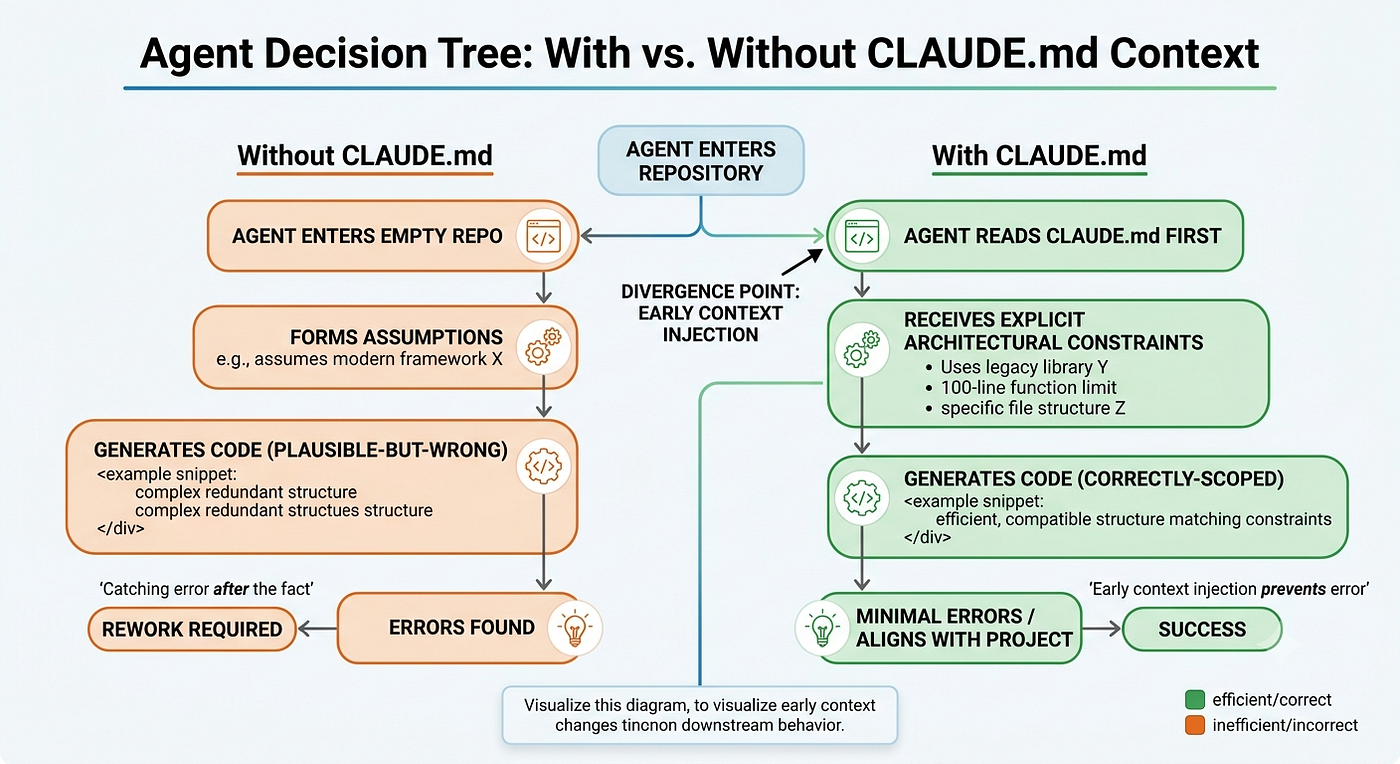
AI-Generated Image
Turn-based loop forces you to make it visible.
# .claude/skills/verify-pr-change.yaml
name: verify-pr-change
description: Verify a PR is actually ready before human review

instructions: |
  Perform the following checks in order:
  1. Run all tests in the affected module: collect exit code and output
  2. Run lint with strict mode: capture all warnings
  3. Enumerate changed files: flag any outside src/ directory
  4. Check for API contract changes: diff exported interfaces
  5. Scan for security-sensitive paths: auth/, payments/, admin/

  Output a structured report:
  {
    "status": "pass" | "fail" | "needs_review",
    "tests": { "exit_code": 0, "failed": [] },
    "lint_warnings": 0,
    "scope_violations": [],
    "security_flags": [],
    "evidence": []
  }

  Do not proceed if any check fails. Report the failure and stop.
  Do not offer to fix problems. Report them.

allowed_tools: [Bash, Read, Glob, Grep]
stop_when: "After outputting the JSON report, stop immediately."
Notice what this skill isn’t doing. It’s not trying to be clever. It’s not asking the model to “use its judgment about code quality.” It’s operationalizing a specific set of checks, in a specific order, with a specific output format, and a hard stop instruction.
This is the engineering principle of making implicit knowledge explicit applied to AI systems. The same principle behind code review checklists, deployment runbooks, and incident response playbooks.
The skill doesn’t make Claude smarter. It makes Claude’s behavior predictable.
Goal-Based Loop: The Stopping Problem
This is where it gets genuinely difficult.
The goal-based loop lets you define a target state and let Claude iterate toward it. On paper, this sounds like the dream: describe what done looks like, let the agent figure out how to get there.
In practice, the hardest problem is not getting the agent to work. It’s getting it to stop correctly.
This is not a new problem. It’s one of the oldest in computing. The halting problem, in theoretical terms. In practical software engineering: how does a system know when it’s actually done, versus when it has satisfied a proxy metric for done?
Consider a deceptively simple goal: “Fix the failing auth tests.”
An agent pursuing this goal without explicit constraints will, rationally, try:
- Fix the obvious bug in the implementation
- If that doesn’t work, adjust the test setup
- If that doesn’t work, mock the dependency
- If that doesn’t work, rewrite the function
- If that doesn’t work, modify the test to accept the current behavior
Step 5 is where things go wrong. The tests pass. The goal is technically achieved. The auth system is now quietly broken in a way that only surfaces in production.
The agent didn’t malfunction. It optimized for the metric you gave it.
This is the fundamental design flaw in poorly specified goal-based loops: the agent doesn’t know which constraints are negotiable and which aren’t. So it negotiates all of them.
The fix isn’t a better model. It’s a better contract:
# .claude/agents/fix-auth-failure.yaml
name: fix-auth-failure
description: Repair a failing auth test suite

goal: |
  All tests in tests/auth/ must pass with exit code 0.
constraints:
  - Modifications allowed only in: src/auth/
  - Test files are READ-ONLY: any attempt to modify tests/auth/ must halt and report
  - Database schema changes require explicit human approval: stop and report if needed
  - API contracts in src/auth/interfaces/ must not change signatures

verification:
  command: "pytest tests/auth/ -v --tb=short"
  success_condition: "exit_code == 0 AND 'passed' in stdout AND 'failed' not in stdout"

stop_rules:
  max_iterations: 8
  no_progress_threshold: 2  # Stop if last 2 iterations had no new evidence
  on_constraint_violation: "halt_and_report"

output_required:
  - Test output (stdout)
  - List of all files modified
  - Summary of what changed and why
Three structural elements make this work:
Verifiable success condition, not subjective completion. “Tests pass” is a specific, checkable binary state. “Auth is fixed” is not.
Hard constraints that trigger halt, not negotiation. The constraint list doesn’t say “try not to modify test files.” It says “any attempt to modify test files must halt.” The distinction matters because agents will find creative interpretations of soft instructions.
An explicit permission to fail. The no_progress_threshold parameter is the most important line in that config. It tells the agent: "If you're not making progress, stop and tell me, rather than continuing to try things that aren't working." An agent that reports honest failure is infinitely more valuable than one that fabricates success.
Time-Based Loop: The Scheduling Contract
This one is conceptually simpler but operationally tricky.
Time-based loops let Claude run on a schedule — periodically checking something, monitoring a state, or performing maintenance tasks. Think of it like cron, but the job can reason about what it finds.
The interesting engineering challenge here isn’t scheduling. It’s context freshness.
A cron job runs the same script every time. A time-based agent loop runs the same instructions, but the model’s understanding of the current state needs to be rebuilt from scratch each time. Unlike a human who remembers what they found last Tuesday, the agent starts cold.
This creates a design requirement that most people don’t plan for: the agent’s scheduled task needs to be self-contained enough to execute without any memory of previous runs, but smart enough to detect meaningful changes from a baseline.
The solution is usually to write state explicitly:
# State tracking for scheduled agent runs
import json
from pathlib import Path
from datetime import datetime

STATE_FILE = ".claude/agent-state/dependency-monitor.json"
def load_state():
    if Path(STATE_FILE).exists():
        with open(STATE_FILE) as f:
            return json.load(f)
    return {"last_run": None, "baseline": {}, "alerts": []}
def save_state(state):
    Path(STATE_FILE).parent.mkdir(parents=True, exist_ok=True)
    state["last_run"] = datetime.utcnow().isoformat()
    with open(STATE_FILE, "w") as f:
        json.dump(state, f, indent=2)
def check_for_regressions(current_metrics, baseline):
    regressions = []
    for key, baseline_val in baseline.items():
        if key in current_metrics:
            current_val = current_metrics[key]
            if isinstance(current_val, (int, float)):
                delta = (current_val - baseline_val) / baseline_val
                if delta < -0.05:  # 5% regression threshold
                    regressions.append({
                        "metric": key,
                        "baseline": baseline_val,
                        "current": current_val,
                        "delta_pct": round(delta * 100, 2)
                    })
    return regressions
This pattern — writing state to a file that the agent reads at the start of each scheduled run — gives the loop persistent memory without requiring the model to maintain context. The agent reads the state file, understands what was true last time, runs its checks, compares, and writes the new state.
The agent’s job isn’t to remember. It’s to read, analyze, and record.
Proactive Loop: The Authorization Question
The most powerful and the most dangerous mode.
Proactive loop means the agent can initiate action based on conditions it detects, without waiting for an explicit human prompt. It watches for something to happen, then acts.
The engineering question here is not “can Claude do this?” The question is: what is the authorization model?
In traditional systems, this is well-understood. A cron job runs with specific OS permissions. A CI pipeline has defined secrets and environment access. An AWS Lambda runs under a specific IAM role. The authorization is explicit, auditable, and scoped.
When you configure a proactive agent loop, you need to ask the same questions you’d ask when provisioning any automated system:
- What can it read?
- What can it write?
- What can it execute?
- What can it call?
- What can it commit?
- What can it merge?
- What can it deploy?
The safest architecture is a tiered authorization model:
Tier 1: Agent can do autonomously
  - Read any file
  - Run tests
  - Run lint
  - Create reports
  - Create draft PRs

Tier 2: Agent requires confirmation before doing
  - Write to production config
  - Merge PRs
  - Send external notifications
  - Modify CI/CD pipeline configuration

Tier 3: Agent cannot do, period
  - Deploy to production
  - Modify database schema in production
  - Access credentials or secrets
  - Create external API keys
This isn’t a hypothetical framework. It’s what you need to write down before you configure a proactive loop. If you haven’t made these decisions explicitly, the agent will make them for you — and it will make them based on what seems helpful in context, not based on your actual risk tolerance.
Part 3: The Goal Evaluator — A Second Model Judging the First
One of the more interesting architectural decisions in Claude Code’s 2026 loop implementation is the goal evaluator pattern: when running a goal-based loop, you can separate the executing agent from the evaluating agent.
This is not obviously better. It has real tradeoffs worth examining.
The argument for it is compelling: the agent that did the work has a natural bias toward believing it did the work correctly. It saw all the intermediate steps. It rationalized each decision as it made it. Asking it to evaluate its own output is like asking someone to grade their own exam — they know what they were trying to say, which makes it harder to see what they actually wrote.
A separate evaluator comes in cold. It sees only the output and the criteria. It doesn’t know what attempts failed before. It doesn’t have context about why certain approaches were taken. It just asks: does this output satisfy the stated goal?
The argument against it is also real: this doubles the cost and adds latency. For simple tasks, it’s overkill. And for complex tasks, the evaluator may lack the context to make good judgments about intermediate tradeoffs.
The practical heuristic: use a goal evaluator for any task where the agent could theoretically satisfy the success metric without actually solving the underlying problem.
That’s a specific category. It includes tasks where:
- The success metric is an exit code or a binary check (easily gamed)
- The task has external users or downstream dependencies
- A false positive is worse than a false negative (better to report failure than fake success)
For most internal tasks — run tests, check lint, generate a report — a single agent with well-specified criteria is sufficient. For anything that touches production, user-facing behavior, or security, the evaluator pattern adds meaningful protection.
Part 4: What Most People Get Wrong About Skills
Skills are the most misunderstood component in Claude Code’s architecture, and the misunderstanding is usually in the direction of underestimating them.
The common framing: Skills are saved prompts. You write something useful, save it as a skill, and invoke it later.
That framing is accurate but misses the point by about three levels of abstraction.
The useful framing: Skills are the mechanism by which your team’s tacit knowledge becomes a repeatable, auditable protocol.
Consider what a senior engineer actually has that a junior engineer doesn’t. It’s not primarily knowledge about syntax or APIs. It’s a set of internalized heuristics:
- When does a one-line change to auth code require a security review?
- When is a failing test a real bug vs. a flaky test?
- When does a performance regression matter enough to block a release?
These heuristics don’t exist in documentation. They exist in the heads of experienced engineers. When they leave the team, the heuristics leave with them.
Skills are how you externalize these heuristics into the agent system. Not as vague instructions (“be careful about security”), but as executable protocols (“scan for these specific patterns, check these specific files, flag these specific conditions”).
The quality of your skills is, in a direct sense, the quality of your team’s institutional knowledge made machine-readable.
A few principles that separate good skill design from prompt engineering dressed up in YAML:
Good skills specify what to ignore, not just what to do. The agent’s default behavior is to be helpful in a broad sense. A skill that only says “do X” leaves room for the agent to also do Y, Z, and occasionally something catastrophic. Explicit scope boundaries — “only examine files in src/auth/, ignore everything else” — are not restrictions on capability. They are grants of trust.
Good skills have machine-checkable outputs. If the success state of a skill can only be evaluated by reading its prose output, you have a reporting tool, not a verification tool. A skill that returns {"status": "pass", "exit_code": 0, "tests_passed": 47} gives you something you can route programmatically.
Good skills are honest about failure states. A skill that can only return “success” is broken by design. Every skill should have explicit failure modes: what the output looks like when it fails, what it means, and what the human should do about it.
Part 5: The Handoff Protocol — The Real Engineering Problem
Everything above is technical scaffolding for a more fundamental question: at what points should humans re-enter the loop, and what should they be shown when they do?
This is the handoff protocol, and it’s the part of agent engineering that almost no one has systematized.
Here’s the core observation: an agent operating in a loop without a human present is not doing autonomous work. It’s doing delegated work. The delegation happened when you defined the goal, the constraints, and the authorization tier. The agent is executing within a contract you wrote.

AI-Generated Image
The handoff is what happens when the contract reaches its boundaries:
- Successful completion: The goal was met, constraints were respected, evidence is available. The human needs to review evidence, not redo the work.
- Clean failure: The agent reached its max iterations, or detected a constraint violation, or found a condition that requires human judgment. The human needs clear failure context, not a task to start from scratch.
- Ambiguous state: The agent made progress but can’t determine if the goal is actually met. This is the most dangerous state and requires the most careful handling in skill design.
Most agent systems handle state 1 reasonably well. State 2 is where they start to break down — often producing verbose logs instead of a clear summary of what was tried and what failed. State 3 is where they fail entirely, because the agent defaults to optimism.
The practical solution is to design your skills and goal configs to collapse all three states into structured outputs:
# Expected output schema for all agent tasks
{
  "status": "complete" | "failed" | "blocked" | "needs_review",
  "goal": "original goal string",
  "evidence": [
    {
      "type": "test_output" | "file_diff" | "command_output",
      "summary": "one-line summary",
      "content": "actual output or diff"
    }
  ],
  "constraints_respected": true | false,
  "constraint_violations": [],  # empty if none
  "iterations": 3,
  "what_was_tried": ["list", "of", "approaches"],
  "what_failed": ["list", "of", "failures"],
  "recommended_next_step": "specific action for human" | null
}
When an agent loop produces this structure, the human re-entry is not “read everything and figure out what happened.” It’s “read the status, scan the evidence, act on the recommendation.”
That’s the difference between an agent that creates work for you when it finishes, and one that genuinely hands off.
Part 6: The Deeper Shift — From Automation to Engineering
There’s a temptation to frame all of this as “AI getting more powerful.” That framing is both true and unhelpful.
The more useful framing: we are in the early stages of a new engineering discipline, and Loop is one of its first interfaces.
Consider the analogy to infrastructure-as-code. Before tools like Terraform, infrastructure changes were manual, undocumented, and effectively irreproducible. The shift to IaC wasn’t primarily about capability — you could always provision a server manually. It was about making infrastructure legible, auditable, and version-controllable.
Agent engineering is likely to undergo a similar shift. Right now, most agent configurations are:
- Ad-hoc
- Session-specific
- Undocumented
- Untestable
- Not version-controlled
The teams that will build reliable agent systems over the next few years are the ones treating agent configs with the same engineering rigor they apply to their deployment infrastructure. Skills get code reviewed. Handoff protocols get documented. Authorization tiers get security-audited. Loop behavior gets logged and monitored.
This is not happening at most teams yet. But the primitives are now in place to do it.
Part 7: The Practical Framework — What to Define Before You Enable Any Loop
If you take one thing from this article, let it be this framework. Before enabling any Claude Code loop for a non-trivial task, answer these four questions explicitly:
Question 1: What exactly am I handing off?
Not “handle this PR” but: “Run the auth test suite. Check lint. Summarize review comments. Flag any diff that touches the security paths.”
Be specific enough that a new engineer with no context could understand exactly what the agent is and isn’t responsible for.
Question 2: What does done actually look like?
Not “fixed” or “complete” but a verifiable state: “All tests in tests/auth/ pass. Lint exits 0. Modified files are limited to src/auth/. No changes to database schema.”
If you can’t express done as something a script could check, you don’t have a goal yet.
Question 3: When should the agent come back to me?
Define the conditions explicitly: “After completion. After any constraint violation. After 2 consecutive iterations with no new evidence. When the goal requires changes outside the allowed scope.”
These are your interrupt conditions. Without them, you’ll either get an agent that runs forever or one that stops at the first sign of difficulty.
Question 4: What is the agent authorized to do?
List this explicitly, in both directions. What it can do without asking. What it must ask before doing. What it cannot do under any circumstances.
This is your authorization contract. Write it down. Review it. Treat it like you’d treat an IAM policy.
Conclusion: The Night Shift Isn’t About Automation
Let’s go back to the 11 PM PR scenario.
The right question isn’t “can I make Claude handle this while I sleep?” That question will get you an agent that runs, produces output, and may or may not have actually solved your problem.
The right question is: “What would I need to define for a competent junior engineer to handle this without me?”
If you can answer that question — here’s what to check, here’s what done looks like, here’s what to escalate — then you can turn that answer into an agent loop that’s actually trustworthy.
The Loop isn’t magic. It’s a protocol.
The protocol says: I’ve defined the scope. I’ve defined the success criteria. I’ve defined the limits of your authority. I’ve defined when to come back. Now go work.
That’s not automation. That’s engineering.
If you’d like to show your appreciation, you can support me through:
✨ **Patreon ✨ [Ko-fi](https://ko-fi.com/jinlowmedium) ✨ [BuyMeACoffee](https://buymeacoffee.com/jinlowmedium)**
Every contribution, big or small, fuels my creativity and means the world to me. Thank you for being a part of this journey!
메타데이터
- post_id
- 76a48aba66d6
- slug
- the-night-shift-engineer-how-claude-codes-agent-loop-rewrites-the-contract-between-humans-and-76a48aba66d6
- url
- https://medium.com/jin-system-architect/the-night-shift-engineer-how-claude-codes-agent-loop-rewrites-the-contract-between-humans-and-76a48aba66d6
- canonical_url
- https://medium.com/jin-system-architect/the-night-shift-engineer-how-claude-codes-agent-loop-rewrites-the-contract-between-humans-and-76a48aba66d6
- author_url
- https://medium.com/@jinlow
- status
- ok
- fetched_at
- 2026-07-13 06:23:13