RAG vs Long Context: Is the Vector Database Dead?
LLMs are frozen in time — and solving the context problem is where AI architecture gets interesting. Two schools of thought have emerged…
RAG vs Long Context: Is the Vector Database Dead?
LLMs are frozen in time — and solving the context problem is where AI architecture gets interesting. Two schools of thought have emerged, and the answer might surprise you.

There is a fundamental truth about large language models that every AI engineer eventually confronts: they are frozen in time. An LLM knows everything about the world up until its training cutoff, and absolutely nothing about what happened five minutes ago. Nor does it know anything about your private data — your internal wikis, your proprietary codebase, your customer records.
If we want a model to reason over any of that, we have to solve what engineers call context injection: getting the right information into the model at the right time. Two very different philosophies have emerged for doing this, and the rise of million-token context windows has forced us to reconsider which one actually makes sense.
The Engineering Approach: RAG
Retrieval-Augmented Generation, or RAG, is what happens when engineers apply their favourite tool — the database — to the problem of LLM memory. The basic idea is elegant:
- Take your documents (PDFs, code files, wikis, entire books).
- Chunk them into smaller pieces using a chosen strategy.
- Pass those chunks through an embedding model to convert them into vectors.
- Store those vectors in a dedicated vector database.
- At query time, perform semantic search to retrieve the most relevant chunks and inject them into the model’s context window.

This works — and it scales. You can index terabytes of enterprise data and always present the model with a slimmed-down, targeted slice of information.
But it also hides a serious point of failure.
“The answer existed in the data. The LLM just never saw it — because retrieval failed silently.”
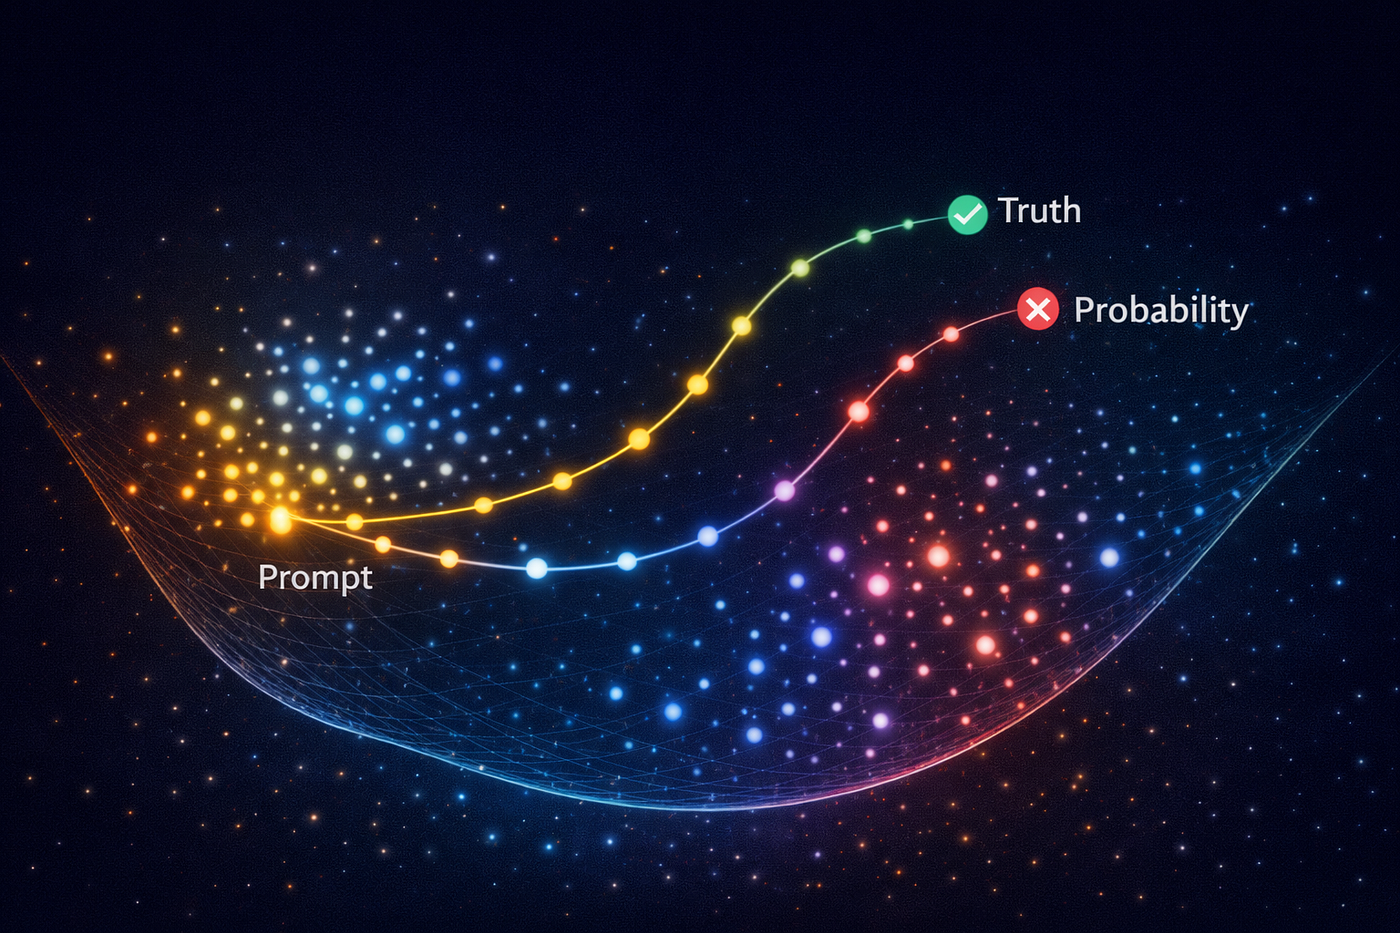
Semantic search is probabilistic. Vectors are mathematical approximations of meaning. And for all manner of reasons — domain-specific vocabulary, multi-hop questions, poorly chunked documents — retrieval can fail to surface the right information. Engineers have a name for this: silent failure. The model confidently answers based on whatever it did retrieve, without any indication that better evidence was left in the database.
A Concrete RAG Example
# Simple RAG pipeline (pseudocode)
def answer_with_rag(query, vector_db, llm):
  # Step 1: Embed the user's question
  query_vector = embed(query)

  # Step 2: Find the closest matching chunks
  chunks = vector_db.search(query_vector, top_k=5)

  # Step 3: Build context from retrieved chunks
  context = "\n".join([chunk.text for chunk in chunks])

  # Step 4: Send to LLM with retrieved context
  prompt = f""" Context: {context} Question: {query} Answer:"""

return llm.complete(prompt)
The infrastructure that surrounds this simple function is anything but simple. You need a chunking strategy (fixed-size? sliding window? recursive?), an embedding model, a vector store (Pinecone, Weaviate, Chroma), a reranker to sort results, and a sync process to keep vectors in step with source data as it changes. That is a lot of moving parts — and a lot of places for things to break.
The Brute-Force Approach: Long Context
Long context is the model-native solution. Skip the database. Skip the embedding model. Just take your documents and put them straight into the context window, then let the model’s attention mechanism do the heavy lifting.
For years, this was not a realistic option. Early LLMs had context windows of around 4K tokens — barely enough for a long email thread, let alone a corporate knowledge base. RAG was essentially mandatory.

With context windows this large, a reasonable question emerges: if we can simply paste all of our documentation into the model’s context window, do we really need the overhead of embedding models and vector stores at all?
Long Context in Practice
# Long context approach — much simpler stack
def answer_with_long_context(query, document_paths, llm):
    # Step 1: Load all relevant documents
    documents = [read_file(path) for path in document_paths]

    # Step 2: Put everything in context, ask the question
    full_context = "\n\n".join(documents)
    prompt = f""" Here are all relevant documents: {full_context} Question: {query} Answer:"""

return llm.complete(prompt)

# No embedding model. No vector store. No chunking strategy. # Just files → model
The architecture collapses dramatically. No embedding model, no vector database, no retrieval logic, no sync process. What some are calling the no-stack stack.
Three Arguments for Long Context
1. Collapsing the Infrastructure
A production RAG system is heavy. Between the chunking strategy, embedding model, vector database, reranker, and sync pipeline, you are maintaining five distinct subsystems — each with its own failure modes, scaling concerns, and operational costs. Long context eliminates all of them. For teams that want to move fast and keep the architecture legible, this simplification is genuinely meaningful.
2. Eliminating the Retrieval Lottery
RAG’s critical point of failure is the retrieval step itself. When the system fails to find the right chunk, the model never sees the answer — and crucially, it often doesn’t know that it missed anything. With long context, there is no retrieval step. The model gets to see everything, and its attention mechanism can find connections that probabilistic vector search would miss.
3. The Whole Book Problem

This is the scenario RAG architectures handle worst: questions whose answers are not in the data, but emerge from relationships between parts of the data. Global reasoning — spotting omissions, identifying contradictions, tracing threads across a long document — demands the whole book, not fragments of it.
Three Arguments for Keeping RAG
Despite all of the above, the vector database is not headed for a museum. Long context has real limitations that RAG was built to solve.
1. The Rereading Tax
Consider a 500-page technical manual — roughly 250,000 tokens. Every time a user asks a question, loading the entire manual into a long-context prompt means the model re-processes all 250,000 tokens from scratch. If you have 1,000 user queries per day, you are processing 250 million tokens daily from a single document.
RAG pays the processing cost once, at indexing time. Prompt caching partially offsets this for static documents, but for dynamic data that changes frequently, long context incurs the full cost on every request. At scale, this becomes expensive very quickly.
2. The Needle in the Haystack Problem
Research has consistently shown that model performance degrades as context windows grow. If a critical piece of information is buried in the middle of a 2,000-page document, the model’s attention mechanism can become diluted — it hallucinates details from the surrounding text rather than extracting the precise fact buried on page 847.
RAG’s forced relevance selection can actually improve reasoning quality. By retrieving only the top-five most relevant chunks, it removes the haystack and presents the model with just the needles — maximising signal and minimising noise.
3. The Infinite Dataset
A million tokens sounds enormous until you compare it to enterprise data lakes measured in terabytes or petabytes. No context window, however large, can hold an organisation’s entire knowledge base simultaneously. For any organisation with truly large-scale data, a retrieval layer is not optional — it is the only mechanism that makes the problem tractable at all.


Conclusion
The framing of RAG vs long context as a binary choice is a false dilemma. These are tools with different properties, suited to different shapes of problem. The real question is not which one you use — it is whether you understand clearly which problem you are actually solving.
If your data is bounded and your questions require global reasoning across documents, long context simplifies your stack and often improves your answers. If you are navigating an enterprise-scale knowledge base with millions of documents and thousands of daily queries, the vector database is not legacy infrastructure — it is the only viable foundation.

The frozen-in-time problem is real. How you thaw it out depends on the ice you’re working with.
메타데이터
- post_id
- 7a51612ecaba
- slug
- rag-vs-long-context-is-the-vector-database-dead-7a51612ecaba
- url
- https://ai.plainenglish.io/rag-vs-long-context-is-the-vector-database-dead-7a51612ecaba
- canonical_url
- https://ai.plainenglish.io/rag-vs-long-context-is-the-vector-database-dead-7a51612ecaba
- author_url
- https://medium.com/@naveenpandey2706
- status
- ok
- fetched_at
- 2026-06-09 15:37:30