Model Cascading: The Routing Layer Nobody Diagrams
Why the layer deciding which model answers your query rarely gets a name, a diagram, or a health metric
Model Cascading: The Routing Layer Nobody Diagrams
Why the layer deciding which model answers your query rarely gets a name, a diagram, or a health metric

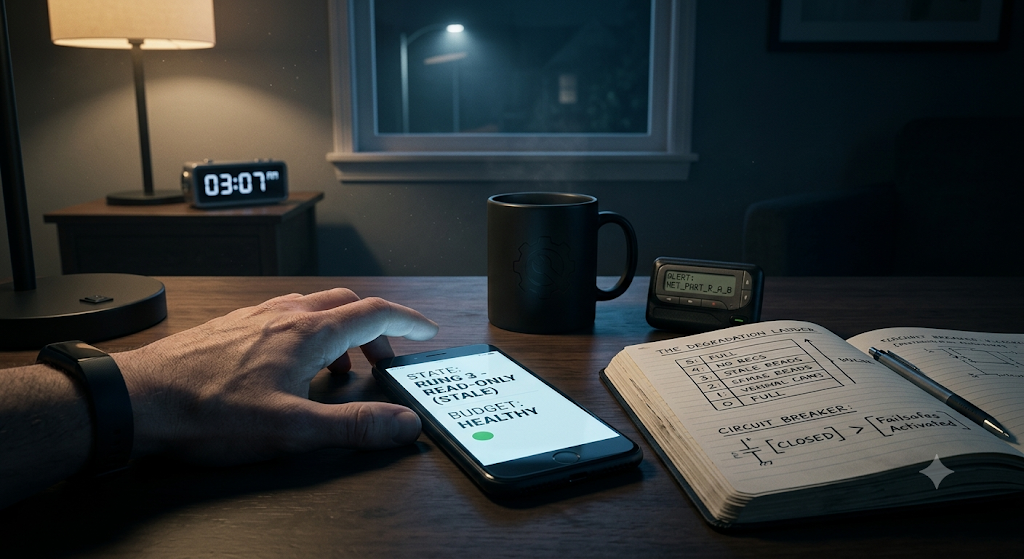
created by Gemini
Every AI engineering team has a diagram for their retrieval pipeline. Most have one for their agent orchestration. Almost none have a diagram for the piece of infrastructure that decides, on every single request, which model actually answers the question.
💥 Master Any Skills in 3 Months 📚 Up to 50% OFF Premium Courses ⏳ Limited-Time Offer *👉 **Enroll Now & Start Learning***
That piece is usually a handful of if-statements bolted onto a wrapper function, written in a hurry during a cost-cutting sprint, and never touched again except when someone notices the bill or the complaints. It rarely makes it into the architecture review. It rarely gets a name. And yet it is doing something more consequential than almost anything else in the stack: deciding, per request, how much intelligence the system is willing to pay for.
This piece is worth diagramming, because the decision it makes — cheap model or expensive model, one pass or two, accept or escalate — shapes your cost curve, your latency curve, and your quality curve simultaneously. Most teams tune one of those three and let the other two drift.
Cascading Is Not Routing, Even Though Everyone Uses the Words Interchangeably
Before going further, a distinction that gets flattened constantly in casual conversation but matters a lot in practice.
Routing places several models side by side and uses a classifier or heuristic to pick one, up front, based on the characteristics of the incoming query. One model, one shot. Fast, but the decision has to be right the first time, because there’s no fallback built into the mechanism itself.
Cascading runs models in sequence. A small, cheap model answers first. A judge — sometimes the model itself, sometimes a separate lightweight verifier — decides whether that answer is good enough to ship. If it isn’t, the query escalates to a larger, more expensive model. This can chain through several tiers before landing on a final answer.
The two get combined in production constantly (route to a starting tier, then cascade upward from there), but they fail differently, get monitored differently, and belong in different boxes on your architecture diagram. Treating them as one undifferentiated “smart routing” blob is exactly how teams end up unable to explain why costs crept up or quality dipped, because they never separated which mechanism was responsible for which decision.
Why This Layer Exists at All
The economic case is not subtle. A frontier model and a small open-weight model can differ in per-token cost by an order of magnitude or more, while overlapping heavily in the range of queries they can both answer correctly. Sending every request — “what’s the capital of France” included — to your most expensive model is not a quality decision, it’s a subsidy you’re paying for not having built a routing layer.
Cascading formalizes the alternative: try cheap first, escalate only when the cheap attempt shows signs of failing. The foundational framing of this came from academic work on cost-reducing LLM pipelines, which demonstrated that a cascade of models — small model first, escalation on low confidence — could approach the accuracy of always calling the most capable model, at a fraction of the cost. Follow-on research built on this by adding a self-verification step: the small model doesn’t just answer, it also assesses its own answer, and that self-assessment (not just raw output) becomes the signal for whether to escalate.
More recent industry-scale deployments back this up empirically. Cloud providers offering built-in “intelligent prompt routing” between models in the same family have reported meaningful cost reductions — on the order of 30% — simply by not sending easy queries to hard-model pricing.
What the Judge Actually Looks At
The hard part of cascading was never running two models. It’s deciding, cheaply, whether the first answer was good enough — without spending as much compute on the judgment as you saved by using the small model in the first place. A few signals show up repeatedly across implementations:
- Confidence from the model itself — self-reported certainty, or a secondary prompt asking the small model to critique its own output.
- Margin sampling — looking at how spread out the probability distribution is over the first token or two; a peaked distribution suggests confidence, a flat one suggests the model is guessing.
- Consistency checks — asking the small model the same question multiple times and checking whether the answers agree; disagreement is a proxy for difficulty.
- A separate, purpose-trained verifier — a lightweight classifier trained specifically to predict whether a given answer will hold up, decoupled from the model that produced it.
None of these are free. Every one of them adds latency or an extra call. This is the part that doesn’t make it into the pitch deck: a cascade with a badly tuned judge can end up slower and no cheaper than just calling the big model directly, because you paid for the small model’s attempt, paid for the verification step, and then escalated anyway.
A Shape Worth Drawing
request
   │
   ▼
┌─────────────┐     high confidence      ┌──────────────┐
│  Tier 1      │ ───────────────────────▶ │   return     │
│  small model │                          │   answer     │
└─────────────┘                          └──────────────┘
   │  low confidence
   ▼
┌─────────────┐     high confidence      ┌──────────────┐
│  Tier 2      │ ───────────────────────▶ │   return     │
│  mid model   │                          │   answer     │
└─────────────┘                          └──────────────┘
   │  low confidence
   ▼
┌─────────────┐
│  Tier 3      │ ─────────────────────────▶ return answer
│  frontier    │      (no further escalation)
└─────────────┘
Draw this, and a few uncomfortable questions surface immediately. What happens if Tier 3 is also unconfident — is there a human escalation path, or does the system just ship its worst guess with the same confidence as its best one? What’s logged at each tier, and can you reconstruct, after the fact, which tier actually produced a given answer a customer complained about? Is the judge itself versioned and evaluated, or is it the one component in this diagram nobody has ever back-tested?
Where Cascades Quietly Break
Classifier and judge drift. The judge — whether it’s a trained classifier or a prompted self-check — was tuned against a distribution of queries that existed at one point in time. Query patterns shift as products evolve and users change how they interact with the system. A judge that was well-calibrated at launch can become miscalibrated months later with no code change and no alert, because nothing about the system is technically “broken.” It’s just silently making worse escalation decisions.
Compounding failure under adversarial or unusual input. Recent research into cascade robustness has shown something worth taking seriously: because a cascade’s early stage acts as a gatekeeper for later stages, an input crafted to fool the confidence mechanism at Tier 1 can suppress escalation entirely — the system stays falsely confident in a bad answer and never gives the stronger model a chance to correct it. A single point of failure at the front of the pipeline can matter more than the strength of the model at the back of it.
Evaluation artifacts that flatter the cascade. Several routing benchmarks have been built specifically to compare cascading and routing strategies, and a recurring finding is that aggregate accuracy numbers can hide a lot. A cascade can look excellent on average while performing badly on an entire category of query that happens to be underrepresented in the benchmark — and that category can easily map onto a real, commercially important segment of your actual traffic.
Latency stacking. Every escalation tier is a sequential network call. A three-tier cascade that escalates 40% of the time isn’t paying the latency cost of your fastest model — it’s paying the latency cost of your fastest model plus a meaningful fraction of your slowest model’s latency, on top. Teams that only benchmark cost savings and skip the corresponding p95 latency chart are missing half the picture.
Cascading, Routing, and Ensembling, Side by Side

None of these is strictly better. They’re different trades, and most mature systems end up using more than one — static routing to pick a starting tier, cascading from there, with ensembling reserved for a narrow set of queries where being wrong is expensive enough to justify calling everything at once.
What Actually Belongs on the Architecture Diagram
If this layer is going to get the scrutiny it deserves, it needs to stop being an implementation detail inside a single function and start being a named component with its own health metrics: escalation rate over time, judge accuracy against spot-checked ground truth, latency contribution per tier, and cost per resolved query broken out by tier. Escalation rate in particular deserves the same alerting rigor as an error rate — a sudden jump means either the traffic mix changed or the judge broke, and right now, at most organizations, nobody would notice either one until finance or a customer did.
The routing layer isn’t glamorous. It doesn’t demo well. But it’s the component quietly deciding, thousands of times a day, how much your product is willing to spend on being right — and that’s not a detail worth leaving undiagrammed.
Thank you for being a part of the community
Before you go:
👉 Be sure to clap and follow the writer ️👏️️
👉 Follow us: **Linkedin| [Medium](https://medium.com/codetodeploy)**
👉 CodeToDeploy Tech Community is live on Discord — **Join now!**
Disclosure: This post includes affiliate and partnership links.
메타데이터
- post_id
- be866529afaf
- slug
- model-cascading-the-routing-layer-nobody-diagrams-be866529afaf
- url
- https://medium.com/codetodeploy/model-cascading-the-routing-layer-nobody-diagrams-be866529afaf
- canonical_url
- https://medium.com/codetodeploy/model-cascading-the-routing-layer-nobody-diagrams-be866529afaf
- author_url
- https://medium.com/@inprogrammer651
- status
- ok
- fetched_at
- 2026-07-23 04:11:16