GraphRAG: When RAG’s Blind Spot Costs You $85
Part 3 of the RAG Failures Series — how I mapped a 6-hop smartphone supply chain with Memgraph, the hidden connections that made my RAG…
GraphRAG: When RAG’s Blind Spot Costs You $85
Part 3 of the RAG Failures Series — how I mapped a 6-hop smartphone supply chain with Memgraph, the hidden connections that made my RAG system look blind, and a benchmark that shows exactly when GraphRAG stops being optional

GraphRAG Solution
“What happens to smartphone prices if China restricts Gallium exports?”
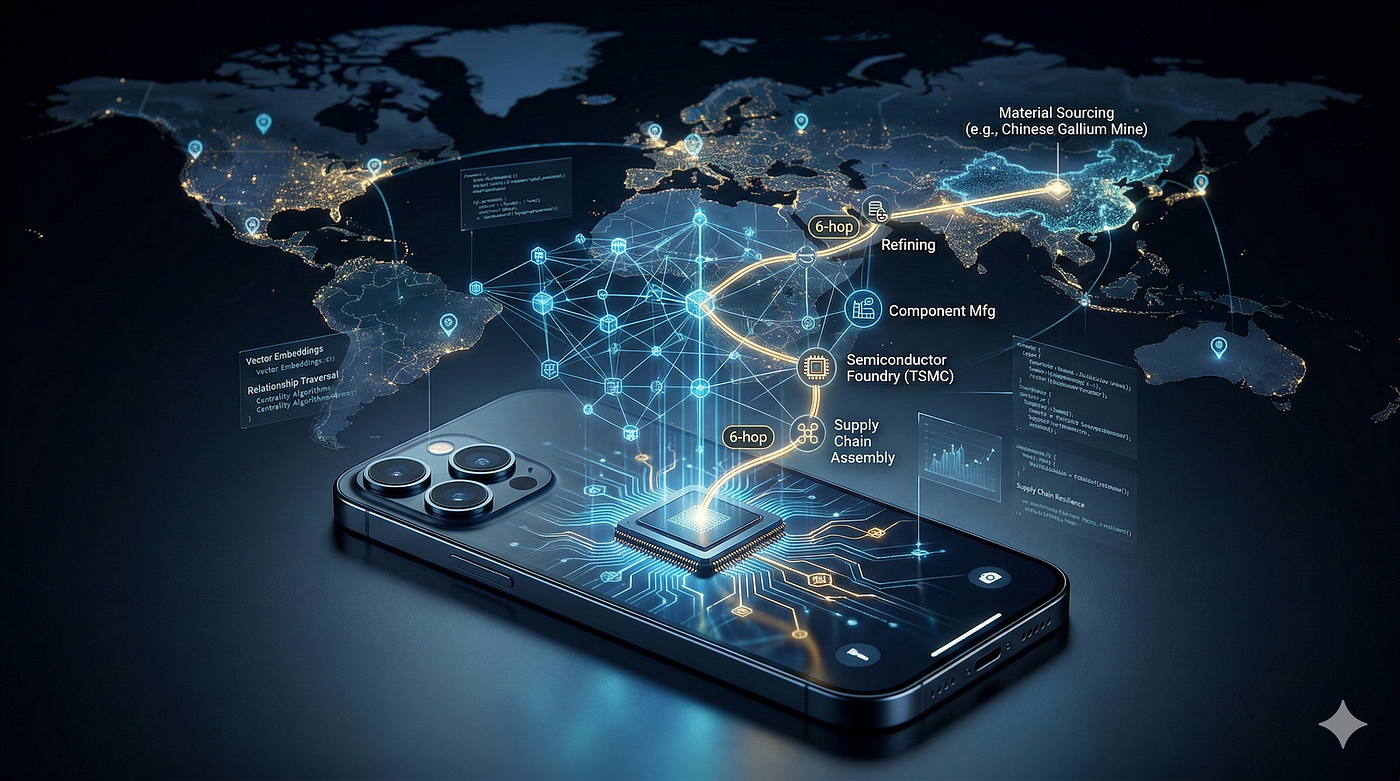
I asked this to two systems built on the same data. Standard RAG returned a paragraph about Gallium mining. GraphRAG traced a 4-hop path — Gallium → GaN chips → Qualcomm → iPhone 16 Pro — and returned $85 as the price impact. Same data. Same question. Completely different category of answer.
The Blind Spot of Standard RAG
Parts 1 and 2 of this series covered architectural failures, security gaps, and cost traps. One problem I left unresolved: multi-hop reasoning. RAG retrieves text chunks ranked by similarity. It has no concept of relationships between entities. When your question requires traversing connections — “trace the path,” “what breaks downstream,” “which node is the chokepoint” — text similarity cannot help. The answer lives in the topology of the data, not in any single document.

RAG vs GraphRAG: same question, two answers, benchmark across 5 query types
The gap is structural. On single-hop queries both systems score similarly. On 4-hop queries RAG scores 1.9/10. GraphRAG scores 8.7/10. That’s not a tuning problem.
Data Curation: The 80% Rule for Building Knowledge Graph
Most GraphRAG tutorials skip straight to the AI, but data curation is 80% of the work. To map a supply chain, you need diverse, structured, and unstructured data. Here is what powered this project:

The Golden Rule of Entity Extraction
Do not start with LLM-based extraction. LLMs hallucinate entities. For a reliable graph, use rule-based extraction first. It is deterministic and auditable. Match your text against known lists of companies, materials, and countries. Only use LLMs to enrich your data from unstructured sources after you have a clean baseline. One bad edge in a graph corrupts every query that traverses it.
extractor.py
KNOWN_COMPANIES = [
    "TSMC", "ASML", "Apple", "Samsung", "Qualcomm",
    "SK Hynix", "Foxconn", "Corning", "Murata", "ATL"
]

def extract_entities_rule_based(text: str) -> Dict:
    """Deterministic extraction - matches known entities only.
    Use this first. Always."""
    found_companies = [c for c in KNOWN_COMPANIES
                      if c.lower() in text.lower()]
    found_materials = [m for m in KNOWN_MATERIALS
                      if m.lower() in text.lower()]
    return {"companies": found_companies,
            "materials": found_materials}

def extract_entities_llm(text: str) -> Dict:
    """LLM extraction - used to ENRICH, not replace,
    rule-based results. Only for unstructured text."""
    pass
Why this order matters: a bad document in RAG gives one bad answer. A wrong relationship in GraphRAG gives wrong answers across every query that traverses that edge. Data quality is amplified in graphs. Rule-based first gives you a guaranteed clean baseline. LLM enriches it, but every LLM-extracted relationship gets validated against known entity lists before entering the graph.
The Architecture
The system I built, PhoneGraph, runs 100% locally using Memgraph (an in-memory graph DB), LangChain, Ollama (Llama 3), and a FastAPI/Streamlit frontend.
When a user asks a question, the pipeline executes three steps:
- NL to Cypher: The LLM generates a Cypher graph query using the graph schema as context.
- Graph Traversal: The query executes against Memgraph, returning connected nodes and relationships across multiple hops.
- Synthesis: The LLM synthesizes a human-readable answer from the structured graph results, complete with edge properties (like contract values or production percentages).

GraphRag Architecture
The Graph Schema

How the Two Pipelines Differ
The difference isn’t just performance. It’s a fundamentally different approach at every stage:
Standard RAG Pipeline: Raw Text → Chunk into fragments → Embed chunks (vector store) → Similarity search (top-K chunks) → LLM reads chunks → Answer
GraphRAG Pipeline: Raw Text + Structured Data → Extract entities and relationships → Build knowledge graph (nodes + typed edges) → LLM generates Cypher, traverses graph (N hops) → LLM reads graph results → Answer
The critical difference is steps 2–4. Standard RAG never sees the structure of the data. GraphRAG extracts that structure, preserves it as a graph, and traverses connected paths to construct the answer.
Wiring Relationships With Edge Properties
# Connecting materials to the countries they're sourced from
# Data: Gallium → China (80%), Japan (8%), South Korea (5%)
for country, percentage in mineral["extraction_countries"].items():
    query = """
    MATCH (m:Material {name: $mineral})
    MATCH (c:Country {name: $country})
    MERGE (m)-[r:EXTRACTED_IN]->(c)
    SET r.percentage = $pct
    """
The percentage property on the edge is what makes quantified answers possible. Without it, GraphRAG knows "Gallium comes from China." With it, GraphRAG knows "China produces 80% of global Gallium" — and can calculate price impact downstream. Always add properties to edges, not just nodes. It took me an embarrassing amount of time to learn this.
Unlocking Insights with Graph Algorithms
Running graph algorithms on connected data reveals patterns that text similarity simply cannot discover.

Graph Algorithms
The Query Pipeline

Three steps — question → Cypher → answer:
class PhoneGraphRAG:
    def query(self, question: str):
        result = self._chain.invoke({"query": question})
        return {
            "answer":  result["result"],
            "cypher":  result["intermediate_steps"][0].get("query"),
            "hops":    self._estimate_hops(cypher)
        }
LLMs generate invalid Cypher 15–30% of the time. Always include the full schema in your system prompt and build a hybrid fallback for when graph generation fails — vector similarity + 2-hop expansion. The system works even without Memgraph running.
The Shock Simulator — Real Events, Real Numbers
Three scenarios from real disruptions:

Shock Simulator: Gallium ban 2023 · Ukraine neon 2022 · Taiwan tariffs 2025 — with full cascade chains and dollar impacts
The Verdict: When to Use GraphRAG
GraphRAG is not universally “better” than standard RAG. It is better when your data is inherently relational.
Use GraphRAG When:
- Questions require multi-hop reasoning (3+ hops).
- Your data relies heavily on interconnected entities.
- You need traceable, quantified reasoning (e.g., impact analysis).
- Your domain is inherently a graph (supply chains, finance, fraud detection).
Stick to Standard RAG When:
- Questions are single-fact lookups.
- Data is mostly unstructured narrative text (blogs, manuals).
- You need general document summarization.
The rule of thumb: If you can answer the question by finding the right paragraph, use RAG. If you need to traverse connections between entities to construct the answer, build a graph.
Try It Yourself ( working Code)
The entire PhoneGraph project is open-source, requires no cloud API keys, and runs locally.
Streamlit Snippet :

You can clone the repo, spin up Memgraph, and start querying your own local LLM via Ollama to see the difference between RAG and GraphRAG side-by-side.
⚖️ Company names used under nominative fair use. Data from USGS, SEC EDGAR, UN Comtrade. Price impacts are modeled estimates, not company projections.
GraphRAG RAG Knowledge Graph Supply Chain Memgraph LangChain Artificial Intelligence
For more technical deep dives:
📝 @abyakod on Medium · 💼 LinkedIn · 🐙 GitHub
메타데이터
- post_id
- 6f6e66e1a0bb
- slug
- graphrag-finds-the-connections-your-rag-system-doesnt-know-are-missing-6f6e66e1a0bb
- url
- https://medium.com/@abyakod/graphrag-finds-the-connections-your-rag-system-doesnt-know-are-missing-6f6e66e1a0bb
- canonical_url
- https://medium.com/@abyakod/graphrag-finds-the-connections-your-rag-system-doesnt-know-are-missing-6f6e66e1a0bb
- author_url
- https://medium.com/@abyakod
- status
- ok
- fetched_at
- 2026-06-12 18:14:10





