Lakebase 🐘 All That She Wants 🧠
The fraud PoC was lightning-fast until we tried to make it helpful.
Lakebase 🐘 All That She Wants 🧠
The fraud PoC was lightning-fast until we tried to make it helpful.
Built for the fraud department of an insurance company, this Databricks App allowed analysts to open suspicious claims, evaluate risk patterns, and decide the next move. At first, it showed only the essentials: claim status, risk score, and policyholder IDs. It was clean, boring, and sub-second fast.
Then came the feature creep. We added historical claims, payment timelines, provider networks, OCR evidence, and dashboard-style KPIs. Suddenly, opening a claim felt less like an operational triage workflow and more like asking Lakebase to drag the entire corporate archive through a keyhole. Latency spiked to a painful 8 seconds.
That’s where the real architectural lesson began. We realized that all that she wants — meaning, all that Lakebase actually wanted — was another cache hit.
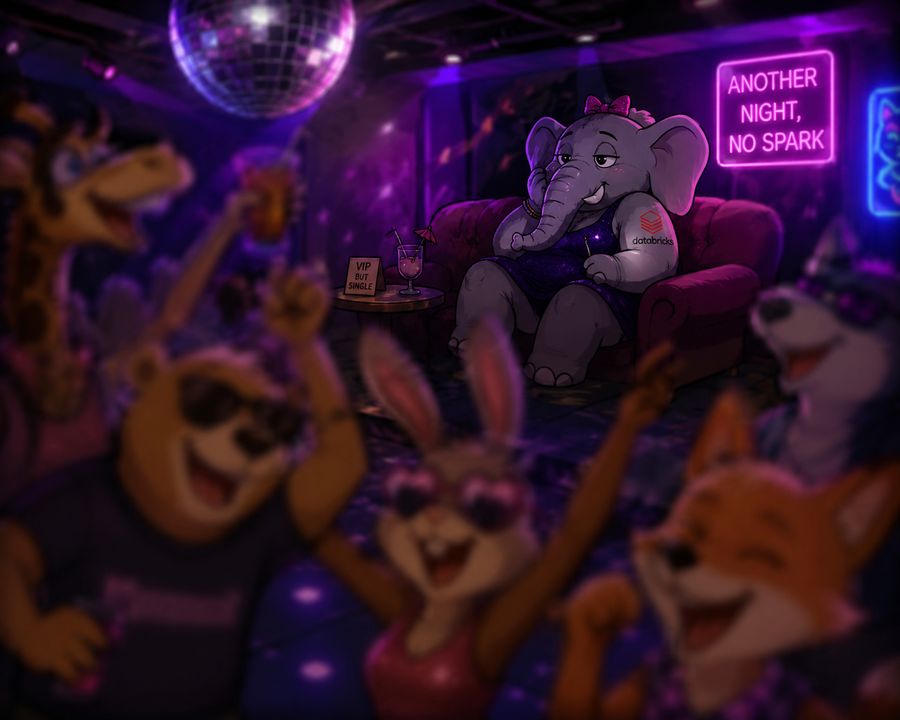
“She leads a lonely life” from “All that she wants” by Ace of Base
👻 The Problem: Waking a Haunted Forest
Insurance fraud doesn’t live in one clean table with a polite primary key; it hides in connections. The same repair shop appears too frequently; the same bank account receives payments across unrelated claims; a single provider has a suspicious talent for attracting accidents.
To capture this, our initial design made every single analyst click trigger an exhaustive archaeological dig. The app scanned deep JSON payloads, traversed live graph neighbors, and calculated historical aggregations on the fly.
Instead of a clean, high-concurrency operational path, we created a haunted forest. The database was constantly missing caches because every query forced massive, unpredictable full-table reads. We were treating an access pattern problem as a generic data volume problem, completely ignoring what the engine was begging for.
🛠️ What We Tried vs. What Worked
To rescue our p95 latency and win back the analysts, we had to systematically decouple operational speed from historical depth. We shifted our engineering approach across three core areas to give Lakebase exactly what “she” wanted.
1. Lakebase for Current State, Delta for Long Memory
We stopped forcing Lakebase to carry the weight of the entire enterprise archive. We split the backend into two distinct operational layers:
- Lakebase (The Hot Path): Stores the immediate, high-concurrency state needed for triage (active claims, current risk scores, assignment routing, and compact metadata summaries).
- Delta Lake (The Archive): Retains heavy historical timelines, full raw OCR outputs, and deep multi-year logs.
The application now loads the Lakebase layer instantly. If an analyst actually needs to investigate an old payment ledger or raw document evidence, they click an “Expand Details” button, fetching it on demand from Delta.
2. Evicting JSONB Treasure Hunts
Fraud evidence is messy and unpredictable, so we initially dumped everything into a flexible JSONB payload column. It worked great in development, but the triage queue frequently filtered on these embedded fields.
What we tried:
WHERE evidence_payload->>'claim_type' = 'AUTO'
  AND evidence_payload->>'provider_risk' = 'HIGH';
This forced Lakebase to parse text blocks line-by-line during every filter scan.
What worked: We promoted hot triage metrics directly out of the JSON into dedicated, structured, indexed columns.
WHERE claim_type = 'AUTO'
  AND provider_risk_band = 'HIGH';
👍 Rule of thumb: If analysts filter by it, sort by it, or route by it, it earns a concrete column. Keep JSON strictly for deep, passive payloads.
3. Starving the Analytical Raccoons
We mistakenly let analytics sneak into our operational path by trying to compute portfolio trends live on the triage screen.
What we tried:
SELECT provider_id, COUNT(*) AS claim_count, AVG(risk_score) AS avg_risk
FROM historical_claims
WHERE claim_date >= NOW() - INTERVAL '180 days'
GROUP BY provider_id;
Running this live multi-table aggregation across hundreds of thousands of historical rows on every single click destroyed database cache performance.
What worked: We moved graph traversal and historical analytical aggregations completely out of the click-path. Heavy provider rings and suspicious identity clusters are now computed asynchronously downstream via GraphFrames and written to a lean summary table:
SELECT recent_claim_count, provider_risk_band
FROM provider_summary_current
WHERE provider_id = :provider_id;
Our p95 latency dropped from 8.2 seconds down to 180ms.
😲 One Honest Caveat: The Price of Scale-to-Zero
Because Lakebase fits natively into modern cloud architectures, its scale-to-zero capability is highly appealing. For development and testing, letting the database hibernate during idle hours is a fantastic cost saver.
However, in a production operational environment, this economy introduces a sharp caveat: the cold-start penalty.
When the first fraud analyst logged in at 7:30 AM, their very first queue click took nearly 15 seconds while the decoupled compute layer provisioned and spun back up. For critical line-of-business applications, a “cold first impression” can tank user trust.
To mitigate this, we had to implement a scheduled pre-warming script at 7:15 AM to ensure the core operational working set was awake and warm before the team arrived. If your application demands sub-second readiness, you must actively manage scale-to-zero boundaries.
📝 Takeaways for the Hot Path
To build reliable, ultra-fast applications on Lakebase, remember that the engine thrives on predictable, repeatable operational workflows. It wants cache hits, not massive data-archaeology expeditions.
- Triage vs. Investigation: Keep the initial payload down to a snack. Let the analyst request the full buffet on a second click.
- Precompute Aggregations: Don’t turn operational screens into live dashboards. If it requires a
GROUP BYacross months of history, compute it asynchronously. - Clone the Crime Scene: Use Lakebase branching to safely test schema additions and index impacts in isolated preview environments without degrading the live app performance.
Lakebase was never struggling with the scale of our fraud data; it was struggling with our haunted questions. Stop throwing the entire archive at every click, and your operational apps will fly.

Wouldn’t it be nice if every disco toilet door came with better architecture advice than half the production reviews?
메타데이터
- post_id
- e8bf17e3efe8
- slug
- lakebase-all-that-she-wants-e8bf17e3efe8
- url
- https://medium.com/towards-data-engineering/lakebase-all-that-she-wants-e8bf17e3efe8
- canonical_url
- https://medium.com/towards-data-engineering/lakebase-all-that-she-wants-e8bf17e3efe8
- author_url
- https://medium.com/@angel.alvarez.pascua
- status
- ok
- fetched_at
- 2026-06-24 16:30:55